pegainfer
App Listed
Pure Rust + CUDA LLM inference engine — no PyTorch, OpenAI-compatible, serves Qwen3 to Kimi-K2
- Downloads
- 6
- Dependents
- Not applicable
- Stars
- 738
- Forks
- 120
- Contributors
- 40
- Commits
- 943
- Latest release
About
Quickstart · Performance · Models · Architecture · API · Development
PegaInfer serves LLMs through an OpenAI-compatible API. Each model owns its scheduler, state, and kernels; serving and KV infrastructure are shared. No PyTorch or Python runtime.
Quickstart
Prebuilt binary · Qwen3 on Linux
The Qwen3-only release bundles CUDA 13 and cuBLAS. It requires Linux x86_64, an NVIDIA GPU with compute capability 8.x–12.x, driver 580+, glibc 2.35+, and OpenSSL 3. Model weights are downloaded separately.
curl -fsSL https://raw.githubusercontent.com/pegainfer-project/pegainfer/main/install.sh | bash
Download Qwen3-4B into models/Qwen3-4B, then start the server:
pegainfer --model-path models/Qwen3-4B
The server listens on port 8000. If the command is not on your shell's path:
export PATH="$HOME/.local/bin:$PATH"
The installer selects the latest release by default. PEGAINFER_VERSION selects an exact version; see releases.
Read the full README
Build from source
Use the Rust toolchain pinned in rust-toolchain.toml, a CUDA Toolkit with nvcc and cuBLAS, and a compatible NVIDIA driver. The default Qwen3 build needs no Python. Its driver floor is R545 / CUDA 12.3; newer toolkits and model-specific kernels can require a newer driver.
From the repository root, with the checkpoint downloaded:
export CUDA_HOME=/usr/local/cuda
cargo run --release -- --model-path models/Qwen3-4B
Always use --release for GPU builds. The server entrypoint is pegainfer-server; model crates contain the model implementation and diagnostics.
Feature builds and environment options
Qwen3.5 uses Triton AOT kernels, requiring Python and Triton at build time:
uv venv
uv pip install triton
export PEGAINFER_TRITON_PYTHON=.venv/bin/python
cargo run --release --features qwen35 -- --model-path models/Qwen3.5-4B
| Variable | Purpose |
|---|---|
CUDA_HOME | CUDA Toolkit location; defaults to /usr/local/cuda |
PEGAINFER_CUDA_SM | Target GPU architecture when it cannot be detected, e.g. 120 |
PEGAINFER_TRITON_PYTHON | Python interpreter for Qwen3.5 Triton AOT compilation |
PEGAINFER_QWEN35_GDN_AOT_BUNDLE | Build-time FlashInfer GDN candidate directory; serving requires explicit backend selection |
PEGAINFER_TILELANG_PYTHON | Python interpreter for K3 TileLang kernel generation |
Qwen3.5 defaults to Triton even when a FlashInfer GDN candidate is linked. Explicit --qwen35-gdn-backend flashinfer-candidate selection requires SM120/Hv32/TP1 and fails on unsupported or unavailable candidates. Generation and production gates are described in the candidate README.
Other model lines have their own hardware and build requirements; follow the model guides below. Run cargo run --release -- --help for the compiled-in CLI.
Windows source builds
$env:CUDA_PATH = "C:\Program Files\NVIDIA GPU Computing Toolkit\CUDA\v12.x"
cargo run --release -p pegainfer-server -- --model-path models/Qwen3-4B

# Qwen3.5 additionally needs Triton at build time
uv venv .venv --python 3.12
uv pip install "triton-windows<3.7"
$env:PEGAINFER_TRITON_PYTHON = ".venv\Scripts\python.exe"
cargo run --release --features qwen35 -- --model-path models/Qwen3.5-4B
Performance
Selected serving measurements across dense, hybrid-attention, and MoE models. Each panel uses its own hardware, workload, and scale; the linked reports preserve the benchmark conditions.
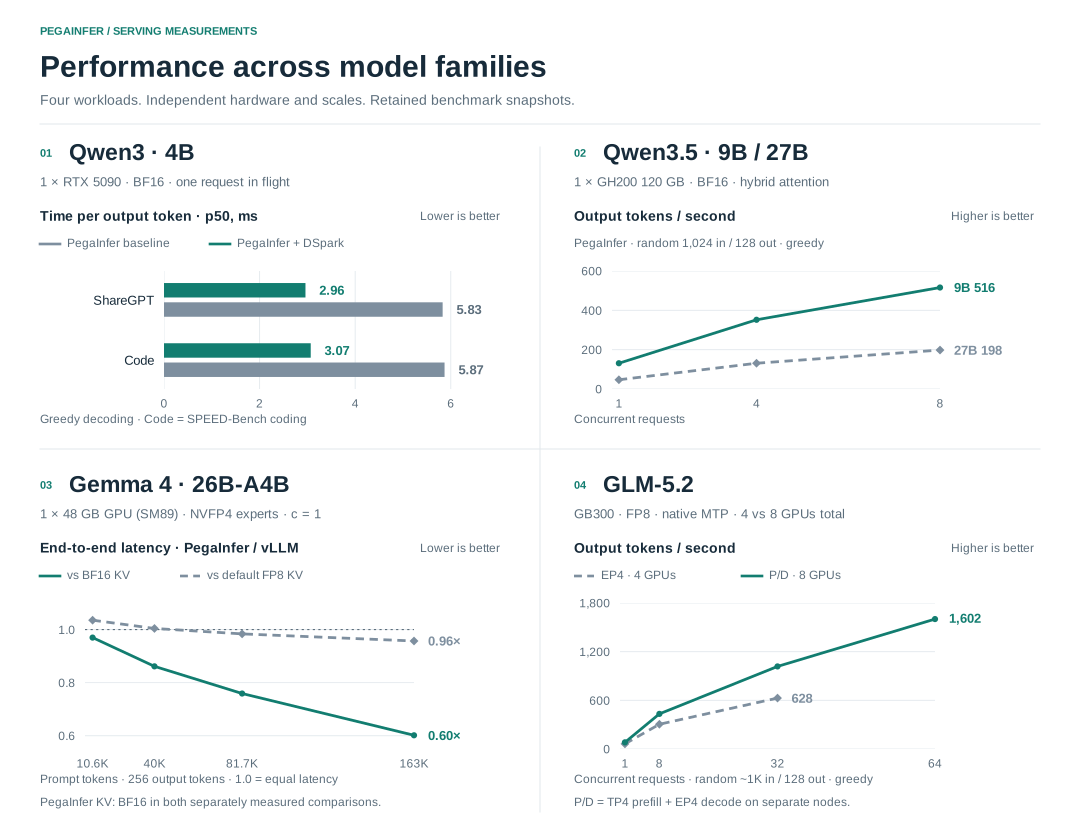
| Panel | Measurement and source |
|---|---|
| Qwen3 · 4B | DSpark vs PegaInfer baseline, single-request greedy decoding on ShareGPT and SPEED-Bench coding. |
| Qwen3.5 · 9B / 27B | GH200 concurrency sweep, revision ffb959c4, random 1,024-token prompts and 128-token outputs. |
| Gemma 4 · 26B-A4B | Four-round long-context report. Ratios use reported median end-to-end latencies; PegaInfer uses BF16 KV in both comparisons. The BF16 and default-FP8 vLLM comparisons were measured separately using PegaInfer revisions e7a41975 and ea02a9f7, respectively. |
| GLM-5.2 | Native MTP serving sweep: co-located EP4 uses 4 GPUs; disaggregated TP4 prefill + EP4 decode uses 8 GPUs total. |
Qwen3 serving footprint and additional measurements
Qwen3-4B on one RTX 5090, BF16, TP1: PegaInfer 70888b2 vs vLLM 0.24.0, loaded and serving the same model. PegaInfer is one process; the vLLM figure sums its process tree. This is a separate snapshot from the DSpark panel above.
| Metric | PegaInfer | vLLM 0.24.0 |
|---|---|---|
| Resident memory, loaded and idle | 771 MB | 3814 MB |
| Startup to HTTP ready, cold | 2.99 s | 70.0 s |
| Startup, warm compile cache | ~3.0 s | 32.7 s |
The Qwen3 serving report also covers the 8B model, warm-prefix TTFT, host-tier restore, and the serving sweep against vLLM. Further reports cover DSpark vs matched DFlash, DFlash serving, and Gemma 4 12B long-context performance.
Supported Models
Only qwen3 is enabled by default, including in the prebuilt binary. Build other lines with --features <feature>. At launch, --model-path selects a checkpoint and its config.json identifies the model family.
| Model line | Attention / experts | Cargo feature | Serving scope and guide |
|---|---|---|---|
| Qwen3 · dense 0.6B to 32B | Full attention, GQA | qwen3 · default | Greedy + sampling, tensor parallel, prefix cache, KV offload; DFlash / DSpark on 4B. Model page |
| Qwen3.5 · dense 0.8B to 27B | Gated DeltaNet + full attention | qwen35 | Text-only BF16; build-time Triton. Qwen3.8-27B rides the same feature. Model page · Qwen3.8 support record |
| Gemma 4 · 12B and 26B-A4B | Sliding-window + global attention; NVFP4 routed experts on 26B | gemma4 | Text-only, batched decode and optional chunked prefill; the dense sizes also run at tensor parallel 2, one rank per device. Model page |
| DeepSeek-V2-Lite | MLA + MoE | deepseek-v2-lite | 2-GPU EP2 correctness path. Status and limits |
| Kimi-K2 / K2.5 | MLA + MoE, Marlin INT4 | kimi-k2 | 8-GPU expert parallelism. Model roadmap |
| GLM-5.2 | Sparse MLA + MoE, FP8 | glm52 | Blackwell; EP decode, TP4 prefill, native MTP speculative decoding, P/D disaggregation. Bring-up. Model page |
| Kimi-K3 | KDA + MLA, latent MoE, MXFP4 | k3 | Text-only, Blackwell, EP and DSpark. Bring-up. Model guide |
Capabilities and maturity differ by model. Quantized formats are model-specific; the Qwen paths listed here use BF16. DeepSeek-V2-Lite's retained correctness and benchmark gates are documented separately from production readiness.
Architecture
Share the infrastructure; let each model own its execution. The frontend submits requests through an engine contract. Model schedulers decide how to batch work, manage state, and execute kernels on their target hardware.
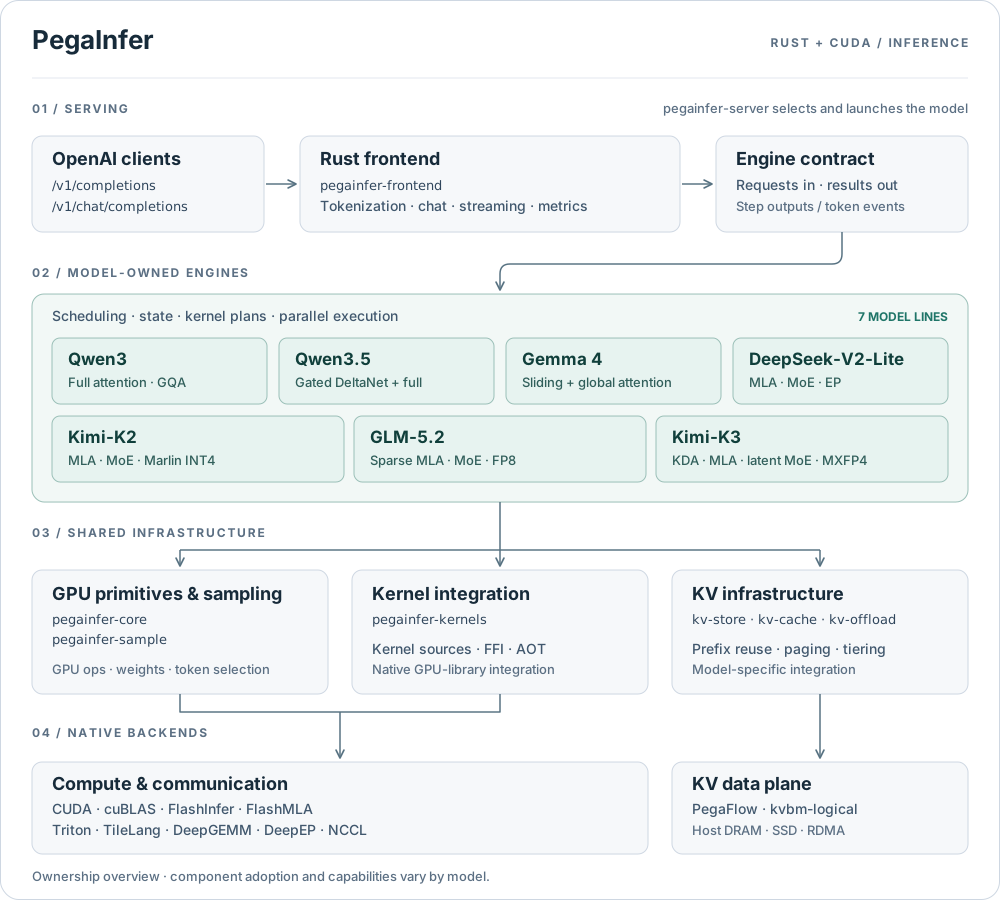
The diagram shows ownership layers. Model engines select the components they need; cache integration and parallel strategies vary by model.
| Boundary | Responsibility |
|---|---|
pegainfer-server | Detect the model, validate its CLI, and launch the selected engine |
pegainfer-frontend | OpenAI protocol, tokenization, chat templates, streaming, metrics, and engine contracts; uses vLLM's Rust frontend crates |
| Per-model crates | Weights, scheduler, prefill/decode execution, state layout, and parallel strategy |
pegainfer-core / pegainfer-sample | Shared GPU and weight-loading primitives; batched token selection |
pegainfer-kernels | Native kernels, FFI, GPU-library integration, and feature-gated AOT builds |
| KV infrastructure | pegainfer-kv-store and the existing pegainfer-kv-cache / pegainfer-kv-offload paths; PegaFlow supplies host, SSD, and RDMA storage/transfer |
The step-based contract and legacy EngineHandle contract currently coexist. See the frontend architecture for the migration boundary and design direction for the reasoning behind model-owned engines.
API
Point an OpenAI-compatible client at http://localhost:8000/v1. Both /v1/completions and /v1/chat/completions support streaming.
curl -s http://localhost:8000/v1/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"models/Qwen3-4B","prompt":"The capital of France is","max_tokens":32}'

curl -N http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"models/Qwen3-4B","messages":[{"role":"user","content":"Write a haiku about Rust."}],"max_tokens":64,"stream":true}'
The model guides document supported sampling fields and model-specific limits. Documentation covers the serving interface; metrics and dashboards cover observability.
Development
scripts/setup_dev.sh prepares a fresh NVIDIA Ubuntu host using the pinned Rust toolchain and build dependencies. CUDA must already be installed. Container development is documented in docker/README.md.
bash scripts/setup_dev.sh
Run checks in release mode; accuracy and integration tests need a GPU and model weights:
cargo test --release --workspace --lib

PEGAINFER_TEST_MODEL_PATH=models/Qwen3-4B \
  cargo test --release -p pegainfer-qwen3 --test hf_golden_gate

PEGAINFER_TEST_MODEL_PATH=models/Qwen3.5-4B \
  cargo test --release -p pegainfer-qwen35 --features qwen35 --lib executor::hf_golden_gate -- --test-threads=1

PEGAINFER_TEST_MODEL_PATH=models/Qwen3.5-4B \
  cargo test --release -p pegainfer-qwen35 --features qwen35 --lib scheduler::e2e_tests -- --test-threads=1
Browse the engineering docs index for model-specific gates, profiling, and benchmark methodology.
The getting started guide and model pages live at pegainfer.org. Read the engineering stories at pegainfer.org/blog: weight loading, speculative decoding, CUDA graph export, and prefill/decode overlap.
License
Apache-2.0. See NOTICE for third-party attributions. The Dynamo-derived kvbm/kvbm-logical crate retains its original Apache-2.0 headers and NVIDIA Dynamo notice.
Compatibility
- License
- Apache-2.0
- Crate facts
- Not measured
- Runs on, Native code and Python bindings read crates on crates.io. This entry lists no crate.
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Pure Rust + CUDA LLM inference engine — no PyTorch, OpenAI-compatible, serves Qwen3 to Kimi-K2 |
6 binary downloads per release | Not applicable | 738 | Not measured | Not measured | Apache-2.0 | |
|
ort Featured
A safe Rust wrapper for ONNX Runtime 1.31 - Optimize and accelerate machine learning inference & training Also in Run and serve models. |
3,902,768 downloads over 30 days | 694 | 2,611 | 2.0.0-rc.15 | CUDA, WebGPU, ROCm | Binds native code: onnxruntime, ort-sys. Build uses a native toolchain: pkg-config (feature pkg-config) | Apache-2.0 OR MIT |
|
llama-gguf Listed
A high-performance Rust implementation of llama.cpp - LLM inference engine with full GGUF support Also in Build LLM apps and agents. |
1,787 downloads over 30 days | 3 | 21 | 0.14.0 | CUDA, Metal, Vulkan | Binds native code: hailort-sys (feature hailo), libsqlite3-sys (feature rag-sqlite) | Apache-2.0 OR MIT |
|
oxionnx Listed
Pure Rust ONNX inference engine — zero C/C++ dependencies Also in Run and serve models. |
550 downloads over 30 days | 24 | 20 | 0.1.7 | CUDA, WebGPU | No native code found | Apache-2.0 |
|
Inference server for LLMs, speech and embeddings: OpenAI-compatible routes with streaming, plus speech synthesis (TTS) and transcription (ASR). Serves Llama, Mistral, Qwen, Mamba2, MLA+MoE and hybrid models from SafeTensors, AWQ, GPTQ and GGUF. Also in Build LLM apps and agents. |
8 binary downloads per release | Not applicable | 7 | 0.7.1 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
oxibonsai Listed
Pure Rust 1-bit LLM inference engine for PrismML Bonsai models — umbrella crate Also in Build LLM apps and agents. |
1 downloads over 30 days | 0 | 137 | 0.2.3 | CUDA, Metal | No native code found | Apache-2.0 |
|
furnace New
Fast, unified, Rust-native, Axum-compatible inference endpoints and nervous system for tensor models and LLMs: KServe / Triton and OpenAI APIs from one pure-Rust server Also in Build LLM apps and agents. |
241 downloads over 30 days | 0 | 66 | 0.16.2 | CUDA, WebGPU, Metal | No native code found | MIT |
All projects in Build LLM apps and agentsAll projects in Run and serve models
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- The check holds no value for Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days. A gate that lacks its signal does not pass.
What else the check found
- The last activity is on 8 Nov 2026, 1 day ago. The rules expect an update within 365 days. Dormancy rule
Not measured: First release, Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days.
Exact rules: Listed, Featured app. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: app: E = 365 daysdormancy: last activity 2026-11-08, 1 days ago, E = 365: activefeatured: not featured: unknown homebrew_on_request_365d, repology_families, docker_pull_growth_90dlisted: listed: no archive, new or featured rule applies
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources4 sources
- Description: the GitHub repository description
- GitHub releases, fetched
- GitHub repository, fetched
- GitHub contributors, fetched
Adoption6 binary downloads per release4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | Not measured | Yes | ||
| New dependents (365 days) | Not measured | Yes | ||
| Peak active dependents | Not measured | Yes | ||
| Active dependents as a share of the peak | Not measured | Yes | ||
| Binary downloads per release | 6 | GitHub releases | Yes |
MaintenanceLatest human commit: 1 day ago7 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-08 | GitHub repository | Yes | |
| Latest release | 2026-08-26 | GitHub releases | Yes | |
| First release | Not measured | Yes | ||
| Latest version | Not measured | Yes | ||
| Days the oldest outside issue waits for a reply | 39 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 18 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | Not measured | Yes | ||
| Published docs | Not measured | Yes | ||
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityNot measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | Not measured | Yes | ||
| RustSec unmaintained advisory | Not measured | Yes | ||
| Deprecation notice | Not measured | Yes | ||
| Deprecated requirement | Not measured | Yes |
Distribution12 binary downloads over the last 3 releases10 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | Not measured | Yes | ||
| Downloads over 30 days | Not measured | Yes | ||
| Binary downloads over the last 3 releases | 12 | GitHub releases | Yes | |
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | Not measured | Yes | ||
| Every version 0.0.x | Not measured | Yes | ||
| Every version yanked | Not measured | Yes | ||
| Crate deleted from crates.io | Not measured | Yes |
Repository738 stars, 120 forks, 40 contributors, 943 commits. Stars alone never qualify a project.1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 738 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 120 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 40 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 943 | GitHub repository | No | |
| Repository's main crate left out of the entry | Not measured | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | Apache-2.0 | GitHub repository | No | |
| Runs on, from listed crates and their direct dependencies | Not measured | No | ||
| What shows each backend | Not measured | No | ||
| Native code, from listed crates and their dependencies | Not measured | No | ||
| Python bindings, from direct dependencies of listed crates | Not measured | No | ||
| Crates that depend on a listed crate directly | Not measured | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.