mistralrs
App Featured
Fast, flexible LLM inference.
- Downloads
- 1,498
- Dependents
- Not applicable
- Stars
- 7,819
- Forks
- 763
- Contributors
- 101
- Commits
- 3,514
- Latest release
- 0.8.1 ·
About
| Documentation | Quickstart | Supported models | Rust SDK | Python SDK | Discord |
Read the full README
Latest
- LFM3 family: text with LFM3, image and video with LFM3-VL, speech input and output with LFM3-Audio, and combined text, image, video, and audio with LFM3-Omni. Includes ISQ, paged attention, and chunked prefill; text/VL also support GGUF. Model notes
- v0.9.5: paged attention is now the default on supported Metal models, with automatic memory planning across the CLI and SDKs. Existing memory and device-mapping options have changed; see the upgrade guide. This release also adds Qwen3.8-Flash-Next and CUDA 13.4 source builds.
- Muse Glimmer 30B: native text, image, and video inference with ATEM tool calling, reasoning controls, LoRA, ISQ/UQFF, and companion-projector GGUF loading. Model notes
- GGUF loading: load a local file with
-f, or select a published artifact with--quant. Tokenizer, configuration, and multimodal projector files are discovered when the available metadata identifies them unambiguously. Guide - OpenAI-compatible Skills: upload
/v1/skillsbundles and reference them from Responses requests for reusable procedures, helper scripts, and local data. Guide - OpenAI-compatible file inputs: upload
/v1/files, attach Responsesinput_fileor Chatfileparts, and mount request files into shell/code sessions. Guide - DiffusionGemma: block-diffusion text generation. Fully integrated: paged attention, prefix caching, ISQ, multimodal, and tool calling. Guide
- Anthropic Messages API:
mistralrs servenow exposes Anthropic-compatible/v1/messagesand/v1/messages/count_tokensendpoints alongside the OpenAI-compatible/v1API. Guide - v0.8.2 CUDA performance: paged-attention and MoE optimizations deliver strong results on GB10, B200, and H100 SXM. Benchmarks
- Agentic runtime: web search, local Python code execution, shell execution, OpenAI-compatible Skills, session management, and custom tool hooks. Guide
- Gemma 4: full multimodal: text, image, video, and audio input. Supported models | Video setup
Benchmarks
v0.8.2 CUDA benchmarks
Mean tokens per second across prompt lengths and decode depths from 128 to 16384 tokens. Decode uses 256 generated tokens. See the full v0.8.2 report for commands, model revisions, host metadata, and appendix tables.
Q8 prefill TPS: mistral.rs UQFF q8 vs llama.cpp GGUF Q8_0
| Model | Hardware | mistral.rs | llama.cpp |
|---|---|---|---|
| Gemma 4 E4B | GB10 | 7395.7 | 3973.7 |
| Gemma 4 E4B | B200 | 27705.6 | 11992.4 |
| Gemma 4 E4B | H100 SXM | 26220.6 | 11702.1 |
| Gemma 4 26B-A4B | GB10 | 2947.0 | 2178.5 |
| Gemma 4 26B-A4B | B200 | 12725.3 | 8503.4 |
| Gemma 4 26B-A4B | H100 SXM | 12362.3 | 8055.1 |
Q8 decode TPS: mistral.rs UQFF q8 vs llama.cpp GGUF Q8_0
| Model | Hardware | mistral.rs | llama.cpp |
|---|---|---|---|
| Gemma 4 E4B | GB10 | 44.1 | 40.5 |
| Gemma 4 E4B | B200 | 241.4 | 194.4 |
| Gemma 4 E4B | H100 SXM | 223.1 | 183.0 |
| Gemma 4 26B-A4B | GB10 | 46.8 | 46.4 |
| Gemma 4 26B-A4B | B200 | 210.9 | 192.2 |
| Gemma 4 26B-A4B | H100 SXM | 199.8 | 183.9 |
BF16 prefill TPS: mistral.rs BF16 vs vLLM BF16
| Model | Hardware | mistral.rs | vLLM |
|---|---|---|---|
| Gemma 4 E4B | GB10 | 5838.9 | 5812.9 |
| Gemma 4 E4B | B200 | 43547.8 | 39431.2 |
| Gemma 4 E4B | H100 SXM | 35852.2 | 39293.7 |
| Gemma 4 26B-A4B | GB10 | 592.2 | 3878.6 |
| Gemma 4 26B-A4B | B200 | 3467.3 | 28532.8 |
| Gemma 4 26B-A4B | H100 SXM | 2766.0 | 26295.9 |
BF16 decode TPS: mistral.rs BF16 vs vLLM BF16
| Model | Hardware | mistral.rs | vLLM |
|---|---|---|---|
| Gemma 4 E4B | GB10 | 25.1 | 18.8 |
| Gemma 4 E4B | B200 | 202.6 | 196.2 |
| Gemma 4 E4B | H100 SXM | 174.4 | 153.0 |
| Gemma 4 26B-A4B | GB10 | 26.9 | 23.2 |
| Gemma 4 26B-A4B | B200 | 159.6 | 220.2 |
| Gemma 4 26B-A4B | H100 SXM | 138.7 | 148.0 |
Why mistral.rs?
- Automatic model loading: Architecture, weight format, and chat template are detected for supported Hugging Face models and GGUF files, with flags available for explicit selection.
- True multimodality: Text, vision, video, and audio, speech generation, image generation, and embeddings in one engine.
- Quantization selection:
--quantselects a matching artifact from GGUF repositories. For other Hugging Face repositories, it uses a prebuilt UQFF when available and otherwise applies ISQ. Docs - Works with Claude Code and Codex: The same
mistralrs serveprocess exposes OpenAI-compatible/v1endpoints and Anthropic-compatible Messages endpoints, so coding agents run on your local model. Setup - Prometheus metrics:
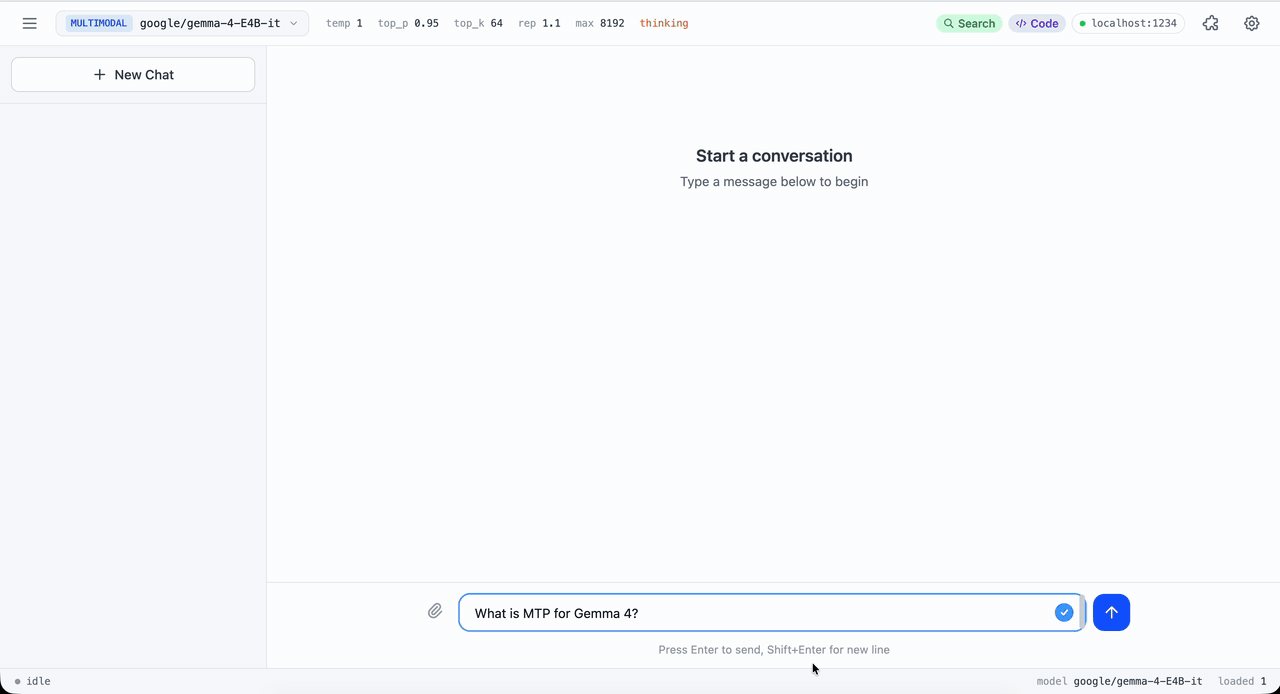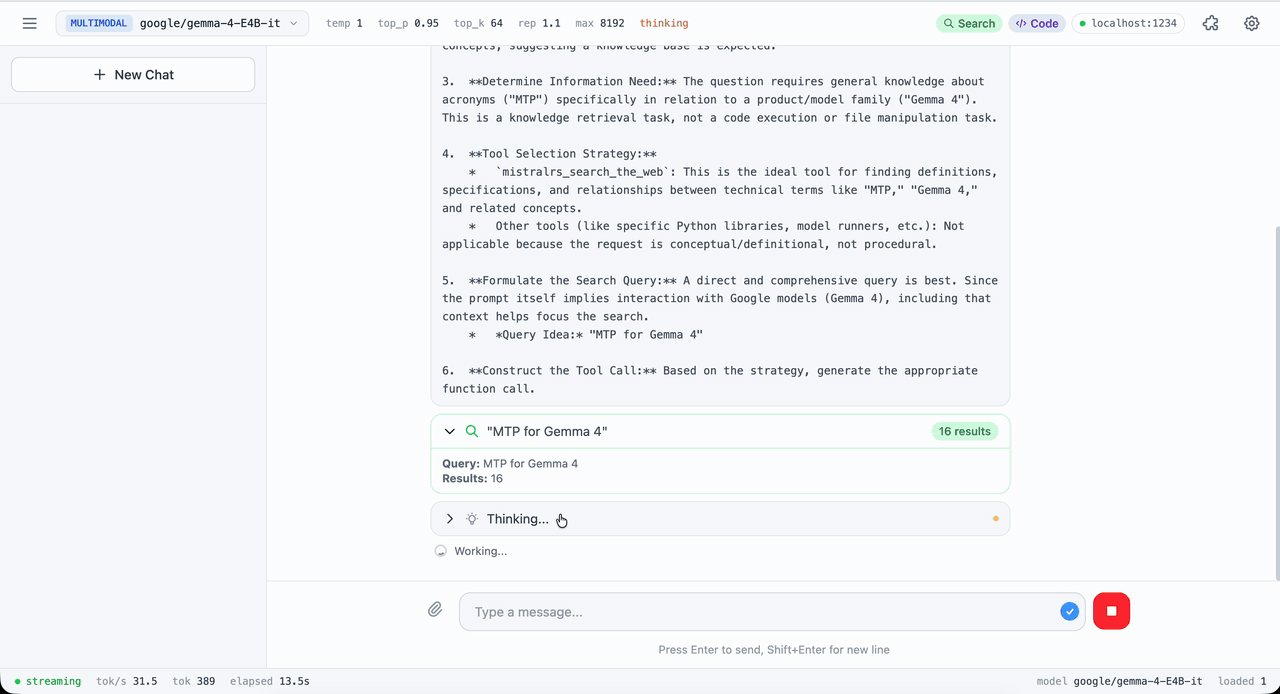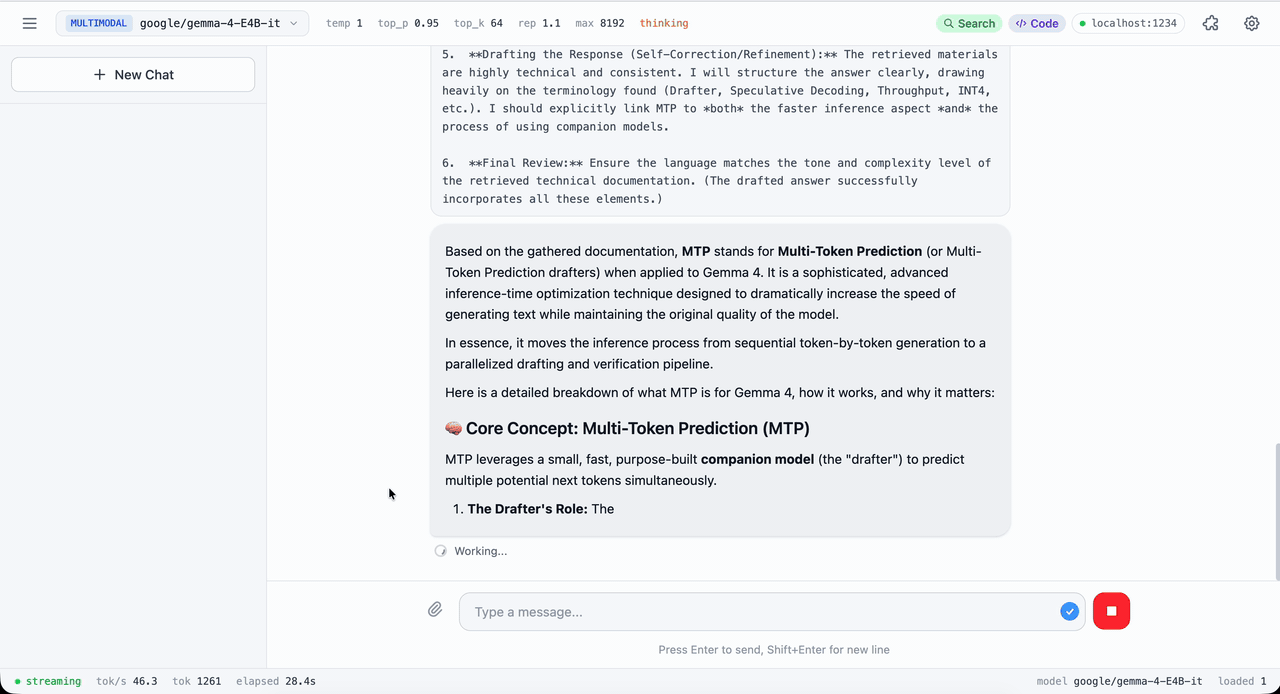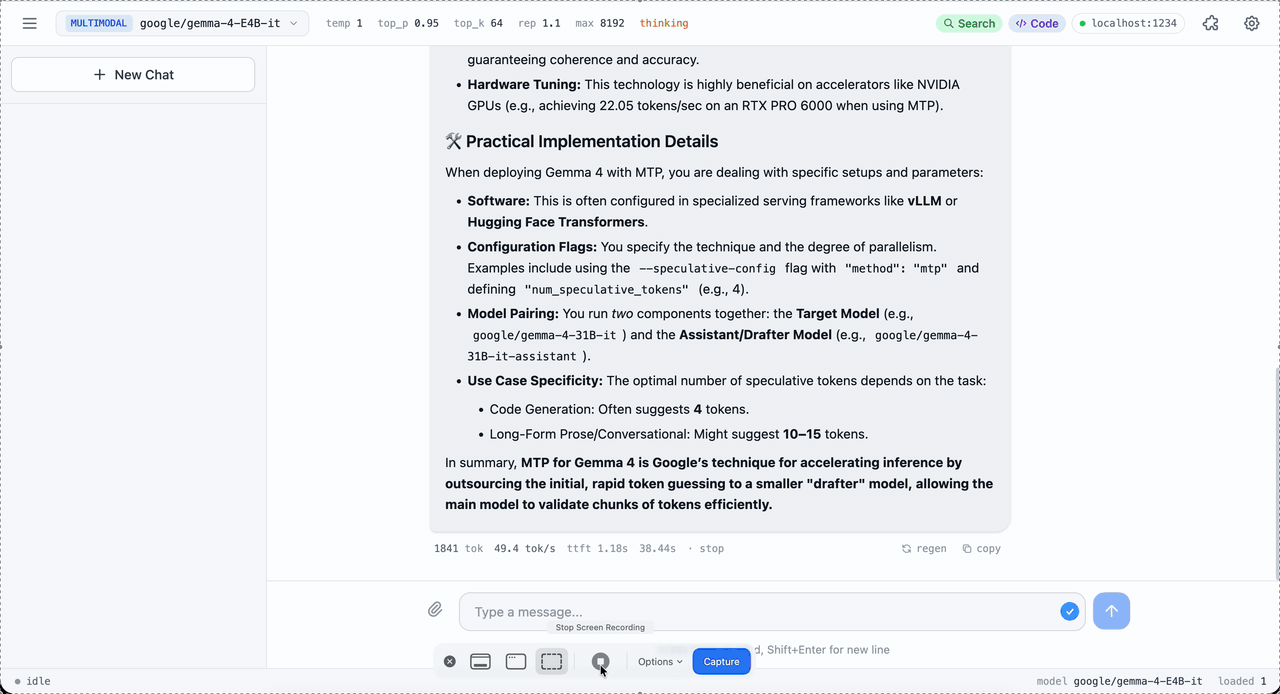
mistralrs serveexposes a/metricsendpoint in Prometheus format, recording per-request counts and latency labeled by method, route, and status. Docs - Built-in web UI: Served at
/uiby default. Shows reasoning, code execution, plots, and files inline. Edit any message and the new branch runs with its own Python state. Pass--no-uito disable. - Hardware-aware:
mistralrs tunerecommends quantization and device mapping from the model config and your detected hardware. - Flexible SDKs: Python package and Rust crate to build your projects.
- Native agentic support: built-in agentic loop with web search, local Python code execution, shell execution, OpenAI-compatible Skills, session management, and custom tool hooks.
Quick Start
Install
Run the command for your platform in a terminal, then follow the installer.
macOS / Linux:
curl -fsSL https://mistralrs.dev/install.sh | sh
Windows (PowerShell):
irm https://mistralrs.dev/install.ps1 | iex
When installation finishes, open a new terminal.
Chat in Your Browser
Start a model:
mistralrs serve -m Qwen/Qwen3-4B --quant 4
When the server is ready, open http://localhost:1234/ui and send a message. Keep the terminal open while chatting; press Ctrl+C to stop.
Quickstart | Installer options
UI Demo
Use with Claude Code or Codex
Serve a coding model, then point Claude Code or Codex at it to use it in your projects:
mistralrs serve -m Qwen/Qwen3-Coder-Next --quant 4
What Makes It Fast
Performance
- Continuous batching support by default on all devices.
- CUDA with FlashAttention V2/V3, Metal, and multi-GPU/distributed inference
- PagedAttention for high throughput continuous batching on CUDA or Apple Silicon, prefix caching (including multimodal)
Quantization (full docs)
- In-situ quantization (ISQ) for Hugging Face models
- GGUF (2-8 bit), GPTQ, AWQ, HQQ, FP8, BNB support
- ⭐ Per-layer topology: Fine-tune quantization per layer for optimal quality/speed
- ⭐ Auto-select fastest quant method for your hardware
Flexibility
- LoRA & X-LoRA with per-request LoRA selection and X-LoRA adapter mixing
- AnyMoE: Create mixture-of-experts on any base model
- Multiple models: Load/unload at runtime
Agentic Features
- Integrated tool calling with grammar enforcement and strict schema mode
- ⭐ Server-side agentic loop: auto-execute tools and feed results back
- ⭐ Python code execution: persistent Jupyter-like sessions with matplotlib capture and multimodal feedback
- ⭐ Shell execution: persistent command-line sessions with sandboxing and approval controls
- ⭐ OpenAI-compatible Skills: uploaded skill bundles for Responses API agents
- ⭐ OpenAI-compatible file inputs:
/v1/files, Responsesinput_file, Chatfile, and workdir mounts - ⭐ Web search integration with embedding-based ranking
- ⭐ Tool dispatch URL: POST tool calls to your own endpoint
- ⭐ MCP client: Connect to external tools via Process, HTTP, or WebSocket
- Python/Rust tool callbacks for custom execution
Supported Models
Text, multimodal, speech, image generation, and embedding models across 45+ architectures. The supported models reference is the single source of truth: it explains how to check whether your model's config.json is supported, lists every architecture with copy-paste run commands, and is generated directly from the engine's loader registry so it never drifts.
Supported models reference | Request a new model
Python SDK
pip install mistralrs
In-process inference from Python: load a model with Runner and send OpenAI-shaped requests, no server required. Accelerator-specific wheels (CUDA, Metal, MKL, Accelerate) are listed in the getting-started guide.
Get started | API reference | Examples
Rust SDK
cargo add mistralrs
Embed the engine in a Rust application with the high-level mistralrs crate.
Get started | docs.rs | Crate | Examples
Docker
Prebuilt CPU and CUDA images are published to GHCR. Pull commands, tags, and Kubernetes notes are in the Docker guide.
Documentation
For complete documentation, see the Documentation.
Quick Links:
- Quickstart - Install, first run, first serve
- Coding agents - Claude Code and Codex on a local model
- CLI Reference - All commands and options
- Anthropic Messages API - Anthropic-compatible Messages, streaming, tool use, and token counting
- HTTP API - OpenAI-compatible and Anthropic-compatible endpoints
- Quantization - ISQ, GGUF, GPTQ, and more
- Multi-GPU and Distributed - NCCL TP, P2P layer mapping, multi-node, and ring
- MCP Integration - MCP integration documentation
- Troubleshooting - Common issues and solutions
- Environment variables - Environment variables for configuration
Citation
If you use mistral.rs in your research, please cite:
@misc{mistralrs,
  author = {Buehler, Eric},
  title = {{mistral.rs}: Fast, flexible {LLM} inference},
  year = {2024},
  url = {https://github.com/EricLBuehler/mistral.rs}
}
Citation metadata is available in CITATION.cff.
Contributing
Contributions welcome! Please open an issue to discuss new features or report bugs. If you want to add a new model, please contact us via an issue and we can coordinate.
Credits
This project would not be possible without the excellent work at Candle. Thank you to all contributors!
mistral.rs is not affiliated with Mistral AI.
Back to Top
Compatibility
- Runs on
- CUDA, Metal
What shows it
- CUDA: mistralrs feature cuda, mistralrs-cli feature cuda, mistralrs-core feature cuda, mistralrs-paged-attn feature cuda, mistralrs-quant feature cuda, mistralrs-server-core feature cuda
- Metal: mistralrs feature metal, mistralrs-cli feature metal, mistralrs-core feature metal (dependency objc2-metal), mistralrs-paged-attn feature metal (dependency objc2-metal), mistralrs-quant feature metal (dependency objc2-metal), mistralrs-server-core feature metal
- Native code
- Optional
- Binds native code: accelerate-src (feature accelerate-src), intel-mkl-src (feature intel-mkl-src)
- Python bindings
- Has Python bindings
- mistralrs-core needs Python only with feature pyo3_macros
- mistralrs-mcp needs Python only with feature pyo3_macros
- License
- MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Fast, flexible LLM inference. Python bindings |
1,498 binary downloads per release | Not applicable | 7,819 | 0.8.1 | CUDA, Metal | Binds native code: accelerate-src (feature accelerate-src), intel-mkl-src (feature intel-mkl-src) | MIT |
|
ort Featured
A safe Rust wrapper for ONNX Runtime 1.31 - Optimize and accelerate machine learning inference & training Also in Run and serve models. |
3,902,768 downloads over 30 days | 694 | 2,611 | 2.0.0-rc.15 | CUDA, WebGPU, ROCm | Binds native code: onnxruntime, ort-sys. Build uses a native toolchain: pkg-config (feature pkg-config) | Apache-2.0 OR MIT |
|
llama-gguf Listed
A high-performance Rust implementation of llama.cpp - LLM inference engine with full GGUF support Also in Build LLM apps and agents. |
1,787 downloads over 30 days | 3 | 21 | 0.14.0 | CUDA, Metal, Vulkan | Binds native code: hailort-sys (feature hailo), libsqlite3-sys (feature rag-sqlite) | Apache-2.0 OR MIT |
|
A rust mlx server, ui, and model router for fast, dependency free inference on apple architecture Also in Build LLM apps and agents. |
23 binary downloads per release | Not applicable | 34 | Not measured | Not measured | MIT | |
|
cake Listed
Distributed LLM inference for mobile, desktop and server. Also in Run and serve models. |
22 downloads over 30 days | 0 | 3,131 | 0.1.0 | CUDA, Metal | No native code found | GPL-3.0 |
|
Inference server for LLMs, speech and embeddings: OpenAI-compatible routes with streaming, plus speech synthesis (TTS) and transcription (ASR). Serves Llama, Mistral, Qwen, Mamba2, MLA+MoE and hybrid models from SafeTensors, AWQ, GPTQ and GGUF. Also in Build LLM apps and agents. |
8 binary downloads per release | Not applicable | 7 | 0.7.1 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
Pure Rust + CUDA LLM inference engine — no PyTorch, OpenAI-compatible, serves Qwen3 to Kimi-K2 Also in Build LLM apps and agents. |
6 binary downloads per release | Not applicable | 738 | Not measured | Not measured | Apache-2.0 |
All projects in Build LLM apps and agentsAll projects in Run and serve models
Why FeaturedIt passes every Featured gate.
What it meets
- Its use signals read: binary downloads 4496, Homebrew unknown, Repology families unknown, Docker growth unknown. Featured needs 2 of these to reach their limits.
- It also passes the repository route, which counts as one use signal: 7,819 stars, 763 forks and 101 contributors. It needs 4,539 stars, 434 forks and 79 contributors together.
- The last activity is on 7 Nov 2026, 2 days ago. The rules expect an update within 365 days. Dormancy rule
Exact rules: Featured app. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: app: E = 365 daysdormancy: last activity 2026-11-07, 2 days ago, E = 365: activefeatured: featured: binary downloads 4496, Homebrew unknown, Repology families unknown, Docker growth unknown, repository route stars 7819 (needs 4539), forks 763 (needs 434), contributors 101 (needs 79)
Crates10 crates
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- GitHub releases, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption1,498 binary downloads per release4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | Not measured | Yes | ||
| New dependents (365 days) | Not measured | Yes | ||
| Peak active dependents | Not measured | Yes | ||
| Active dependents as a share of the peak | Not measured | Yes | ||
| Binary downloads per release | 1498 | GitHub releases | Yes |
MaintenanceLatest human commit: 2 days ago4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-07 | GitHub repository | Yes | |
| Latest release | 2026-10-19 | GitHub releases | Yes | |
| First release | 2026-01-27 | crates.io database dump | Yes | |
| Latest version | 0.8.1 | crates.io database dump | No | |
| Days the oldest outside issue waits for a reply | 124 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 11 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | No | |
| Published docs | Not measured | Yes | ||
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityNot measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | Not measured | Yes | ||
| RustSec unmaintained advisory | Not measured | Yes | ||
| Deprecation notice | Not measured | Yes | ||
| Deprecated requirement | Not measured | Yes |
Distribution5 releases, 33,044 downloads over 30 days6 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 5 | crates.io database dump | No | |
| Downloads over 30 days | 33044 | crates.io database dump | No | |
| Binary downloads over the last 3 releases | 4496 | GitHub releases | Yes | |
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | Not measured | Yes | ||
| Crate deleted from crates.io | Not measured | Yes |
Repository7,819 stars, 763 forks, 101 contributors, 3,514 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 7819 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 763 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 101 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 3514 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | CUDA, Metal | crates.io database dump | No | |
| What shows each backend | CUDA: mistralrs feature cuda, mistralrs-cli feature cuda, mistralrs-core feature cuda, mistralrs-paged-attn feature cuda, mistralrs-quant feature cuda, mistralrs-server-core feature cuda; Metal: mistralrs feature metal, mistralrs-cli feature metal, mistralrs-core feature metal (dependency objc2-metal), mistralrs-paged-attn feature metal (dependency objc2-metal), mistralrs-quant feature metal (dependency objc2-metal), mistralrs-server-core feature metal | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: accelerate-src (feature accelerate-src), intel-mkl-src (feature intel-mkl-src) | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | Has Python bindings: mistralrs-core needs Python only with feature pyo3_macros, mistralrs-mcp needs Python only with feature pyo3_macros | crates.io database dump | No | |
| Crates that depend on a listed crate directly | Not measured | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.