higgs
App Listed
A rust mlx server, ui, and model router for fast, dependency free inference on apple architecture
- Downloads
- 23
- Dependents
- Not applicable
- Stars
- 34
- Forks
- 6
- Contributors
- 6
- Commits
- 467
- Latest release
About
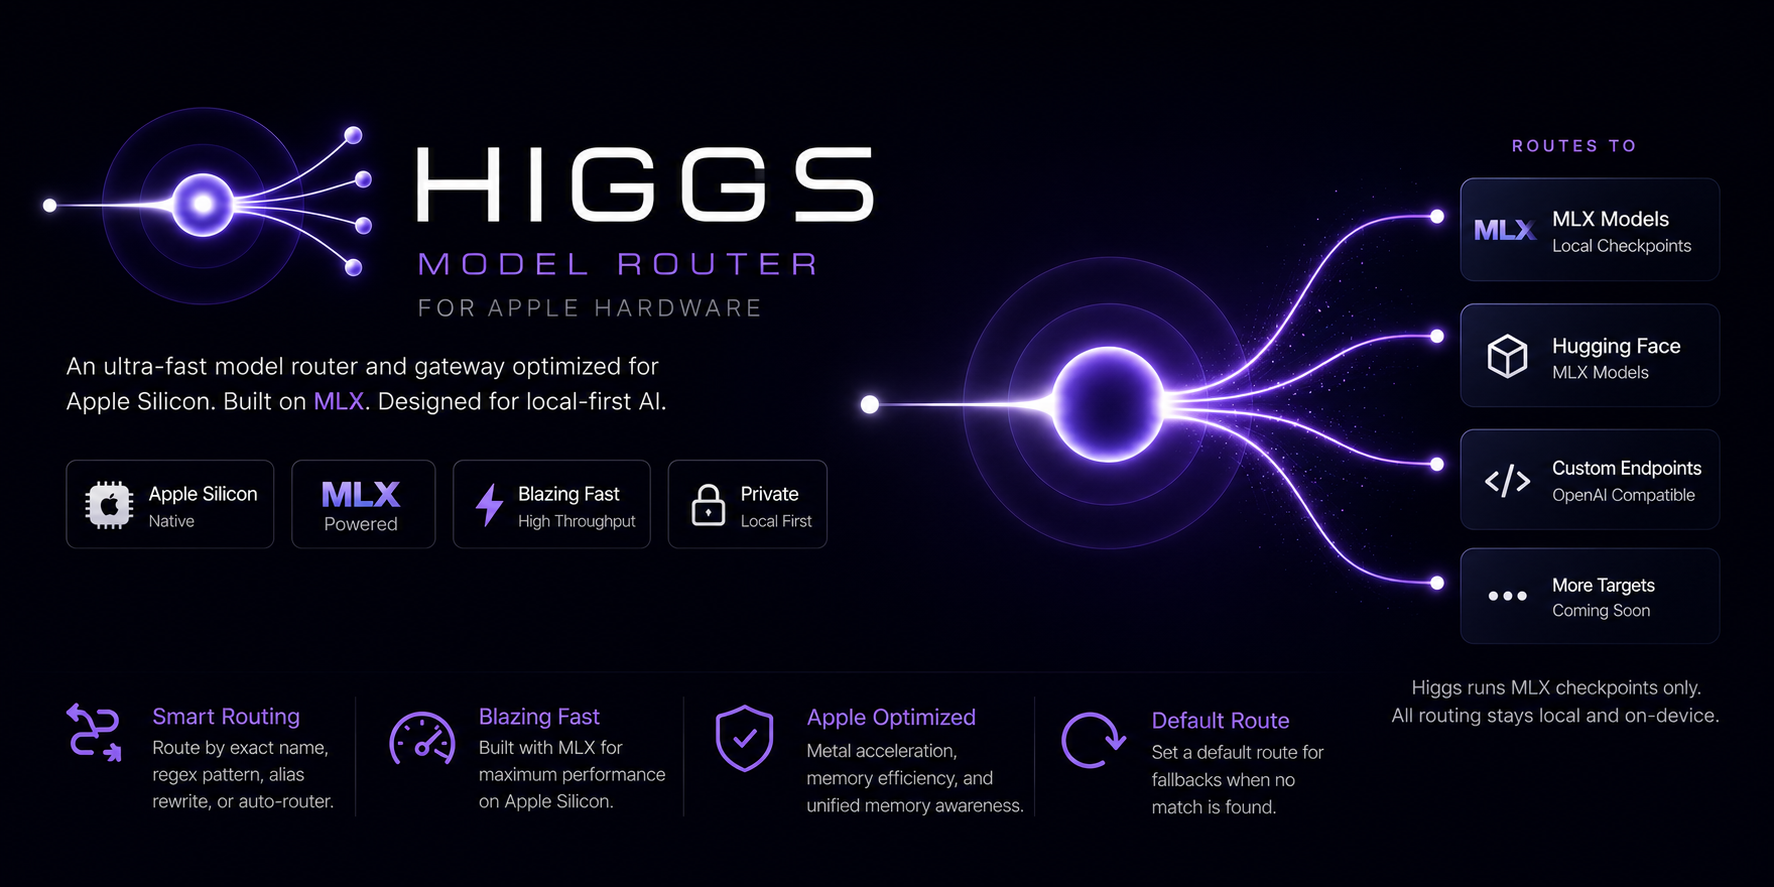
Local LLM inference server for Apple Silicon, with a router, an OpenAI and Anthropic compatible API, and a desktop console that shows how fast each local request ran.
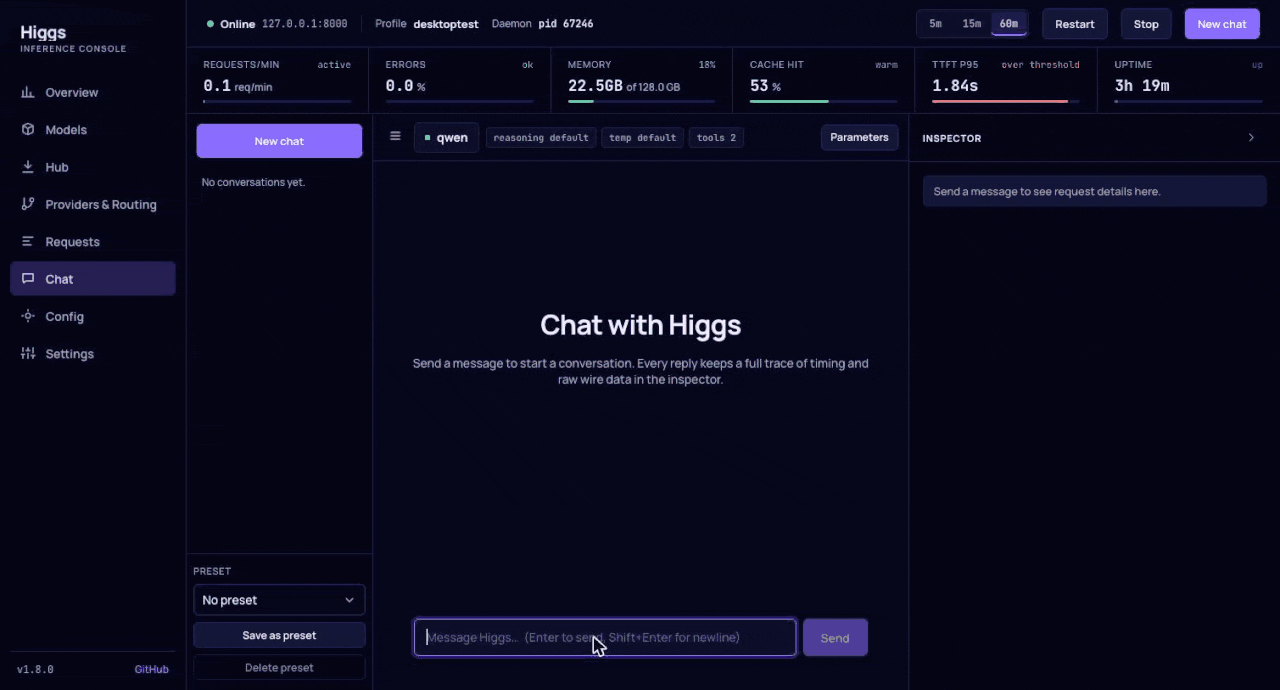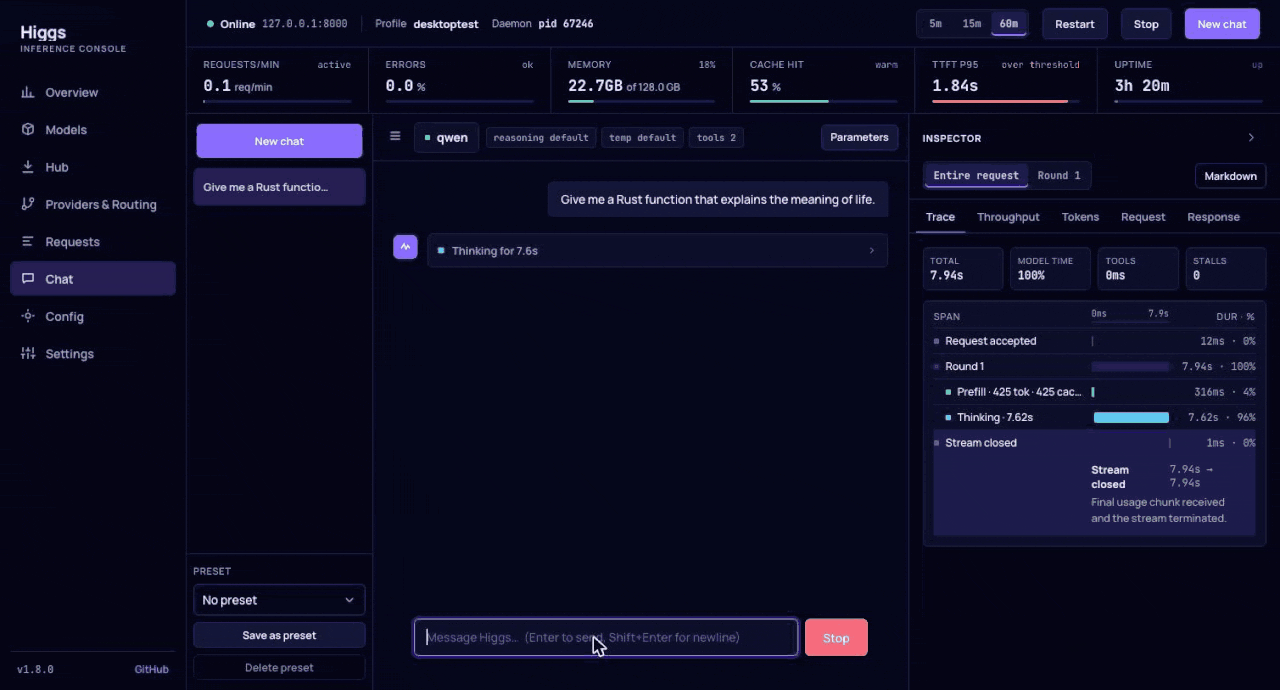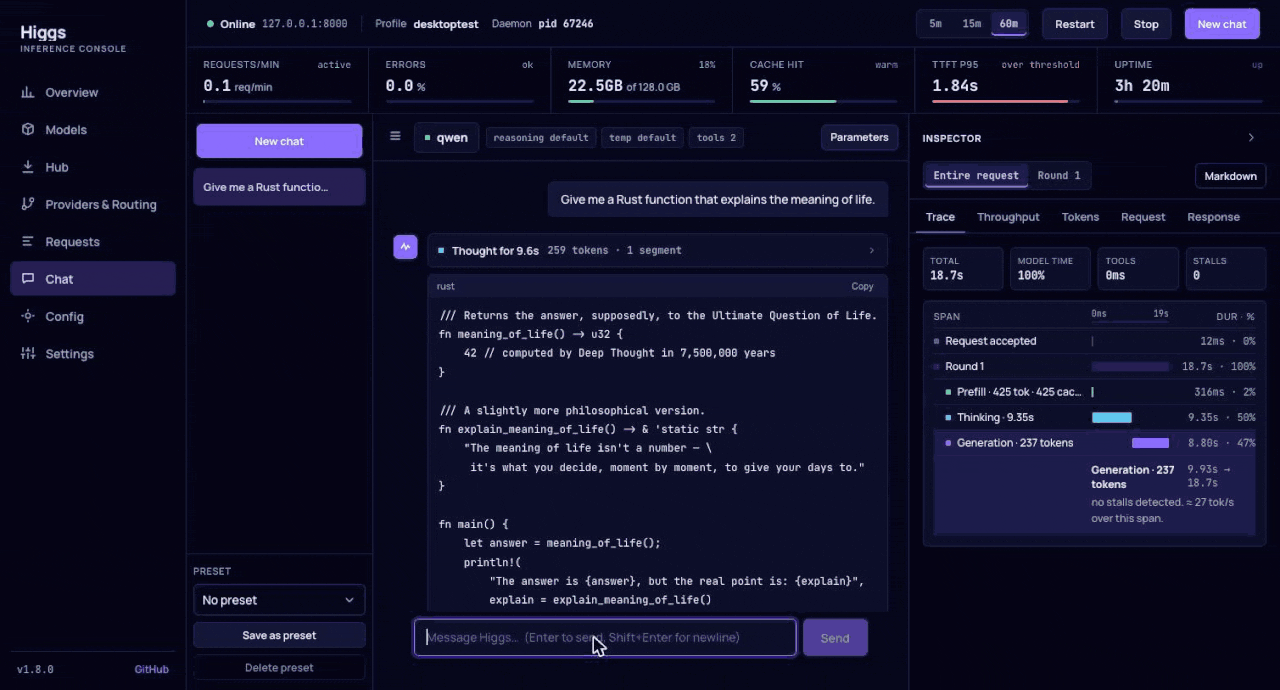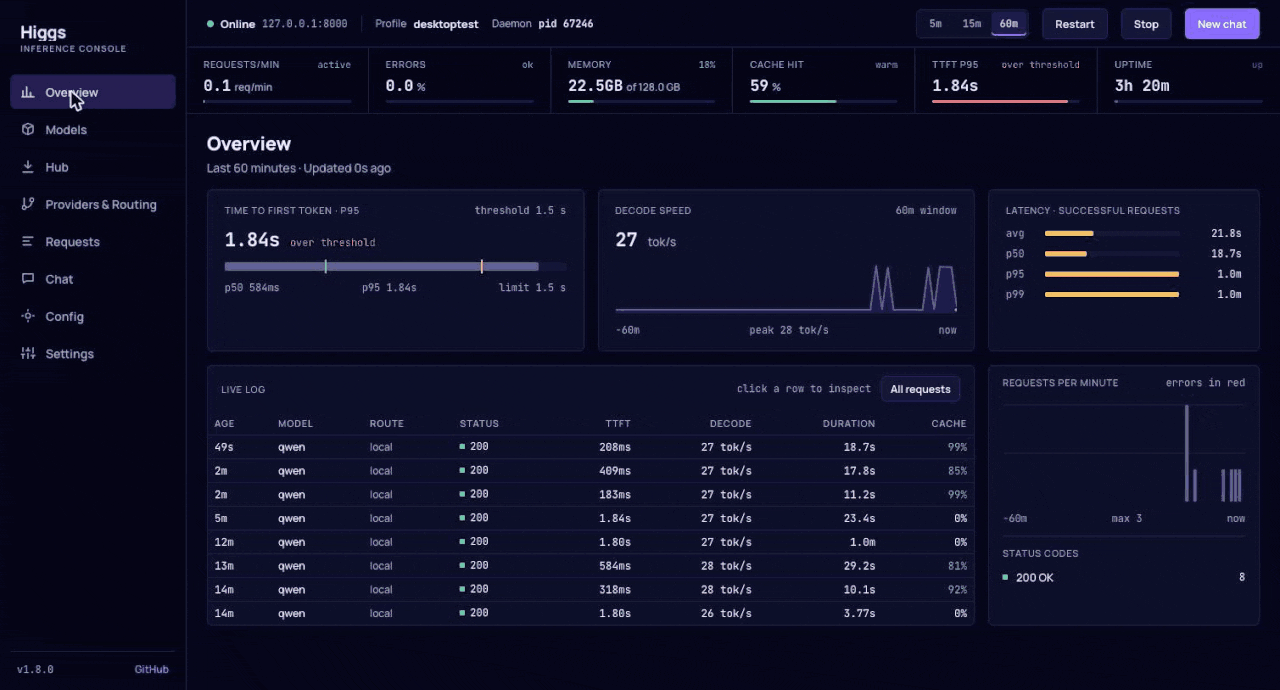
Higgs is a Rust binary (plus its Metal shader library) built on MLX. It serves open-weight models from Hugging Face on your Mac, proxies to OpenAI, Anthropic, Ollama and other providers behind the same endpoint, and translates between the OpenAI and Anthropic wire formats so existing tools keep working. The desktop app is the graphical counterpart of higgs attach: a dashboard of the server and its models, and a chat whose inspector traces every span of a request.
Read the full README
Why Higgs
- Fast on Apple Silicon. Native MLX inference with prefix caching, continuous batching for transformer families, quantized KV cache, and MoE prefill tuning. See Performance.
- One endpoint for everything. Local models and remote providers behind one URL, with regex routes, aliases, and an optional auto-router that picks a model per prompt.
- Drop-in for your tools.
higgs shellenvexportsOPENAI_BASE_URLandANTHROPIC_BASE_URL; Claude Code, Aider, and any OpenAI or Anthropic client just work. - You can see what is happening. Time to first token, decode tokens per second, and prefix-cache hits for local streaming requests, plus latency, throughput, and memory, in the
/metricsAPI and the desktop app.
Install
brew install panbanda/brews/higgs
brew install --cask panbanda/brews/higgs-desktop # desktop app; bundles the CLI
Or grab the binary and the desktop app from the latest release, or build from source with Rust 1.88+ and the Xcode Command Line Tools:
cargo build --release
Quick start
Serve a model from Hugging Face (downloaded on first use):
higgs serve --model mlx-community/Qwen3.6-35B-A3B-4bit
Talk to it with any OpenAI client:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"mlx-community/Qwen3.6-35B-A3B-4bit","messages":[{"role":"user","content":"Write one sentence about Cape Town."}]}'
Point your tools at it:
eval "$(higgs shellenv)"      # exports OPENAI_BASE_URL and ANTHROPIC_BASE_URL
higgs exec -- claude          # or aider, or anything OpenAI/Anthropic compatible
For a persistent setup with several models, providers, and routes, create a config and run the daemon:
higgs init                    # writes ~/.config/higgs/config.toml
higgs doctor                  # validates models, providers, and settings
higgs start                   # background daemon with metrics
higgs attach                  # terminal dashboard
higgs ui                      # desktop app, if installed
Desktop app
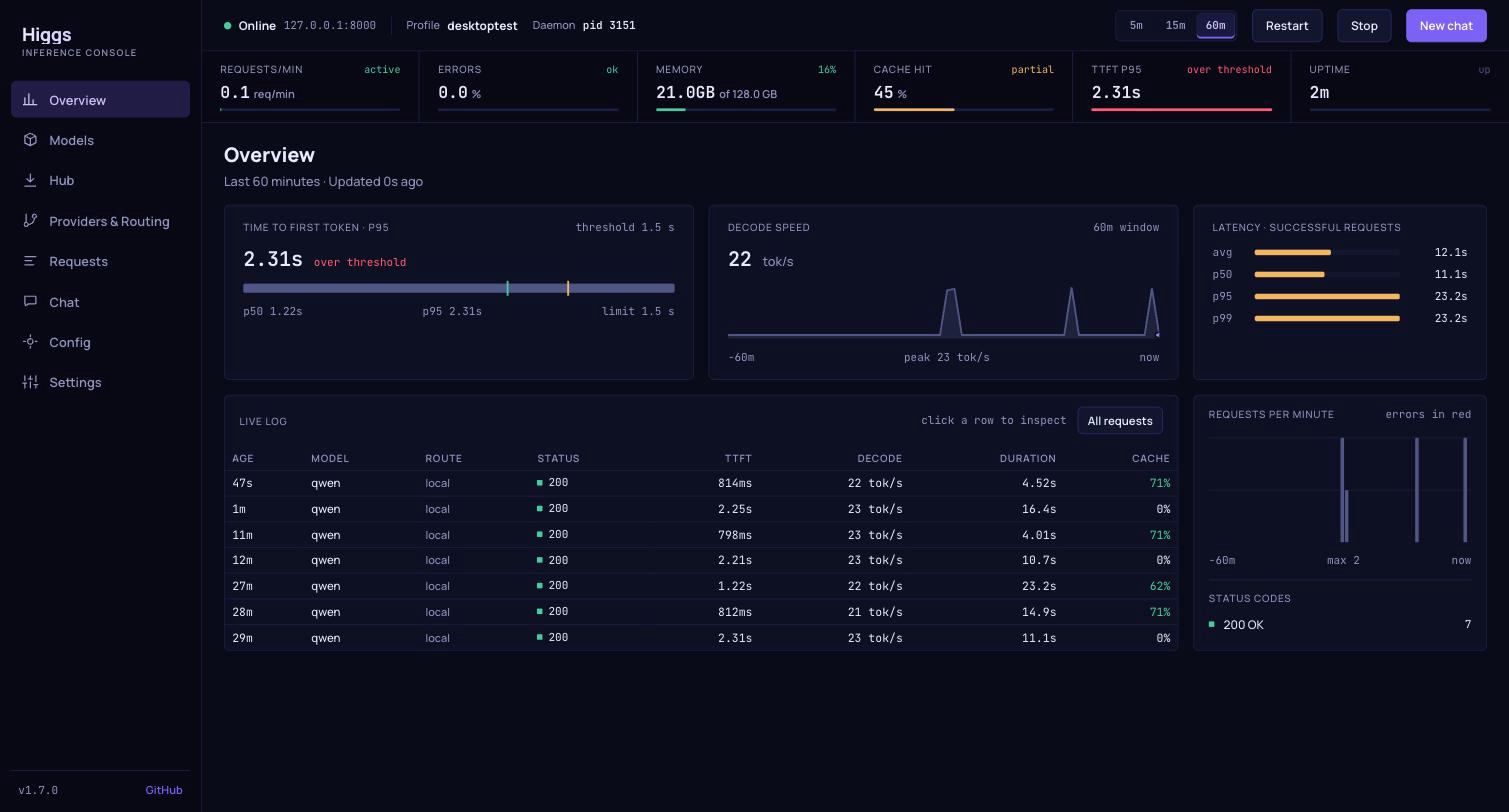
Ships with every release as a .dmg for Apple Silicon (unsigned; right-click, Open on first launch). It runs on the machine that runs Higgs and reads the same config, metrics log, and pid files as the CLI.
- Signal strip and Overview. Requests per minute, error rate, MLX memory, prefix-cache hit rate, TTFT p95 against a threshold, decode tokens per second, latency percentiles, and a live log.
- Models, Requests, Providers & Routing. Everything
higgs attachshows, with TTFT, decode rate, and cache hits per model and per request, and a Hub for browsing and downloadingmlx-communitycheckpoints. - Chat with a request trace. Every reply keeps a trace: a waterfall of prefill (with cache hits), thinking, generation, tool calls, and stalls across rounds; throughput; tokens; the exact request with Replay and Copy as curl; raw SSE chunks; and a Copy as Markdown report for sharing speed numbers.
- Config editor. Form or raw TOML, validated on save, followed by
higgs doctor, with daemon Start, Stop, and Restart.
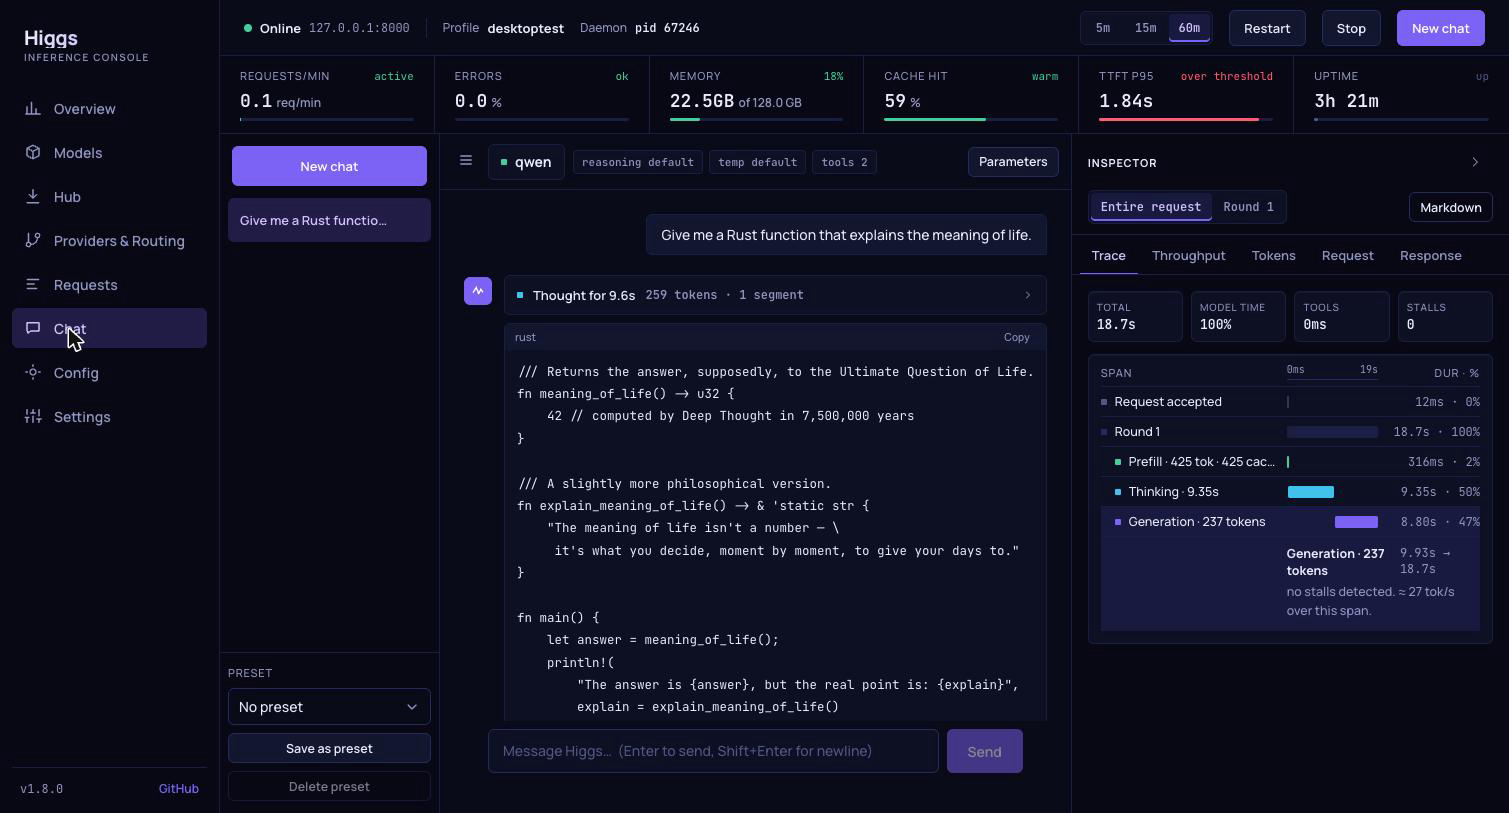
Details, data sources, and browser-mode development: docs/desktop.md.
Supported models
MLX checkpoints from Hugging Face IDs or local paths: Qwen 3.x (dense and MoE, including 3.5, 3.6, and 3.8), Llama, Mistral, Gemma 2, 3, and 4, Phi-3, Starcoder2, DeepSeek-V2, and LLaVA-Qwen2 vision models. Unknown newer versions of a supported family load with the nearest adapter and a warning; unknown families are rejected with the supported list. The full matrix is in docs/models.md.
Configuration
[server]
host = "127.0.0.1"
port = 8000

[[models]]
path = "mlx-community/Qwen3.6-35B-A3B-4bit"
name = "qwen"

[provider.anthropic]
url = "https://api.anthropic.com"
format = "anthropic"

[[routes]]
pattern = "claude-.*"
provider = "anthropic"

[default]
provider = "higgs"
Requests for qwen run locally; anything matching claude-.* is proxied to Anthropic with format translation; everything else falls through to the default. Routing precedence, the auto-router, KV cache and prefill options, profiles, and metrics settings are covered in docs/configuration.md.
API and CLI Overview
API endpoints
- OpenAI:
/v1/chat/completions,/v1/completions,/v1/embeddings,/v1/models- Streaming requests may set
"return_progress": trueto receive llama.cpp-compatibleprompt_progresschunks ({total, cache, processed, time_ms}) during chunked prefill.
- Streaming requests may set
- Anthropic:
/v1/messages,/v1/messages/count_tokens - Metrics:
/metrics(window totals, latency and time-to-first-token percentiles, aggregate tokens/s, per-model and per-provider groups with TTFT, tokens/s, and prefix-cache hits). Local streaming requests recordttft_msandcached_tokensin the metrics JSONL log. - System:
/v1/system(version, pid, uptime, unified memory, process RSS, MLX active/peak/cache memory, loaded models with engine kind and profile) - Health:
/health
/health, /metrics, /v1/models, and /v1/system are dashboard endpoints and
never count as traffic in metrics.
Core commands
higgs serve: start in the foregroundhiggs start: start a background daemon from config or profilehiggs stop: stop a running daemon, or usehiggs stop --forcehiggs attach: open the daemon metrics dashboardhiggs ui: open the desktop app if it is installed (macOS)higgs init: create~/.config/higgs/config.tomlhiggs doctor: validate config, model paths, and providershiggs shellenv: printANTHROPIC_BASE_URLandOPENAI_BASE_URLafter verifying the server is reachablehiggs exec -- <cmd>: run a tool with those variables set after the same reachability check
Apple Silicon Notes
- Release artifacts bundle
mlx.metallib. - Source builds also require
mlx.metallibnext to the executable. Higgs now restores it automatically from Cargo build output when possible, then fails loudly if it still cannot be found. [local].raise_wired_limitdefaults tofalse. Enable it only when you explicitly want MLX to raise the process wired-memory limit.batch=trueis only supported for transformer families with true batched decode support.- For batch models,
prefill_yield_tokenscan interleave long prompt prefills with decode; use0or omit it for the synchronous default.
Performance
Benchmarks below were run on M4 Max 128GB. Methodology, harness details, and benchmark-driven defaults are documented in docs/benchmarking.md.
Decode Throughput (tok/s)
Single request, 500 generated tokens, median of 3 runs.
| Model | higgs | mlx_lm | vllm-mlx | llama.cpp | Ollama |
|---|---|---|---|---|---|
| Llama-3.2-1B-4bit | 448 | 421 | 433 | 314 | 305 |
| Mistral-7B-v0.3-4bit | 103 | 103 | -- | 87 | 85 |
| Qwen3-1.7B-4bit | 305 | 293 | 300 | 216 | 183 |
| Qwen3-30B-A3B-8bit | 75 | 86 | 87 | 83 | 73 |
| Gemma-2-2B-4bit | 163 | 185 | 91 | -- | -- |
| Phi-3-mini-4bit | 171 | 170 | 95 | -- | -- |
| Starcoder2-3B-4bit | 107 | 176 | 165 | -- | -- |
| DeepSeek-V2-Lite-4bit | 140 | 174 | 99 | -- | -- |
MLX models use 4-bit, or 8-bit for MoE. llama.cpp and Ollama use Q4_K_M, or Q8_0 for MoE.
MoE Prefill (time to first token)
Measured on DeepSeek-V2-Lite-4bit with global batch sorting before gather_qmm.
| Prompt tokens | Before | After | Speedup |
|---|---|---|---|
| 59 | 472ms | 227ms | 2.1x |
| 481 | 3,734ms | 863ms | 4.3x |
| 1,831 | 14,390ms | 3,123ms | 4.6x |
| 4,532 | 37,489ms | 8,860ms | 4.2x |
Continuous Batching (Llama-1B)
| Concurrent requests | higgs tok/s | vllm-mlx tok/s |
|---|---|---|
| 1 | 280 | 250 |
| 2 | 585 | 459 |
| 4 | 698 | 510 |
| 8 | 755 | 646 |
Memory (RSS in MB)
| Model | higgs | mlx_lm | vllm-mlx |
|---|---|---|---|
| Llama-3.2-1B-4bit | 974 | 1,356 | 1,380 |
| Mistral-7B-v0.3-4bit | 3,965 | 4,384 | -- |
| Qwen3-1.7B-4bit | 1,127 | 1,609 | 1,641 |
| Qwen3-30B-A3B-8bit | 31,139 | 31,640 | 31,658 |
| Gemma-2-2B-4bit | 1,645 | 2,329 | 2,350 |
| Phi-3-mini-4bit | 2,126 | 2,548 | 2,573 |
| DeepSeek-V2-Lite-4bit | 8,528 | 8,972 | 8,998 |
Feature Comparison
| higgs | vllm-mlx | |
|---|---|---|
| Structured output (10 prompts, JSON schema) | 100% | 0% |
| Reasoning extraction (5 questions, Qwen3) | 5/5 | 4/5 |
| All architectures produce coherent output | Yes | Yes |
Development
cargo test -- --test-threads=1
cargo clippy
cargo fmt --check
cd apps/desktop && pnpm install && pnpm typecheck && pnpm build
Contributor workflow, project structure, release validation, and doc expectations live in CONTRIBUTING.md. Migration notes for older higgs start flags are in docs/configuration.md.
License
MIT
Compatibility
- License
- MIT
- Crate facts
- Not measured
- Runs on, Native code and Python bindings read crates on crates.io. This entry lists no crate.
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
A rust mlx server, ui, and model router for fast, dependency free inference on apple architecture |
23 binary downloads per release | Not applicable | 34 | Not measured | Not measured | MIT | |
|
ort Featured
A safe Rust wrapper for ONNX Runtime 1.31 - Optimize and accelerate machine learning inference & training Also in Run and serve models. |
3,902,768 downloads over 30 days | 694 | 2,611 | 2.0.0-rc.15 | CUDA, WebGPU, ROCm | Binds native code: onnxruntime, ort-sys. Build uses a native toolchain: pkg-config (feature pkg-config) | Apache-2.0 OR MIT |
|
Efficent platform for inference and serving local LLMs including an OpenAI compatible API server. Also in Build LLM apps and agents. |
138 binary downloads per release | Not applicable | 739 | Not measured | Not measured | MIT | |
|
cake Listed
Distributed LLM inference for mobile, desktop and server. Also in Run and serve models. |
22 downloads over 30 days | 0 | 3,131 | 0.1.0 | CUDA, Metal | No native code found | GPL-3.0 |
|
Inference server for LLMs, speech and embeddings: OpenAI-compatible routes with streaming, plus speech synthesis (TTS) and transcription (ASR). Serves Llama, Mistral, Qwen, Mamba2, MLA+MoE and hybrid models from SafeTensors, AWQ, GPTQ and GGUF. Also in Build LLM apps and agents. |
8 binary downloads per release | Not applicable | 7 | 0.7.1 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
furnace New
Fast, unified, Rust-native, Axum-compatible inference endpoints and nervous system for tensor models and LLMs: KServe / Triton and OpenAI APIs from one pure-Rust server Also in Build LLM apps and agents. |
241 downloads over 30 days | 0 | 66 | 0.16.2 | CUDA, WebGPU, Metal | No native code found | MIT |
All projects in Build LLM apps and agentsAll projects in Run and serve models
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- The check holds no value for Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days. A gate that lacks its signal does not pass.
What else the check found
- The last activity is on 4 Nov 2026, 5 days ago. The rules expect an update within 365 days. Dormancy rule
Not measured: First release, Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days.
Exact rules: Listed, Featured app. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: app: E = 365 daysdormancy: last activity 2026-11-04, 5 days ago, E = 365: activefeatured: not featured: unknown homebrew_on_request_365d, repology_families, docker_pull_growth_90dlisted: listed: no archive, new or featured rule applies
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources4 sources
- Description: the GitHub repository description
- GitHub releases, fetched
- GitHub repository, fetched
- GitHub contributors, fetched
Adoption23 binary downloads per release4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | Not measured | Yes | ||
| New dependents (365 days) | Not measured | Yes | ||
| Peak active dependents | Not measured | Yes | ||
| Active dependents as a share of the peak | Not measured | Yes | ||
| Binary downloads per release | 23 | GitHub releases | Yes |
MaintenanceLatest human commit: 5 days ago7 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-04 | GitHub repository | Yes | |
| Latest release | 2026-09-02 | GitHub releases | Yes | |
| First release | Not measured | Yes | ||
| Latest version | Not measured | Yes | ||
| Days the oldest outside issue waits for a reply | 111 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 11 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | Not measured | Yes | ||
| Published docs | Not measured | Yes | ||
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityNot measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | Not measured | Yes | ||
| RustSec unmaintained advisory | Not measured | Yes | ||
| Deprecation notice | Not measured | Yes | ||
| Deprecated requirement | Not measured | Yes |
Distribution71 binary downloads over the last 3 releases10 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | Not measured | Yes | ||
| Downloads over 30 days | Not measured | Yes | ||
| Binary downloads over the last 3 releases | 71 | GitHub releases | Yes | |
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | Not measured | Yes | ||
| Every version 0.0.x | Not measured | Yes | ||
| Every version yanked | Not measured | Yes | ||
| Crate deleted from crates.io | Not measured | Yes |
Repository34 stars, 6 forks, 6 contributors, 467 commits. Stars alone never qualify a project.1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 34 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 6 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 6 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 467 | GitHub repository | No | |
| Repository's main crate left out of the entry | Not measured | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | GitHub repository | No | |
| Runs on, from listed crates and their direct dependencies | Not measured | No | ||
| What shows each backend | Not measured | No | ||
| Native code, from listed crates and their dependencies | Not measured | No | ||
| Python bindings, from direct dependencies of listed crates | Not measured | No | ||
| Crates that depend on a listed crate directly | Not measured | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.