usearch
Library Featured
Smaller & Faster Single-File Vector Search Engine from Unum
- Downloads
- 242,089
- Dependents
- 70
- Stars
- 4,373
- Forks
- 373
- Contributors
- 114
- Commits
- 2,432
- Latest release
- 2.26.6 ·
About
Smaller & Faster Single-File
Similarity Search & Clustering Engine for Vectors & 🔜 Texts
Spatial • Binary • Probabilistic • User-Defined Metrics
C++11 •
Python 3 •
JavaScript •
Java •
Rust •
C99 •
Objective-C •
Swift •
C# •
Go •
Wolfram
Linux • macOS • Windows • iOS • Android • WebAssembly •
SQLite
- ✅ 10x faster HNSW implementation than FAISS.
- ✅ Simple and extensible single C++11 header library.
- ✅ Trusted by giants like Google and DBs like ClickHouse & DuckDB.
- ✅ SIMD-optimized and user-defined metrics with JIT compilation.
- ✅ Hardware-agnostic
bf16,e5m2, &i8- half-precision & quarter-precision support. - ✅ View large indexes from disk without loading into RAM.
- ✅ Heterogeneous lookups, renaming/relabeling, and on-the-fly deletions.
- ✅ Binary Tanimoto and Sorensen coefficients for Genomics and Chemistry applications.
- ✅ Space-efficient point-clouds with
uint40_t, accommodating 4B+ size. - ✅ Compatible with OpenMP and custom "executors" for fine-grained parallelism.
- ✅ Semantic Search and Joins.
- 🔄 Near-real-time clustering and sub-clustering for Tens or Millions of clusters.
Technical Insights and related articles:
Read the full README
- Uses Arm SVE and x86 AVX-512's masked loads to eliminate tail
for-loops. - Uses Horner's method for polynomial approximations, beating GCC 12 by 119x.
- For every language implements a custom separate binding.
Comparison with FAISS
FAISS is a widely recognized standard for high-performance vector search engines. USearch and FAISS both employ the same HNSW algorithm, but they differ significantly in their design principles. USearch is compact and broadly compatible without sacrificing performance, primarily focusing on user-defined metrics and fewer dependencies.
| FAISS | USearch | Improvement | |
|---|---|---|---|
| Indexing time ⁰ | |||
100 Million 96d f32, f16, i8 vectors | 2.6 · 2.6 · 2.6 h | 0.3 · 0.2 · 0.2 h | 9.6 · 10.4 · 10.7 x |
100 Million 1536d f32, f16, i8 vectors | 5.0 · 4.1 · 3.8 h | 2.1 · 1.1 · 0.8 h | 2.3 · 3.6 · 4.4 x |
| Codebase length ¹ | 84 K SLOC | 3 K SLOC | maintainable |
| Supported metrics ² | 9 fixed metrics | any metric | extendible |
| Supported languages ³ | C++, Python | 10 languages | portable |
| Supported ID types ⁴ | 32-bit, 64-bit | 32-bit, 40-bit, 64-bit | efficient |
| Filtering ⁵ | ban-lists | any predicates | composable |
| Required dependencies ⁶ | BLAS, OpenMP | - | light-weight |
| Bindings ⁷ | SWIG | Native | low-latency |
| Python binding size ⁸ | ~ 10 MB | < 1 MB | deployable |
⁰ Tested on Intel Sapphire Rapids, with the simplest inner-product distance, equivalent recall, and memory consumption while also providing far superior search speed. ¹ A shorter codebase of
usearch/overfaiss/makes the project easier to maintain and audit. ² User-defined metrics allow you to customize your search for various applications, from GIS to creating custom metrics for composite embeddings from multiple AI models or hybrid full-text and semantic search. ³ With USearch, you can reuse the same preconstructed index in various programming languages. ⁴ The 40-bit integer allows you to store 4B+ vectors without allocating 8 bytes for every neighbor reference in the proximity graph. ⁵ With USearch the index can be combined with arbitrary external containers, like Bloom filters or third-party databases, to filter out irrelevant keys during index traversal. ⁶ Lack of obligatory dependencies makes USearch much more portable. ⁷ Native bindings introduce lower call latencies than more straightforward approaches. ⁸ Lighter bindings make downloads and deployments faster.
Base functionality is identical to FAISS, and the interface must be familiar if you have ever investigated Approximate Nearest Neighbors search:
# pip install usearch

import numpy as np
from usearch.index import Index

index = Index(ndim=3)               # Default settings for 3D vectors
vector = np.array([0.2, 0.6, 0.4])  # Can be a matrix for batch operations
index.add(42, vector)               # Add one or many vectors in parallel
matches = index.search(vector, 10)  # Find 10 nearest neighbors

assert matches[0].key == 42
assert matches[0].distance <= 0.001
assert np.allclose(index[42], vector, atol=0.1) # Ensure high tolerance in mixed-precision comparisons
More settings are always available, and the API is designed to be as flexible as possible.
The default storage/quantization level is hardware-dependant for efficiency, but bf16 is recommended for most modern CPUs.
index = Index(
    ndim=3, # Define the number of dimensions in input vectors
    metric='cos', # Choose 'l2sq', 'ip', 'haversine' or other metric, default = 'cos'
    dtype='bf16', # Store as 'f64', 'f32', 'bf16', 'f16', 'e5m2', 'e4m3', 'e3m2', 'e2m3', 'u8', 'i8', 'b1'..., default = None
    connectivity=16, # Optional: Limit number of neighbors per graph node
    expansion_add=128, # Optional: Control the recall of indexing
    expansion_search=64, # Optional: Control the quality of the search
    multi=False, # Optional: Allow multiple vectors per key, default = False
)
Serialization & Serving Index from Disk
USearch supports multiple forms of serialization:
- Into a file defined with a path.
- Into a stream defined with a callback, serializing or reconstructing incrementally.
- Into a buffer of fixed length or a memory-mapped file that supports random access.
The latter allows you to serve indexes from external memory, enabling you to optimize your server choices for indexing speed and serving costs. This can result in 20x cost reduction on AWS and other public clouds.
index.save("index.usearch")

index.load("index.usearch")
view = Index.restore("index.usearch", view=True, ...)

other_view = Index(ndim=..., metric=...)
other_view.view("index.usearch")
Exact vs. Approximate Search
Approximate search methods, such as HNSW, are predominantly used when an exact brute-force search becomes too resource-intensive.
This typically occurs when you have millions of entries in a collection.
For smaller collections, we offer a more direct approach with the search method.
from usearch.index import search, MetricKind, Matches, BatchMatches
import numpy as np

# Generate 10'000 random vectors with 1024 dimensions
vectors = np.random.rand(10_000, 1024).astype(np.float32)
vector = np.random.rand(1024).astype(np.float32)

one_in_many: Matches = search(vectors, vector, 50, MetricKind.L2sq, exact=True)
many_in_many: BatchMatches = search(vectors, vectors, 50, MetricKind.L2sq, exact=True)
If you pass the exact=True argument, the system bypasses indexing altogether and performs a brute-force search through the entire dataset using SIMD-optimized similarity metrics from NumKong.
When compared to FAISS's IndexFlatL2 in Google Colab, USearch may offer up to a 20x performance improvement:
faiss.IndexFlatL2: 55.3 ms.usearch.index.search: 2.54 ms.
User-Defined Metrics
Built-in metrics return distances, so a smaller Match.distance means closer.
cos, the Python default, returns $1 - \frac{a \cdot b}{\lVert a \rVert \lVert b \rVert}$ for vectors of any length.ipreturns $1 - a \cdot b$, matchingcosonly for unit-length vectors and turning negative once $a \cdot b > 1$.l2sqreturns the squared Euclidean distance $\sum_i (a_i - b_i)^2$, without the square root.
While most vector search packages concentrate on just two metrics, "Inner Product distance" and "Euclidean distance", USearch allows arbitrary user-defined metrics. This flexibility allows you to customize your search for various applications, from computing geospatial coordinates with the rare Haversine distance to creating custom metrics for composite embeddings from multiple AI models, like joint image-text embeddings. You can use Numba, Cppyy, or PeachPy to define your custom metric even in Python:
from numba import cfunc, types, carray
from usearch.index import Index, MetricKind, MetricSignature, CompiledMetric

ndim = 256

@cfunc(types.float32(types.CPointer(types.float32), types.CPointer(types.float32)))
def python_inner_product(a, b):
    a_array = carray(a, ndim)
    b_array = carray(b, ndim)
    c = 0.0
    for i in range(ndim):
        c += a_array[i] * b_array[i]
    return 1 - c

metric = CompiledMetric(pointer=python_inner_product.address, kind=MetricKind.IP, signature=MetricSignature.ArrayArray)
index = Index(ndim=ndim, metric=metric, dtype=np.float32)
Similar effect is even easier to achieve in C, C++, and Rust interfaces. Moreover, unlike older approaches indexing high-dimensional spaces, like KD-Trees and Locality Sensitive Hashing, HNSW doesn't require vectors to be identical in length. They only have to be comparable. So you can apply it in obscure applications, like searching for similar sets or fuzzy text matching, using GZip compression-ratio as a distance function.
Filtering and Predicate Functions
Sometimes you may want to cross-reference search-results against some external database or filter them based on some criteria. In most engines, you'd have to manually perform paging requests, successively filtering the results. In USearch you can simply pass a predicate function to the search method, which will be applied directly during graph traversal. In Rust that would look like this:
let is_odd = |key: Key| key % 2 == 1;
let query = vec![0.2, 0.1, 0.2, 0.1, 0.3];
let results = index.filtered_search(&query, 10, is_odd).unwrap();
assert!(
    results.keys.iter().all(|&key| key % 2 == 1),
    "All keys must be odd"
);
Memory Efficiency, Downcasting, and Quantization
Training a quantization model and dimension-reduction is a common approach to accelerate vector search.
Those, however, are only sometimes reliable, can significantly affect the statistical properties of your data, and require regular adjustments if your distribution shifts.
Instead, we have focused on high-precision arithmetic over low-precision downcasted vectors.
The same index, and add and search operations will automatically down-cast or up-cast between f64_t, f32_t, bf16_t, f16_t, e5m2_t, e4m3_t, e3m2_t, e2m3_t, u8_t, i8_t, and single-bit b1x8_t representations.
You can use the following command to check, if hardware acceleration is enabled:
$ python -c 'from usearch.index import Index; print(Index(ndim=768, metric="cos", dtype="f16").hardware_acceleration)'
> sapphire
$ python -c 'from usearch.index import Index; print(Index(ndim=166, metric="tanimoto").hardware_acceleration)'
> ice
In most cases, bf16 is recommended for modern CPUs.
For even smaller footprints, USearch supports IEEE & MX-compatible Float8 (e5m2 and e4m3) and Float6 (e3m2 and e2m3) formats.
You can pass pre-quantized buffers from NumKong with the explicit dtype= parameter on add and search, or let USearch handle the quantization internally from higher-precision inputs.
When quantization is enabled, the "get"-like functions won't be able to recover the original data, so you may want to replicate the original vectors elsewhere.
When quantizing to i8_t integers, note that it's only valid for cosine-like metrics.
As part of the quantization process, the vectors are normalized to unit length and later scaled to [-127, 127] range to occupy the full 8-bit range.
When quantizing to b1x8_t single-bit representations, note that it's only valid for binary metrics like Jaccard, Hamming, etc.
As part of the quantization process, the scalar components greater than zero are set to true, and the rest to false.
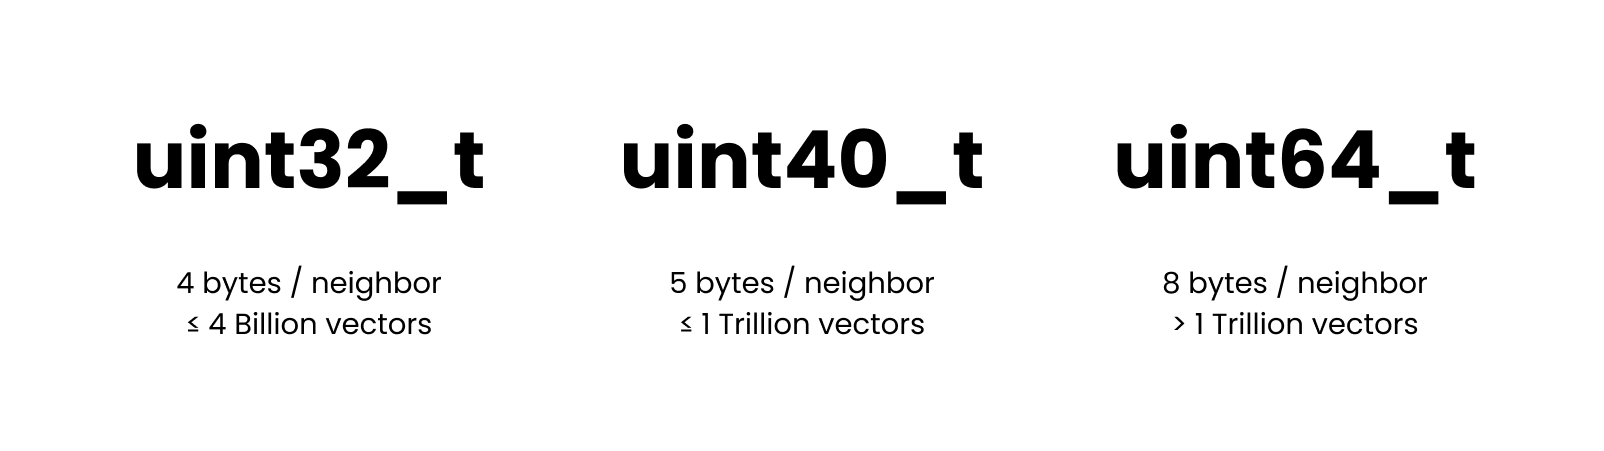
Using smaller numeric types will save you RAM needed to store the vectors, but you can also compress the neighbors lists forming our proximity graphs.
By default, 32-bit uint32_t is used to enumerate those, which is not enough if you need to address over 4 Billion entries.
For such cases we provide a custom uint40_t type, that will still be 37.5% more space-efficient than the commonly used 8-byte integers, and will scale up to 1 Trillion entries.
Indexes for Multi-Index Lookups
For larger workloads targeting billions or even trillions of vectors, parallel multi-index lookups become invaluable. Instead of constructing one extensive index, you can build multiple smaller ones and view them together.
from usearch.index import Indexes

multi_index = Indexes(
    indexes: Iterable[usearch.index.Index] = [...],
    paths: Iterable[os.PathLike] = [...],
    view: bool = False,
    threads: int = 0,
)
multi_index.search(...)
Clustering
Once the index is constructed, USearch can perform K-Nearest Neighbors Clustering much faster than standalone clustering libraries, like SciPy,
UMap, and tSNE.
Same for dimensionality reduction with PCA.
Essentially, the Index itself can be seen as a clustering, allowing iterative deepening.
clustering = index.cluster(
    min_count=10, # Optional
    max_count=15, # Optional
    threads=..., # Optional
)

# Get the clusters and their sizes
centroid_keys, sizes = clustering.centroids_popularity

# Use Matplotlib to draw a histogram
clustering.plot_centroids_popularity()

# Export a NetworkX graph of the clusters
g = clustering.network

# Get members of a specific cluster
first_members = clustering.members_of(centroid_keys[0])

# Deepen into that cluster, splitting it into more parts, all the same arguments supported
sub_clustering = clustering.subcluster(min_count=..., max_count=...)
The resulting clustering isn't identical to K-Means or other conventional approaches but serves the same purpose. Alternatively, using Scikit-Learn on a 1 Million point dataset, one may expect queries to take anywhere from minutes to hours, depending on the number of clusters you want to highlight. For 50'000 clusters, the performance difference between USearch and conventional clustering methods may easily reach 100x.
Joins, One-to-One, One-to-Many, and Many-to-Many Mappings
One of the big questions these days is how AI will change the world of databases and data management.
Most databases are still struggling to implement high-quality fuzzy search, and the only kind of joins they know are deterministic.
A join differs from searching for every entry, requiring a one-to-one mapping banning collisions among separate search results.
| Exact Search | Fuzzy Search | Semantic Search ? |
|---|---|---|
| Exact Join | Fuzzy Join ? | Semantic Join ?? |
Using USearch, one can implement sub-quadratic complexity approximate, fuzzy, and semantic joins. This can be useful in any fuzzy-matching tasks common to Database Management Software.
men = Index(...)
women = Index(...)
pairs: dict = men.join(women, max_proposals=0, exact=False)
Read more in the post: Combinatorial Stable Marriages for Semantic Search 💍
Functionality
By now, the core functionality is supported across all bindings. Broader functionality is ported per request. In some cases, like Batch operations, feature parity is meaningless, as the host language has full multi-threading capabilities and the USearch index structure is concurrent by design, so the users can implement batching/scheduling/load-balancing in the most optimal way for their applications.
| C++ 11 | Python 3 | C 99 | Java | JavaScript | Rust | Go | Swift | |
|---|---|---|---|---|---|---|---|---|
| Add, search, remove | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| Save, load, view | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| User-defined metrics | ✅ | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ |
| Batch operations | ❌ | ✅ | ❌ | ✅ | ✅ | ❌ | ❌ | ❌ |
| Filter predicates | ✅ | ❌ | ✅ | ❌ | ❌ | ✅ | ❌ | ✅ |
| Joins | ✅ | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| Variable-length vectors | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
| 4B+ capacities | ✅ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ | ❌ |
Application Examples
USearch + UForm + UCall = Multimodal Semantic Search
AI has a growing number of applications, but one of the coolest classic ideas is to use it for Semantic Search. One can take an encoder model, like the multi-modal UForm, and a web-programming framework, like UCall, and build a text-to-image search platform in just 20 lines of Python.
from ucall import Server
from uform import get_model, Modality
from usearch.index import Index

import numpy as np
import PIL as pil

processors, models = get_model('unum-cloud/uform3-image-text-english-small')
model_text = models[Modality.TEXT_ENCODER]
model_image = models[Modality.IMAGE_ENCODER]
processor_text = processors[Modality.TEXT_ENCODER]
processor_image = processors[Modality.IMAGE_ENCODER]

server = Server()
index = Index(ndim=256)

@server
def add(key: int, photo: pil.Image.Image):
    image = processor_image(photo)
    vector = model_image(image)
    index.add(key, vector.flatten(), copy=True)

@server
def search(query: str) -> np.ndarray:
    tokens = processor_text(query)
    vector = model_text(tokens)
    matches = index.search(vector.flatten(), 3)
    return matches.keys

server.run()
Similar experiences can also be implemented in other languages and on the client side, removing the network latency.
For Swift and iOS, check out the ashvardanian/SwiftSemanticSearch repository.
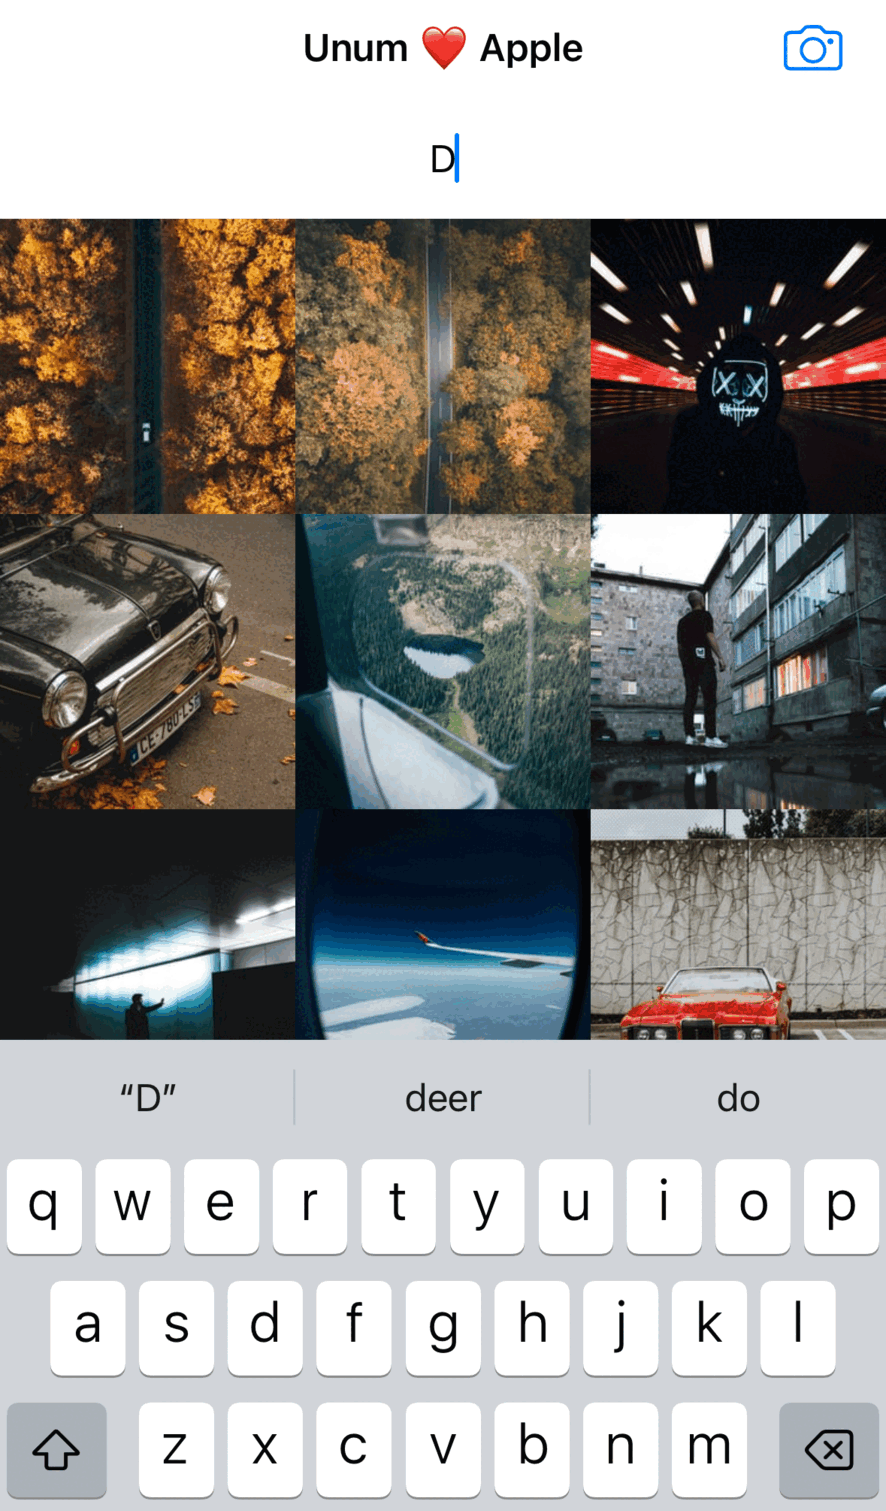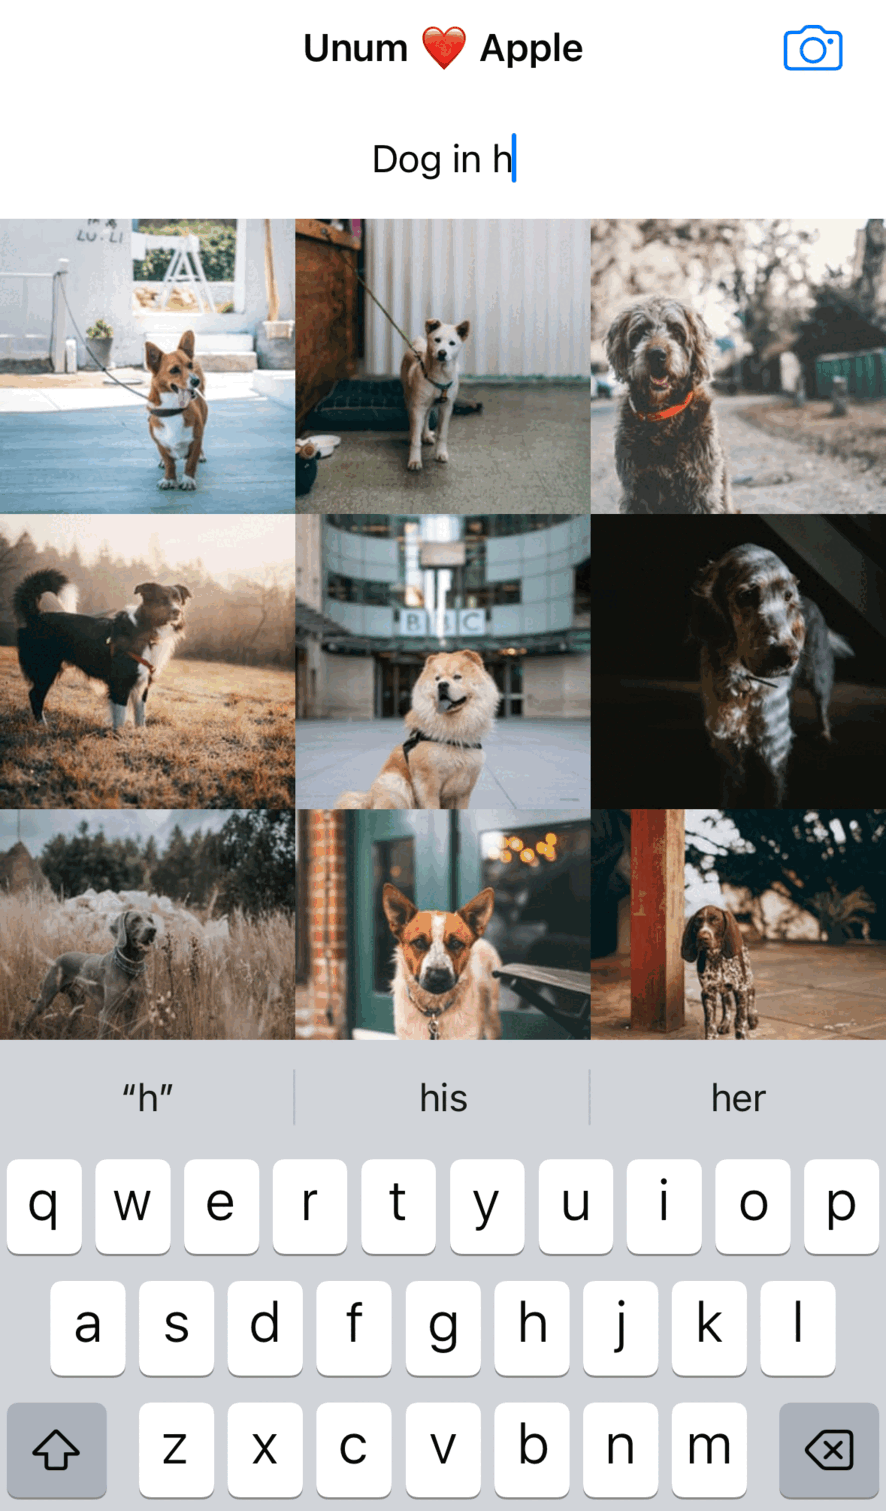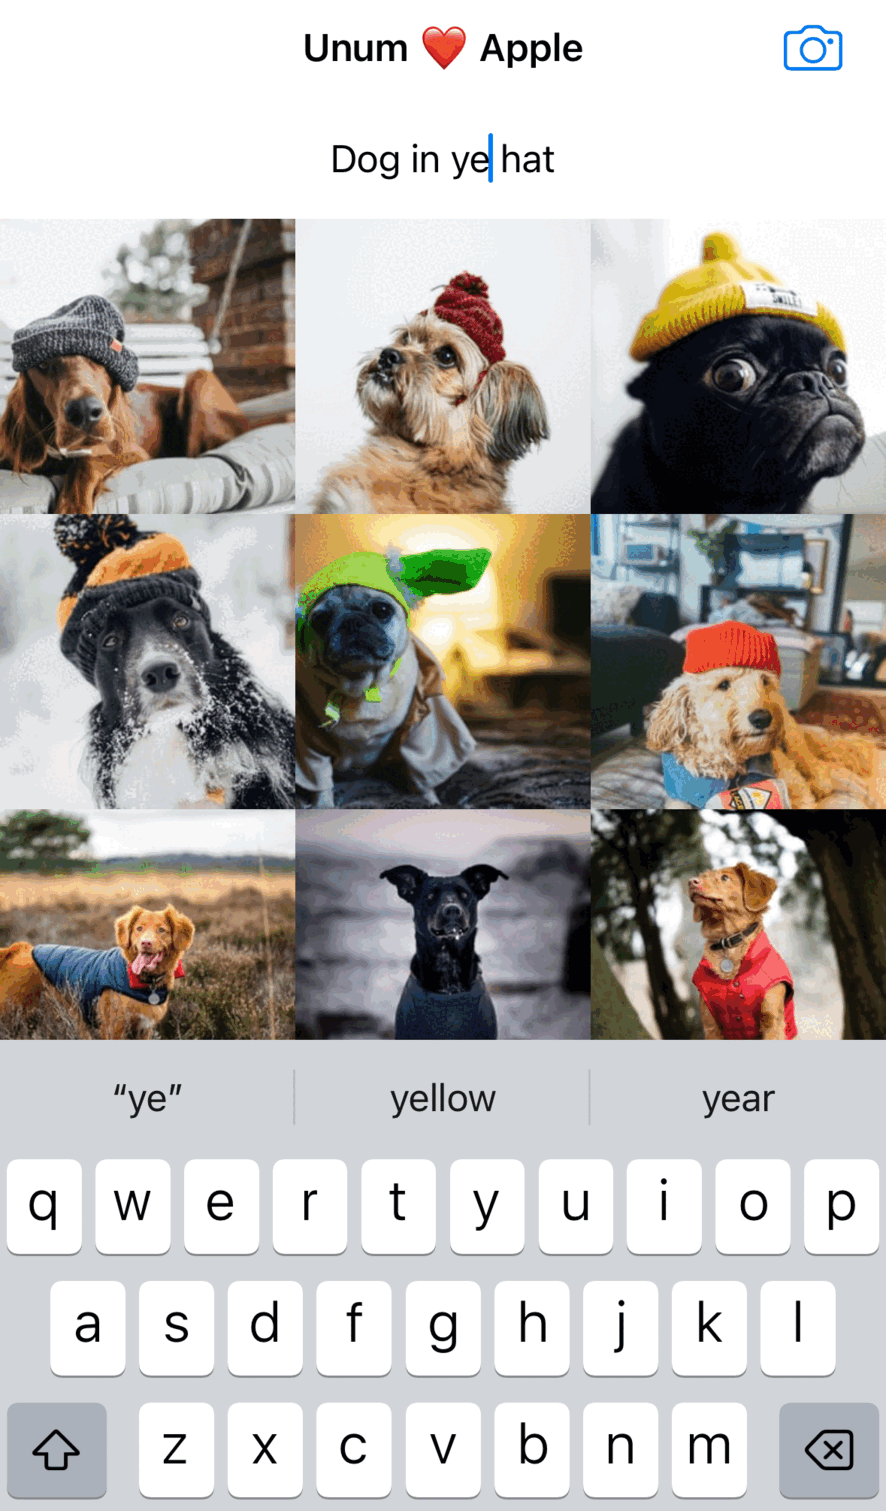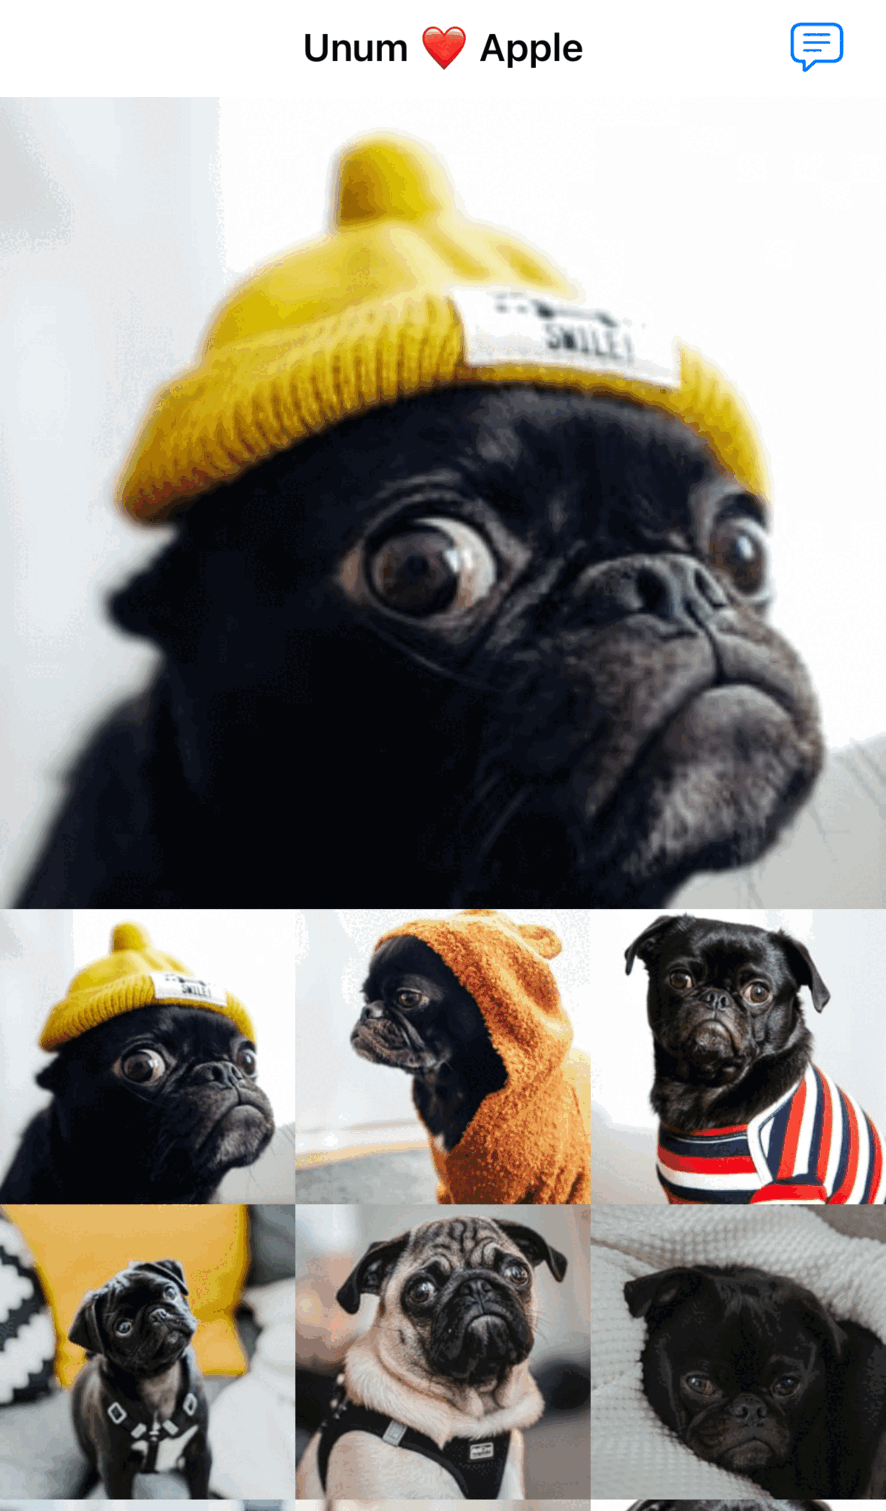 | 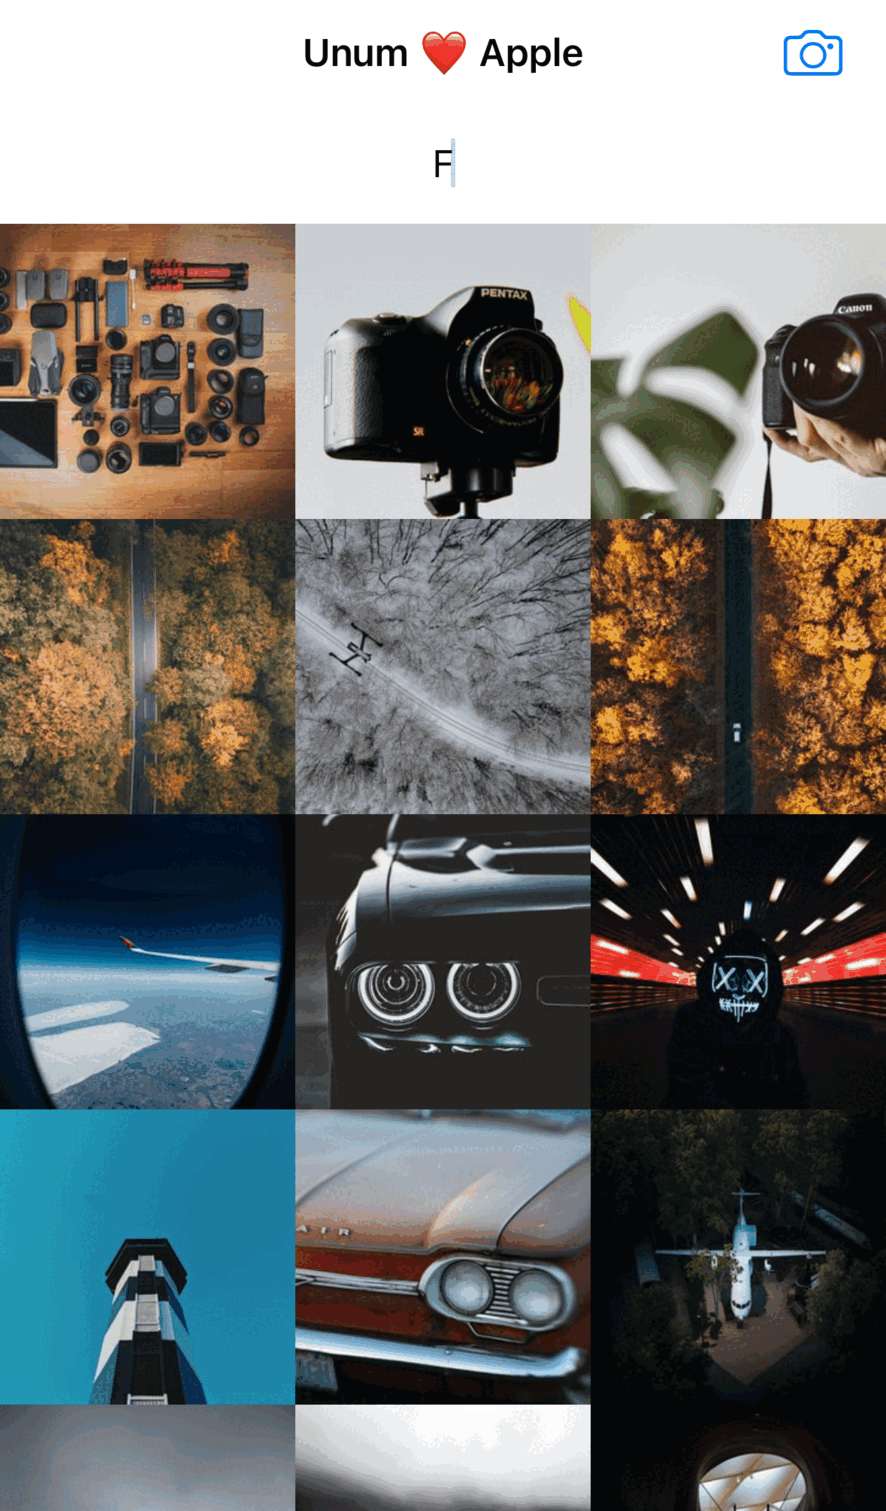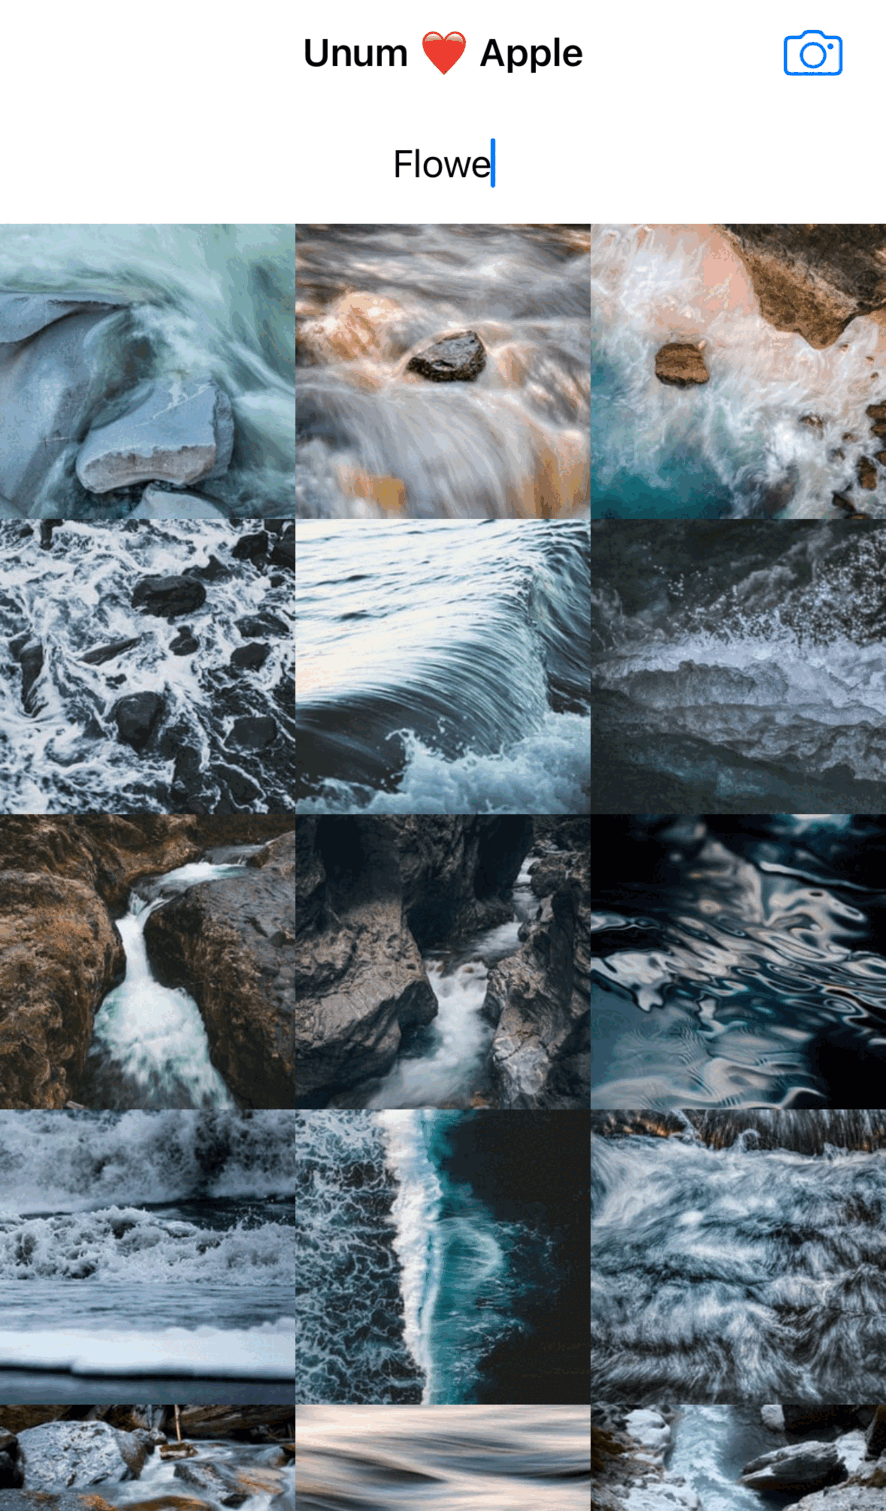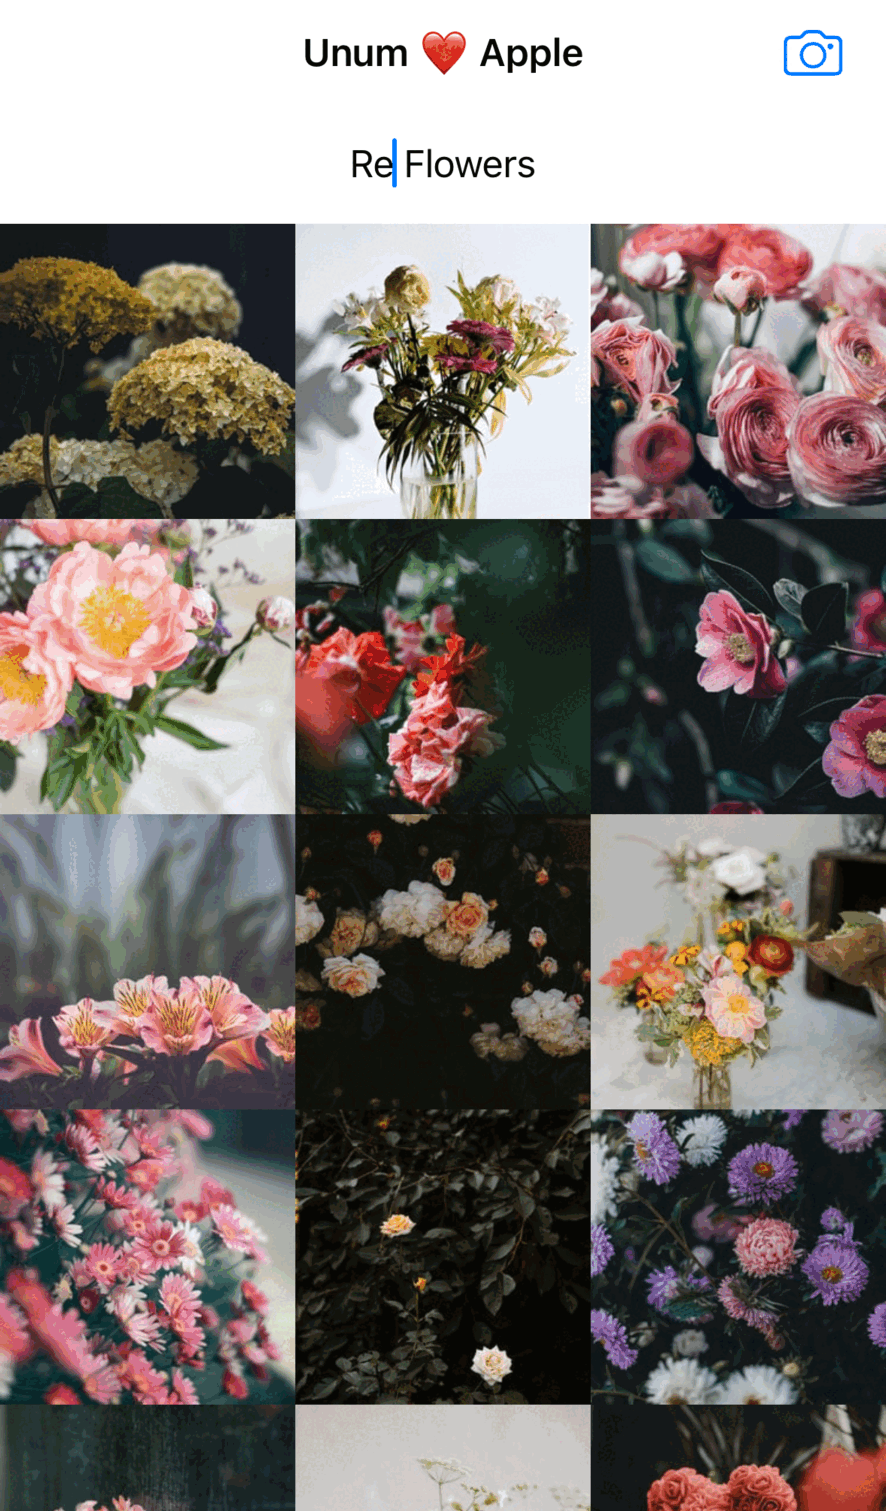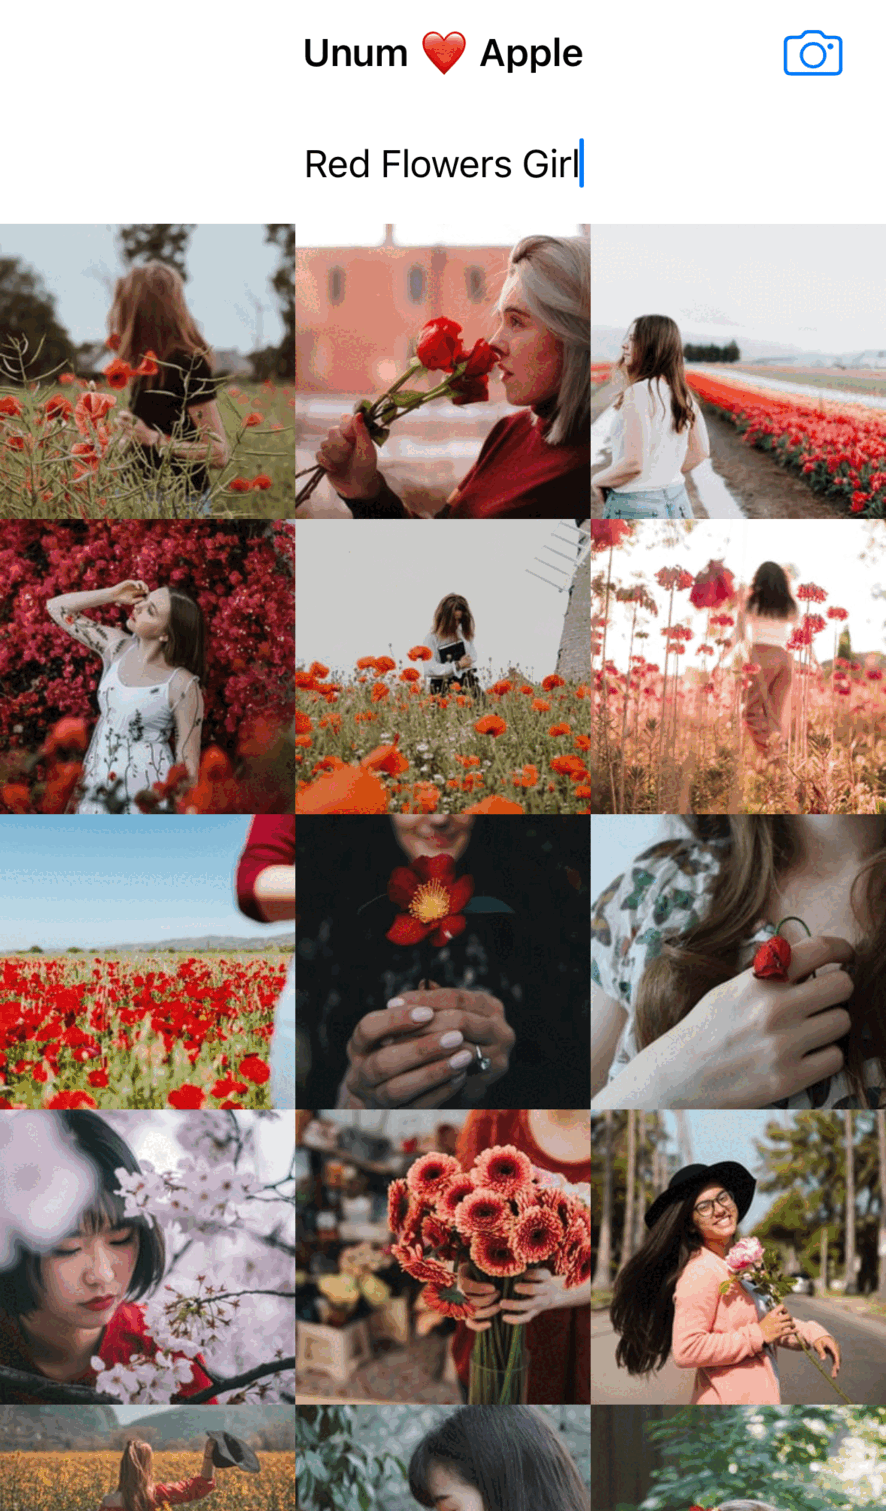 |
A more complete demo with Streamlit is available on GitHub. We have pre-processed some commonly used datasets, cleaned the images, produced the vectors, and pre-built the index.
| Dataset | Modalities | Images | Download |
|---|---|---|---|
| Unsplash | Images & Descriptions | 25 K | HuggingFace / Unum |
| Conceptual Captions | Images & Descriptions | 3 M | HuggingFace / Unum |
| Arxiv | Titles & Abstracts | 2 M | HuggingFace / Unum |
USearch + RDKit = Molecular Search
Comparing molecule graphs and searching for similar structures is expensive and slow. It can be seen as a special case of the NP-Complete Subgraph Isomorphism problem. Luckily, domain-specific approximate methods exist. The one commonly used in Chemistry is to generate structures from SMILES and later hash them into binary fingerprints. The latter are searchable with binary similarity metrics, like the Tanimoto coefficient. Below is an example using the RDKit package.
from usearch.index import Index, MetricKind
from rdkit import Chem
from rdkit.Chem import AllChem

import numpy as np

molecules = [Chem.MolFromSmiles('CCOC'), Chem.MolFromSmiles('CCO')]
encoder = AllChem.GetRDKitFPGenerator()

fingerprints = np.vstack([encoder.GetFingerprint(x) for x in molecules])
fingerprints = np.packbits(fingerprints, axis=1)

index = Index(ndim=2048, metric=MetricKind.Tanimoto)
keys = np.arange(len(molecules))

index.add(keys, fingerprints)
matches = index.search(fingerprints, 10)
That method was used to build the "USearch Molecules", one of the largest Chem-Informatics datasets, containing 7 billion small molecules and 28 billion fingerprints.
USearch + POI Coordinates = GIS Applications
Similar to Vector and Molecule search, USearch can be used for Geospatial Information Systems. The Haversine distance is available out of the box, but you can also define more complex relationships, like the Vincenty formula, that accounts for the Earth's oblateness.
from numba import cfunc, types, carray
import math

ndim = 2
semi_major, flattening = 6378137.0, 1 / 298.257223563
semi_minor = (1 - flattening) * semi_major

def vincenty_distance(first_ptr, second_ptr):
    first, second = carray(first_ptr, ndim), carray(second_ptr, ndim)
    lat1, lon1, lat2, lon2 = first[0], first[1], second[0], second[1]
    diff_lon = lon2 - lon1
    rlat1, rlat2 = math.atan((1 - flattening) * math.tan(lat1)), math.atan((1 - flattening) * math.tan(lat2))
    sin_rlat1, cos_rlat1 = math.sin(rlat1), math.cos(rlat1)
    sin_rlat2, cos_rlat2 = math.sin(rlat2), math.cos(rlat2)
    lon_on_sphere = diff_lon
    for _ in range(100):
        sin_lon, cos_lon = math.sin(lon_on_sphere), math.cos(lon_on_sphere)
        sin_ang = math.sqrt((cos_rlat2 * sin_lon) ** 2 + (cos_rlat1 * sin_rlat2 - sin_rlat1 * cos_rlat2 * cos_lon) ** 2)
        if sin_ang == 0: return 0.0
        cos_ang = sin_rlat1 * sin_rlat2 + cos_rlat1 * cos_rlat2 * cos_lon
        ang = math.atan2(sin_ang, cos_ang)
        sin_az = cos_rlat1 * cos_rlat2 * sin_lon / sin_ang
        cos2_az = 1 - sin_az ** 2
        cos2_mid = cos_ang - 2 * sin_rlat1 * sin_rlat2 / cos2_az if cos2_az != 0 else 0.0
        corr = flattening / 16 * cos2_az * (4 + flattening * (4 - 3 * cos2_az))
        prev = lon_on_sphere
        lon_on_sphere = diff_lon + (1 - corr) * flattening * (
            sin_az * (ang + corr * sin_ang * (cos2_mid + corr * cos_ang * (-1 + 2 * cos2_mid ** 2))))
        if abs(lon_on_sphere - prev) <= 1e-12: break
    else:
        return float('nan')
    u_sq = cos2_az * (semi_major ** 2 - semi_minor ** 2) / (semi_minor ** 2)
    ca = 1 + u_sq / 16384 * (4096 + u_sq * (-768 + u_sq * (320 - 175 * u_sq)))
    cb = u_sq / 1024 * (256 + u_sq * (-128 + u_sq * (74 - 47 * u_sq)))
    delta = cb * sin_ang * (cos2_mid + cb / 4 * (cos_ang * (-1 + 2 * cos2_mid ** 2)
        - cb / 6 * cos2_mid * (-3 + 4 * sin_ang ** 2) * (-3 + 4 * cos2_mid ** 2)))
    return semi_minor * ca * (ang - delta) / 1000.0

index = Index(ndim=ndim, metric=CompiledMetric(
    pointer=vincenty_distance.address,
    kind=MetricKind.Haversine,
    signature=MetricSignature.ArrayArray,
))
Integrations & Users
Databases & Query Engines
- [x] ClickHouse: C++, docs.
- [x] DuckDB: post.
- [x] ScyllaDB: Rust, presentation.
- [x] TiDB & TiFlash: C++, announcement.
- [x] YugaByte: C++, architecture, 1B-vector benchmark.
- [x] MemGraph: C++, announcement.
- [x] MatrixOne: GoLang.
- [x] GreptimeDB: Rust.
- [x] KurrentDB: C#, credits.
- [x] Chroma: Rust, behind their RaBitQ-quantized SPANN index.
AI Frameworks & Memory
- [x] Google: Perch bioacoustics DB, UniSim, RetSim paper.
- [x] Microsoft: Semantic Kernel and vcpkg.
- [x] LangChain: Python and JavaScript.
- [x] Hugging Face: Sentence-Transformers docs, quantization benchmarks.
- [x] GPTCache: Python.
- [x] MemMachine: Python.
- [x] Pathway: Rust.
- [x] Vald: GoLang.
Applications & Products
- [x] Arm MCP: Python.
- [x] GPT4All: C++.
- [x] Ente: Rust, post.
- [x] Tracy profiler: C++, behind the embeddings index of its LLM assistant.
- [x] Copilot for Xcode by Intitni: Swift.
- [x] LLM for Unity: C#, docs.
- [x] Music Assistant: Python, docs.
Citations
@software{Vardanian_USearch,
doi = {10.5281/zenodo.7949415},
author = {Vardanian, Ash},
title = {{USearch by Unum Cloud}},
url = {https://github.com/unum-cloud/USearch},
version = {2.26.6},
year = {2026},
}
Compatibility
- Runs on
- GPU support unknown
What shows it
- no dependency or feature matches a backend row
- Native code
- Required
- Binds native code: cxx, link-cplusplus, numkong (feature numkong)
- Build uses a native toolchain: cxx-build
- Python bindings
- No Python binding crate found
- License
- Apache-2.0
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Smaller & Faster Single-File Vector Search Engine from Unum |
242,089 downloads over 30 days | 70 | 4,373 | 2.26.6 | GPU support unknown | Binds native code: cxx, link-cplusplus, numkong (feature numkong). Build uses a native toolchain: cxx-build | Apache-2.0 |
|
Qdrant - High-performance, massive-scale Vector Database and Vector Search Engine for the next generation of AI. Also available in the cloud https://cloud.qdrant.io/ |
34,017 binary downloads per release | Not applicable | 35,478 | Not measured | Not measured | Apache-2.0 | |
|
Postgres extension for vector search (DiskANN), complements pgvector for performance and scale. Postgres OSS licensed. |
33,328 binary downloads per release | Not applicable | 3,161 | Not measured | Not measured | PostgreSQL | |
|
faiss-rs Listed
High-level bindings for Faiss, the vector similarity search engine |
19,449 downloads over 30 days | 5 | 250 | 0.13.0 | GPU support unknown | Binds native code: faiss-sys, faiss_c. Build uses a native toolchain: cmake (feature static) | Apache-2.0 OR MIT |
|
regexr Listed
A high-performance regex engine built from scratch with JIT compilation and SIMD acceleration |
8,809 downloads over 30 days | 4 | 28 | 0.6.2 | GPU support unknown | No native code found | Apache-2.0 OR MIT |
|
velesdb Listed
High-performance vector database engine written in Rust |
2,396 downloads over 30 days | 0 | 102 | 8.1.0 | WebGPU | Binds native code: tauri, tauri-plugin-velesdb, atk-sys, gdk-pixbuf-sys, gdk-sys and 9 more | Not measured |
|
next-plaid Listed
CPU-based PLAID implementation for multi-vector search using ndarray Python bindings |
256 downloads over 30 days | 1 | 610 | 1.8.5 | CUDA | Binds native code: tree-sitter, libsqlite3-sys, ort-sys, tree-sitter-language, zstd-sys and 4 more | Apache-2.0 |
Why FeaturedIt passes every Featured gate.
What it meets
- It has 51 active dependents and 51 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days.
- Active dependents are at 100% of their peak. Featured needs at least 50%.
- Docs are present. The release commit or a manifest ties the crate to the repository.
- No vulnerability advisory stays unpatched past the grace window. At least one version is neither a prerelease nor 0.0.x.
- The last activity is on 31 Oct 2026, 9 days ago. The rules expect an update within 2800 days. Dormancy rule
Exact rules: Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 2.26.6 base 700, doubled for 242089 downloads per month, doubled for 51 active users: E = 2800 daysdormancy: last activity 2026-10-31, 9 days ago, E = 2800: activefeatured: featured: active_users 51, new_adopters 51, former_glory 1
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption51 active dependents, 51 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 51 | crates.io database dump | Yes | |
| New dependents (365 days) | 51 | crates.io database dump | Yes | |
| Peak active dependents | 49.5 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: 9 days ago3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-10-31 | GitHub repository | Yes | |
| Latest release | 2026-10-25 | crates.io database dump | Yes | |
| First release | 2023-05-02 | crates.io database dump | Yes | |
| Latest version | 2.26.6 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 376 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 28 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | none | crates.io database dump | Yes |
Distribution209 releases, 242,089 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 209 | crates.io database dump | Yes | |
| Downloads over 30 days | 242089 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository4,373 stars, 373 forks, 114 contributors, 2,432 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 4373 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 373 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 114 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 2432 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | Apache-2.0 | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | GPU support unknown | crates.io database dump | No | |
| What shows each backend | no dependency or feature matches a backend row | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: cxx, link-cplusplus, numkong (feature numkong). Build uses a native toolchain: cxx-build | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 70 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.