velesdb
Library Listed
High-performance vector database engine written in Rust
- Downloads
- 2,396
- Dependents
- 0
- Stars
- 102
- Forks
- 13
- Contributors
- 7
- Commits
- 4,899
- Latest release
- 8.1.0 ·
About
One ~14 MB binary fuses vector + graph + columnar under a single query language — with an agent memory that shows its evidence and a deterministic context compiler that cuts your real, billed token spend.
Local-first: nothing leaves the machine, no LLM and no API key in the memory path. Every number below links to a committed harness you can rerun.
Quick start • Proof • Limitations • Architecture • Roadmap • velesdb.com
Start here — three commands that work
pip install velesdb
curl -O https://raw.githubusercontent.com/cyberlife-coder/VelesDB/main/examples/python/hello_velesdb.py
python hello_velesdb.py
To search your own text instead of hand-written vectors, install the opt-in local adapter (pip install "velesdb[embed-sentence-transformers]") and run hello_velesdb_text.py; its first run downloads all-MiniLM-L6-v2.
Expected output, byte-for-byte (read the script — no server, no embedding model):
Query: "tech"
  score=1.000  Rust 1.89 release notes
  score=0.600  AI-generated jazz: the new wave
  score=0.000  Best ramen in Tokyo

Query: "tech + music"
  score=0.990  AI-generated jazz: the new wave
  score=0.707  Rust 1.89 release notes
  score=0.707  Miles Davis discography
Read the full README
An embedding model determines the vector dimension, while your similarity semantics determine the metric. Both are fixed when a collection is created; to change either, create a new collection and re-index your documents.
Give your agent a persistent memory — three more commands:
cargo install velesdb-memory                                    # the local MCP memory server
claude mcp add velesdb-memory -- ~/.cargo/bin/velesdb-memory    # any MCP client works
curl -L https://github.com/cyberlife-coder/VelesDB/releases/latest/download/velesdb-skills.tar.gz | tar -xz -C ~/.claude/skills/
No Rust toolchain? npm i @wiscale/velesdb-memory-node, or grab a prebuilt .mcpb bundle from the official MCP Registry (io.github.cyberlife-coder/velesdb-memory).
Other paths — always-on hooks, shared daemon, Rust, Docker, WASM, REST
Memory used continuously, not just available: integrations/agent-hooks/ wires six Claude Code hooks — SessionStart/Stop/PreCompact resume and save the working context, PreToolUse requires successful recall before an opted-in repository edit, PostToolUse both records that recall and compiles an oversized tool result before it enters the transcript, and PostToolUseFailure records a failed check so the Stop checklist can cite verified outcomes for feedback. One global install covers every project without enabling the edit guard outside explicitly configured repositories.
One memory shared by several clients (Claude Code, Codex CLI, Claude Desktop, Windsurf, Devin CLI): scripts/install-memory-daemon.sh runs velesdb-memory as a single local daemon — HTTPS by default, with a natively generated local CA.
Cargo (Rust + REST server): cargo install velesdb-server velesdb-cli — Docker (multi-arch linux/amd64 + linux/arm64): docker run -d -p 8080:8080 -v velesdb_data:/data --name velesdb ghcr.io/cyberlife-coder/velesdb:latest, then curl http://localhost:8080/health.
Browser / edge: the WASM build is ~710 KB gzipped and runs entirely client-side (TypeScript SDK). REST: 54 REST endpoints (OpenAPI spec). Full matrix: installation guide.
Why VelesDB
- One database instead of three. Vectors for "what feels similar", a graph for "what is connected", typed columns for "what I know for sure" — normally three deployments, three query languages, and glue code. Here it is one binary and one language.
- A memory that can be audited, not just queried. Every recall can show the evidence behind it; every compression decision carries a rule id, a reason, and a risk level. Deterministic by construction — no model in the write path, so no drift and nothing to re-litigate.
- Local-first is a sovereignty decision, not a latency one. No cloud, no API key, no data processor: air-gapped if you want it, in your jurisdiction by default. Why that matters · positioning in depth.
How it works, in plain terms
Four things happen, and none of them calls an AI provider.
1 · It stores facts, not conversations. You give it one statement — "the API port is 6333 because 3000 collided with the web UI" — and it lands in a local file store. No model call, nothing sent anywhere.
2 · It finds them by meaning. Asking "which port did we settle on" reaches that fact even though none of the words match. A local embedding model turns text into coordinates; close meaning means close coordinates.
3 · It connects them, and that is the part a search engine cannot do. Each
fact is linked to the topics it mentions. why() starts from the best match and
then walks those links, so it returns the answer plus the facts that
explain it — including ones sharing no vocabulary with your question.
The links have to exist. Store facts one by one and the graph stays flat, so
why()behaves like a search. Hand a paragraph toremember_extractedand it splits it into facts and wires the links for you.
4 · It compresses what is too big, before you pay for it. Give the compiler your accumulated context and a token budget; it returns a smaller version with one recorded decision per fragment — kept, abstracted, or dropped — and a handle to fetch any original back verbatim. Same input, same bytes out, every time. That is what the 82.5 % below measures.
What no one else combines
1 · Three engines, one query
| Engine | What it does |
|---|---|
| Vector | Semantic similarity (HNSW + AVX2/NEON SIMD) |
| Graph | Typed relationships, BFS/DFS, native MATCH clause (patterns) |
| ColumnStore | Typed columnar metadata filtering, secondary indexes |
One statement crosses all three — similarity, relations and typed filters, no glue code:
MATCH (doc:Document)-[:AUTHORED_BY]->(author:Person)
WHERE similarity(doc.embedding, $question) > 0.8
  AND author.department = 'Engineering'
RETURN author.name, doc.title
ORDER BY similarity() DESC LIMIT 5
2 · A memory that shows its evidence — why()
Most "agent memory" is vector recall: it finds text that looks like your query. VelesDB connects memories with typed links, so it can answer why something happened by walking the graph to context that shares no words with your question — across process restarts, offline, no API key:
from velesdb import MemoryService            # pip install velesdb

mem = MemoryService("./agent_memory")        # a real on-disk store; survives restarts
reason = mem.remember("Robert is recovering from knee surgery")
mem.remember("Booked the aisle seat on Robert's flight", links=[(reason, "because")])

# A *new* process, weeks later, reopens the same store and asks why:
mem.why("why the aisle seat on Robert's flight?")   # walks booking → reason — recall() can't
MemoryServicedefaults to the offlinehashembedder: deterministic, but lexical rather than semantic, so unrelated wording can score0.000. Opening it now says so once on stderr. For meaning-based recall, passembedder="ollama"; follow Real semantic recall in 5 minutes.
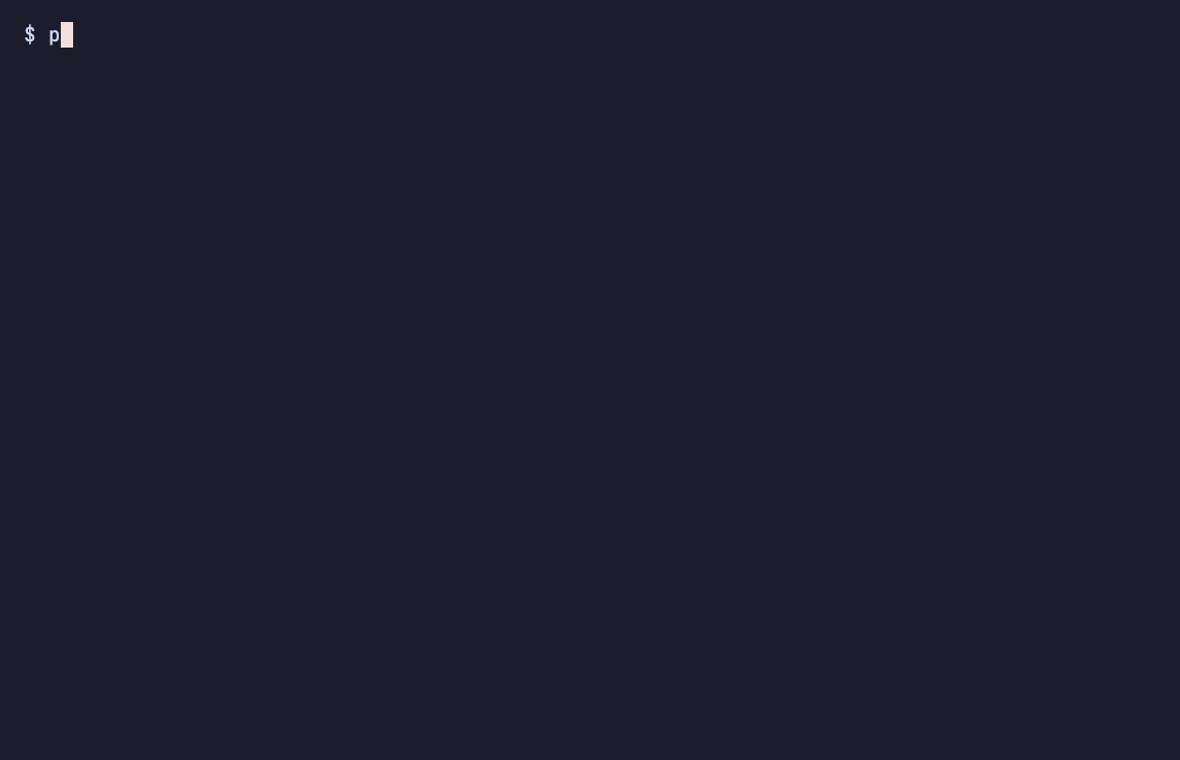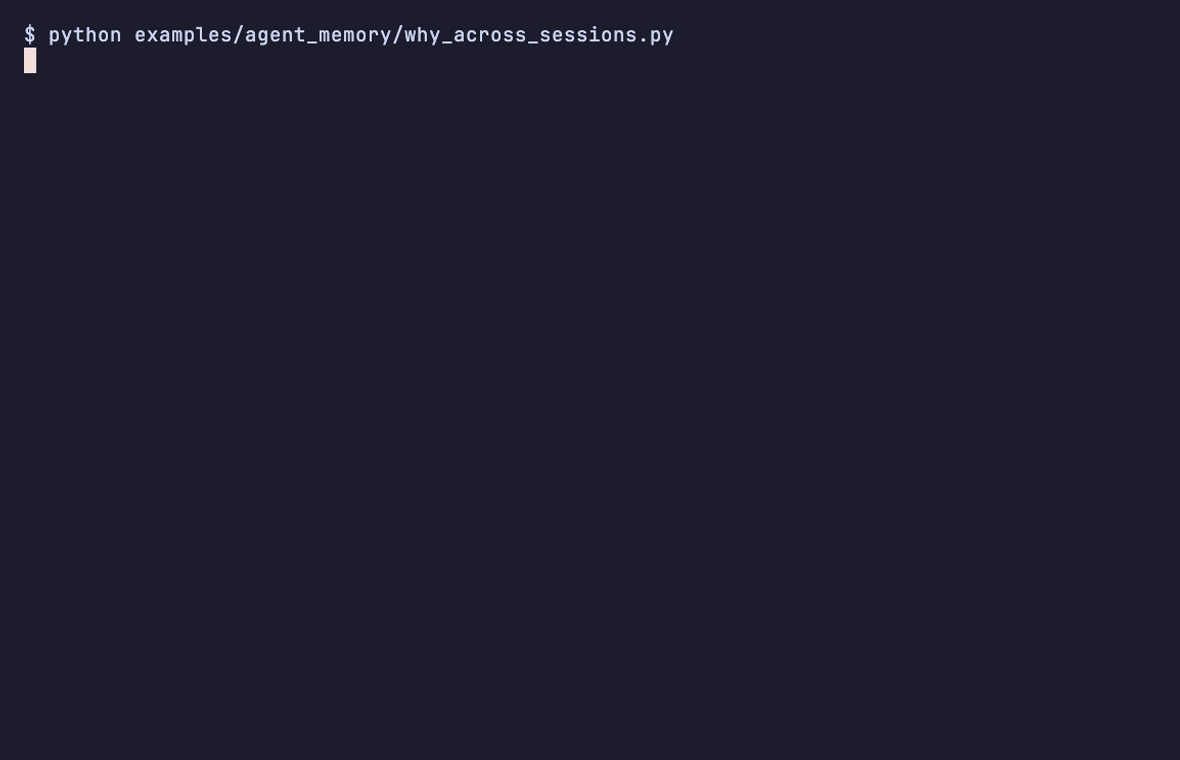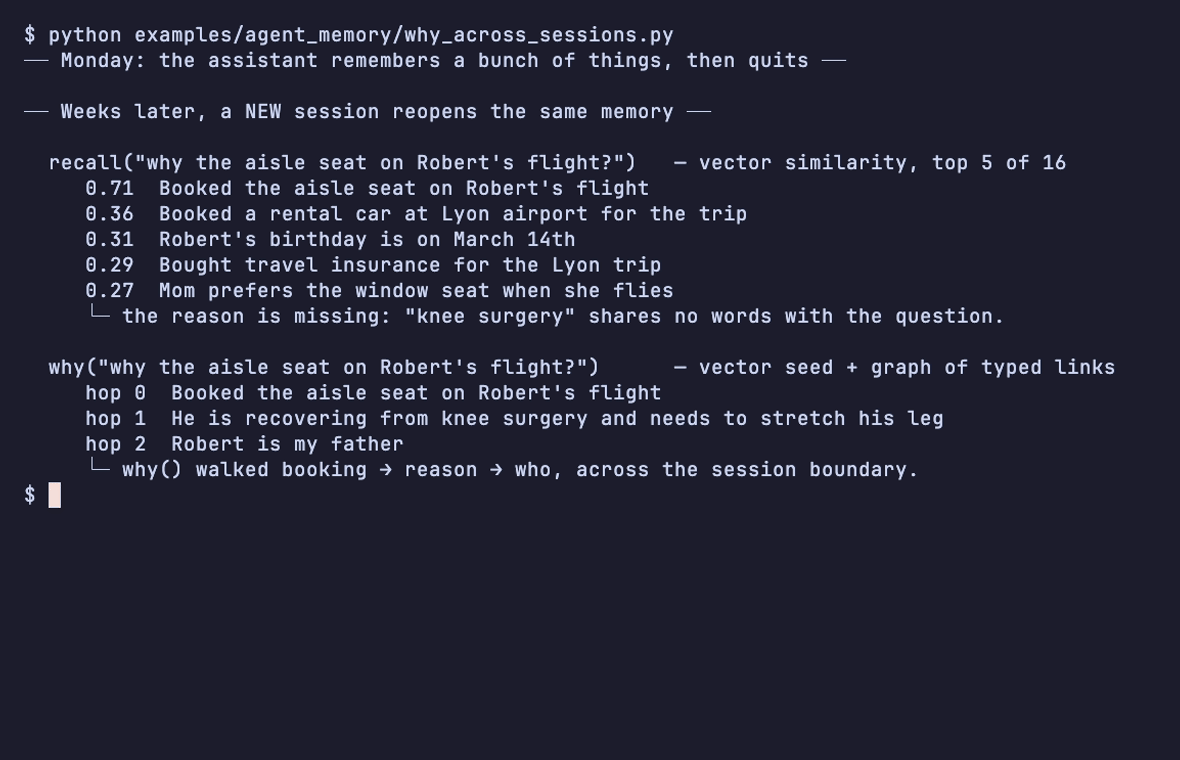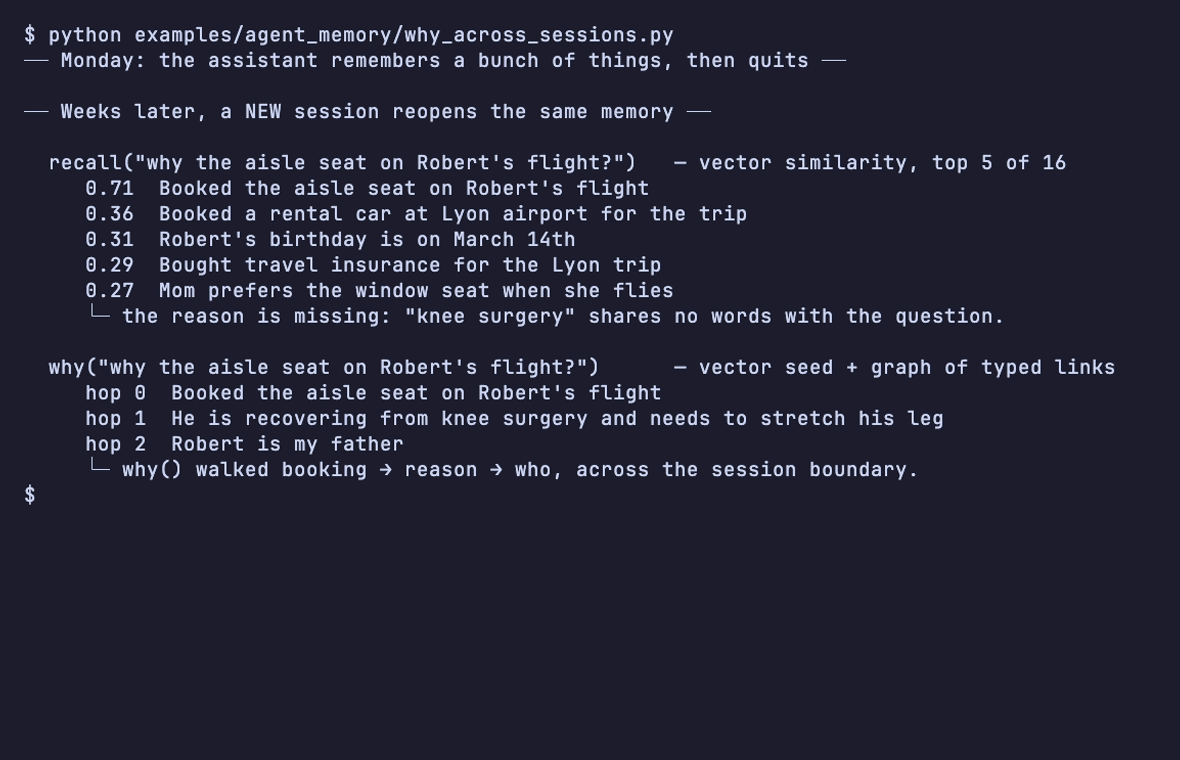
Memories are permanent by default; forget(id) deletes one, ttl_seconds gives a fact a durable expiry. Every remember auto-stamps its storage day, so recency-weighted recall works with zero setup. Same wedge in Python, Node, the MCP server, and in-memory in the TypeScript SDK.
Proof it is not a weak-embedder trick — four runnable demos in which recall stays blind to the reason even under a real semantic embedder (ollama / all-minilm), because the reason is connected by a decision rather than by surface similarity: why_across_sessions.py (survives a process restart) · why_magic_constant.py (a business reason sharing no words with the code) · memory_builds_its_own_graph.py (raw prose in, auto-wired graph out) · why_magic_constant.mjs (Node). Benchmark position, including LoCoMo and why cross-lab scores are not fairly comparable: BENCHMARK.md · Agent Memory guide.
3 · A deterministic context compiler
Agents burn most of their budget re-reading redundant context. compile_context / compile_transcript (MCP, or ContextCompiler in Rust) shrink it with no LLM and no network:
- Deterministic — the same input always compiles to the same bytes, asserted twice per run in every committed benchmark. That also yields a byte-stable cache prefix provider prompt-caching can actually hit.
- Auditable —
explain_compilationgives every kept or dropped fragment a stable rule id, a reason and a risk level. - Reversible — over-budget content becomes a recoverable
ctx://source/handle;retrieve_context_sourcebrings the original bytes back on demand. - Bounded — it compresses only what your agent explicitly hands it, never the harness's system prompt, and nothing enters recallable memory without an explicit
remember.
Code, URLs, numbers and negative constraints survive verbatim. The velesdb-context-optimizer skill teaches the workflow — including when not to compress.
Proof — three numbers, each tied to its harness
No figure here is an estimate from a slide; each links to the log or script in this repo that produced it.
| Claim | Measured | Harness |
|---|---|---|
| Real billed dollars saved, same agent session sent raw vs compiled (real Claude billing, deterministic fact-checklist grader — no LLM judge) | 21.9 % at real Retina screenshot weight, quality at parity (23.0/23 facts both arms) | real-session-benchmark · raw logs |
| Real (cl100k) input-token savings on a committed 12-turn agent-session corpus | 82.5 %, compiled in ~0.7 ms mean stateless (~24.5 ms with source persistence on) | context_savings |
| Vector search latency on the full production path (Python SDK → HNSW → payload hydration, WAL ON) | 450 us p50 (10K/384D, recall ≥ 96 %), measured 2026-03-27 on 1.7.2, when Balanced ran at ef 128 | velesdb_benchmark.py · its report |
Same campaign, less flattering: 10.9 % on cropped screenshots, 14.7 % on a 36-turn day-scale arc, 15.1 % input tokens on the direct Messages API, and 2.5 % for the no-screenshots variant — that spread is the measured value of the media mechanisms, so we publish it as prominently as the headline. Honest reading, limitations and full protocol. Every number on this page is CI-guarded by a promise contract that pins the README to its committed sources.
The full measurement tables — billed A/B runs, retrieval quality, engine micro-benchmarks
Billed A/B sessions (2026-07-19, claude-sonnet-5; raw logs committed verbatim):
| Session | Runner | $ saved | Quality (raw vs compiled) |
|---|---|---|---|
| 19-turn feature session, cropped screenshots | Claude CLI | 10.9 % | 22.8/23 vs 23.0/23 facts |
| Same session, real Retina-weight screenshots | Claude CLI | 21.9 % | 23.0/23 vs 23.0/23 |
| 36-turn day-scale session | Claude CLI | 14.7 % | 49.6/50 vs 49.2/50 * |
| 19-turn session, direct Messages API | API | 15.1 % input tokens | 23.0/23 vs 23.0/23 |
* Two turns' grading key was later found defective (both arms scored full marks there; the parity conclusion stands) — disclosure. Over a 36-turn session compiled context grows 1.7× slower, so one session lasts far longer before hitting the window.
Memory retrieval quality, public test sets, no AI grader in the loop: +7.2 pts multi-hop (HotpotQA), +9.7 pts time-scoped recall (TimeQA), +29 pts on a controlled task needing both engines at once — BENCHMARK.md.
End-to-end search (canonical): search p50 450 us (10K, 384D, WAL ON; measured 2026-03-27 on 1.7.2, Balanced then at ef 128 — harness, report) · quantization PQ (2 × dim / m smaller: dim/4 at the default m = 8), RaBitQ (32x smaller), SQ8 (4x smaller), Binary (32x smaller) — scope & caveats.
Index-only micro-benchmarks (no WAL, no payload, hot cache — not comparable to the end-to-end figure above), each reproducible with cargo bench -p velesdb-core --bench <name>: HNSW Search index-only (10K/768D, k=10) 55 us (hnsw_benchmark -- hnsw_search_latency) · SIMD Dot Product (768D, AVX2) 21.7 ns (simd_benchmark) · Recall@10 balanced 99.8% and accurate mode 100% (10K/128D, recall_benchmark) · BM25 Sparse Search index-only (10K docs, top-10) 57.6 us (sparse_benchmark -- top10_10k_corpus).
| Search mode | ef_search | Recall@10 | Use case |
|---|---|---|---|
| Fast | 96 | 97.4% | Real-time suggestions, typeahead |
| Balanced (default) | 160 | 99.8% | Production search, RAG pipelines |
| Accurate | 512 | 100% | Evaluation, ground truth comparison |
ef_search is each preset's base value, used as-is for k ≤ 32 on up to 10K vectors; ef_search_for_scale raises it beyond. Recall@10: recall_benchmark, 10K/128D, 2026-09-10 on Apple M5 Pro.
Distance metrics — 5 with SIMD acceleration (AVX-512, AVX2, NEON). At 768D on the i9-14900KF reference (AVX2, hot cache; the April 3, 2026 run in docs/BENCHMARKS.md §1): Cosine 32 ns · Euclidean 26 ns · Dot Product 22 ns · Hamming 35 ns · Jaccard 27 ns.
ColumnStore — typed columnar filtering, 130x faster than JSON scanning at 100K rows on the i9-14900KF reference (JSON scan 3.84 ms → ColumnStore 29.5 us). The ratio is hardware-dependent: on Apple Silicon (M5 Pro, 2026-07-20) the JSON scan itself runs ~2.8× faster, so the same bench measures ~50–105x while the ColumnStore's absolute time holds (~27 µs).
Provenance: Intel Core i9-14900KF (x86_64, AVX2). Per-machine figures vary; Apple-Silicon cross-checks, the SIFT1M standardized ANN run and the full methodology live in docs/BENCHMARKS.md. Reproduce the end-to-end figure with
python benchmarks/velesdb_benchmark.py --recall.
Pick your entry point
| I want to… | Use | Notes |
|---|---|---|
| Try it in one file | velesdb (Python 3.9+) | Fastest onboarding path |
| Embed the engine | velesdb-core (Rust) | The engine itself |
| Give my agent memory | velesdb-memory | MCP server + context compiler, any MCP client; .mcpb bundles on the MCP Registry |
| Call it from Node | @wiscale/velesdb-memory-node | Memory wedge (full engine via server + TS SDK) |
| Run it in a browser | @wiscale/velesdb-sdk | WASM, ~710 KB gzipped, fully client-side |
| Serve it over HTTP | velesdb-server | 54 REST endpoints — API reference · OpenAPI · server security |
| Ship on mobile/desktop | velesdb-mobile · Tauri plugin | iOS / Android / desktop |
Tool parity per surface is published honestly — including where a surface is still behind: memory crate README. Worked examples: examples/.
Serving it over HTTP — the 54 REST endpoints, by category
| Category | Key Endpoints |
|---|---|
| Collections | POST /collections, GET /collections, GET/DELETE /collections/{name} |
| Points | /collections/{name}/points, /collections/{name}/points/raw, /collections/{name}/points/scroll, /collections/{name}/stream/insert, /collections/{name}/stream/enable, /collections/{name}/points/{id}/relations, /collections/{name}/points/{id}/ttl, /collections/{name}/relations |
| Search | /collections/{name}/search, /collections/{name}/search/batch, /collections/{name}/search/hybrid, /collections/{name}/search/text, /collections/{name}/search/multi, /collections/{name}/search/ids, /collections/{name}/match |
| Graph | /collections/{name}/graph/edges, /collections/{name}/graph/edges/{id}, /collections/{name}/graph/edges/count, /collections/{name}/graph/traverse, /collections/{name}/graph/traverse/stream, /collections/{name}/graph/traverse/parallel, /collections/{name}/graph/nodes, /collections/{name}/graph/nodes/{id}/degree, /collections/{name}/graph/nodes/{id}/edges, /collections/{name}/graph/nodes/{id}/payload, /collections/{name}/graph/search |
| Indexes | GET/POST /collections/{name}/indexes, DELETE /collections/{name}/indexes/{label}/{property}, /collections/{name}/index/rebuild |
| VelesQL | /query, /aggregate, /query/explain |
| Admin | /health, /ready, /metrics, /guardrails, /collections/{name}/stats, /collections/{name}/config, /collections/{name}/flush, /collections/{name}/analyze, /collections/{name}/empty, /collections/{name}/sanity, /collections/{name}/compact, /collections/{name}/vacuum |
Full API reference: docs/reference/api-reference.md | OpenAPI spec: docs/openapi.yaml | Server security: docs/guides/SERVER_SECURITY.md
How it compares
| VelesDB | Chroma | Qdrant | pgvector | |
|---|---|---|---|---|
| Architecture | Vector + graph + columnar, unified | Vector only | Vector + payload | Vector extension for PostgreSQL |
| Metadata filtering | Typed ColumnStore + secondary indexes | JSON scan | JSON payload | SQL |
| Graph support | Native (MATCH clause) | No | No | No |
| Query language | VelesQL (SQL + NEAR + MATCH) | Python API | JSON API / gRPC | SQL + operators |
| Embeddings from text | Opt-in local / OpenAI adapters; no bundled model | Embedding functions, with a default local model in Python/TypeScript | Opt-in client-side FastEmbed | None; bring vectors from an external model |
| Deployment | Embedded / Server / WASM / Mobile | Server (Python) | Server (Rust) | Requires PostgreSQL |
| Binary size | ~14 MB | ~500 MB (with deps) | ~50 MB | N/A (PG extension) |
| Browser / Mobile | Yes / Yes | No | No | No |
| Offline / Local-first | Yes | Partial | No | No |
Sweet spot: vector + graph + structured filtering in one engine, local-first, auditable. Not the best fit (yet): a managed cloud service with a multi-node distributed cluster. Competitor figures are typical public ranges, not a head-to-head run we performed — run your own. Detailed comparison against agent-memory products (Mem0, Zep, Letta), as of mid-2026: docs/WHY_VELESDB.md.
VelesDB Premium — the enterprise control plane
The core engine is source-available and stays that way. Premium adds the company-grade layer on top of the same binary, for organizations running agent fleets on sensitive data: RBAC on every endpoint including the memory and context-compiler surfaces · audit trail (who, what, when — metadata only, GDPR-conscious) with forensic replay · multi-tenancy with hard per-tenant isolation and two-level deletion rights · clustering and air-gapped deployment · a WebAdmin UI for operators.
Pricing on quote — contact@wiscale.fr · velesdb.com. Built by Wiscale (France; GDPR and data-sovereignty native).
Known limitations — honest boundaries
The items below are deliberate trade-offs or Premium-tracked features, not correctness gaps — the Community Edition is production-ready for single-node, local-first deployments. We publish them next to the strengths, including the ones we have not fixed yet.
| # | Limitation | Scope | Tracked |
|---|---|---|---|
| 1 | Single writer per collection — WAL is serialized; concurrent writers contend on the same fsync lock. | Design trade-off (local-first, crash-safe by default). Read throughput is unaffected. | Concurrent WAL writer planned for Premium. See docs/CONCURRENCY_MODEL.md. |
| 2 | No distributed replication — single-node; no Raft, no sharding, no automatic failover in Core. | Deliberate: the sweet spot is local-first / embedded. | Raft-based replication tracked for Premium. |
| 3 | No advanced RBAC / multi-tenant isolation in Core — Core ships the DatabaseObserver enforcement seam — live on every HTTP read path since 3.10.0 and still current in 4.0.0 — not the policy engine. | Core ships the hook, not the policy engine. | Premium feature. |
| 4 | WASM MATCH limited to 2 hops — 3+ hop MATCH works fully in native builds. | Browser-build scope limit, not a correctness issue. | Tracked. |
| 5 | SIFT1M fingerprint sidecar not yet committed — the loader falls back to TOFU mode until the reference machine commits the pinned hashes. | Not a correctness issue — shape validation still applies. | Bootstrap shipped; sidecar pending. |
| 6 | No head-to-head Docker Compose benchmark vs Qdrant / Chroma / FAISS yet — SIFT1M already gives literature-comparable numbers. | Side-by-side numbers need infrastructure not frozen yet. | Tracked. |
| 7 | Context-compiler tool parity varies by surface — the MCP server and Rust have the full set; Node, Python and WASM are partially behind, and the WASM working contexts are intra-session only. | Binding scope, not an engine gap; MCP covers any client meanwhile. | Per-surface table in the memory crate README. |
Internal technical limitations (query-planner approximations, plan-cache semantics): docs/reference/KNOWN_LIMITATIONS.md.
Contributing & contact
Quality bar: cargo test --workspace — 9k+ tests across Rust, TypeScript and Python run in CI on every merge; exact commands in QUALITY_BAR.md.
Contributions welcome — start with CONTRIBUTING.md and the good first issues. Security reports: SECURITY.md. Roadmap: ROADMAP.md · Changelog · DeepWiki.
License: VelesDB Core License 1.0 (source-available). Premium: commercial license. Contact: contact@wiscale.fr · velesdb.com
The name nods to Veles, a deity of old Slavic myth — a keeper of hidden knowledge and boundaries.
Compatibility
- Runs on
- WebGPU
What shows it
- WebGPU: velesdb-core feature gpu (dependency wgpu)
- Native code
- Required
- Binds native code: tauri, tauri-plugin-velesdb, atk-sys, gdk-pixbuf-sys, gdk-sys and 9 more
- Python bindings
- No Python binding crate found
- License
- Not measured
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
High-performance vector database engine written in Rust |
2,396 downloads over 30 days | 0 | 102 | 8.1.0 | WebGPU | Binds native code: tauri, tauri-plugin-velesdb, atk-sys, gdk-pixbuf-sys, gdk-sys and 9 more | Not measured |
|
Qdrant - High-performance, massive-scale Vector Database and Vector Search Engine for the next generation of AI. Also available in the cloud https://cloud.qdrant.io/ Also in Text, embeddings and search. |
34,017 binary downloads per release | Not applicable | 35,478 | Not measured | Not measured | Apache-2.0 | |
|
ruvector Listed
High-performance Rust vector database core with HNSW indexing Also in Build LLM apps and agents. |
39,411 downloads over 30 days | 51 | 4,675 | 2.5.0 | CUDA, WebGPU, Metal | Binds native code: libsqlite3-sys, napi-sys, ort-sys, pgrx-pg-sys, pqcrypto-internals and 5 more | MIT |
|
regexr Listed
A high-performance regex engine built from scratch with JIT compilation and SIMD acceleration Also in Text, embeddings and search. |
8,809 downloads over 30 days | 4 | 28 | 0.6.2 | GPU support unknown | No native code found | Apache-2.0 OR MIT |
|
mentedb Listed
A purpose-built database engine for AI agent memory Also in Build LLM apps and agents. |
1,605 downloads over 30 days | 1 | 124 | 0.47.1 | GPU support unknown | No native code found | Apache-2.0 |
|
hyperspace-db Listed
[H] HyperspaceDB is a high-performance, vector database. It features 1-bit quantization, async replication, and native support for hierarchical datasets (Lorentz, Poincaré ball & Hybrid models). Also in Text, embeddings and search. |
96 downloads over 30 days | 3 | 163 | 4.2.0 | GPU support unknown | Binds native code: ort-sys (feature local-onnx) | MIT |
|
High performance embedded vector database Also in Build LLM apps and agents. |
0 binary downloads per release | Not applicable | 245 | Not measured | Not measured | MIT |
All projects in Build LLM apps and agentsAll projects in Text, embeddings and search
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- It has 0 active dependents and 0 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days. The repository route reads 102 stars, 13 forks and 7 contributors. It needs 4,539 stars, 434 forks and 79 contributors together.
What else the check found
- The last activity is on 9 Nov 2026, 0 days ago. The rules expect an update within 365 days. Dormancy rule
Exact rules: Listed, Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 8.1.0 base 200, raised to the 365-day floor: E = 365 daysdormancy: last activity 2026-11-09, 0 days ago, E = 365: activefeatured: not featured: active_users 0 < 11 and new_adopters 0 < 9 and repository route stars 102 (needs 4539), forks 13 (needs 434), contributors 7 (needs 79)listed: listed: no archive, new or featured rule applies
Crates8 crates
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption0 active dependents, 0 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 0 | crates.io database dump | Yes | |
| New dependents (365 days) | 0 | crates.io database dump | Yes | |
| Peak active dependents | 0 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: on the check date3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-09 | GitHub repository | Yes | |
| Latest release | 2026-11-06 | crates.io database dump | Yes | |
| First release | 2025-12-20 | crates.io database dump | Yes | |
| Latest version | 8.1.0 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 0 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 52 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | none | crates.io database dump | Yes |
Distribution100 releases, 2,396 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 100 | crates.io database dump | Yes | |
| Downloads over 30 days | 2396 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository102 stars, 13 forks, 7 contributors, 4,899 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 102 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 13 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 7 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 4899 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | Not measured | No | ||
| Runs on, from listed crates and their direct dependencies | WebGPU | crates.io database dump | No | |
| What shows each backend | WebGPU: velesdb-core feature gpu (dependency wgpu) | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: tauri, tauri-plugin-velesdb, atk-sys, gdk-pixbuf-sys, gdk-sys and 9 more | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 0 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.