aprender
Library Listed
Next-generation ML framework in pure Rust — `cargo install aprender` for the `apr` CLI
- Downloads
- 15,442
- Dependents
- 31
- Stars
- 140
- Forks
- 25
- Contributors
- 6
- Commits
- 4,744
- Latest release
- 0.72.3 ·
About
schema_version: "1.0" kind: library entrypoints: [crates/aprender-contracts-cli] contract_count: 1837
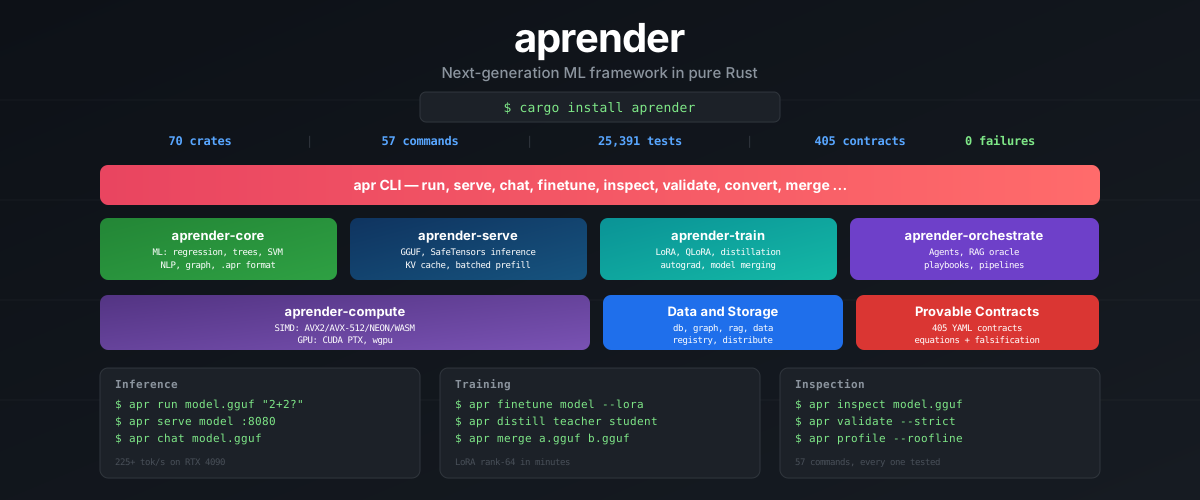
Quick Start
Pre-built and ready to use (Linux x86_64/aarch64 only today — other platforms fall
through to cargo install below):
curl -LsSf https://paiml.com/apr/install.sh | sh
To read the script before it runs, download it with curl -LsSf https://paiml.com/apr/install.sh -o install.sh, review it, then run sh install.sh. The installer is POSIX sh and checks the downloaded release archive against its published .sha256 before installing.
Compile and build:
cargo install aprender                    # CPU ONLY - no GPU backend is compiled in
cargo install aprender --features cuda    # NVIDIA GPU acceleration
cargo install aprender --features full    # everything (training, visualization, zram)
apr pull hf://Qwen/Qwen2.5-Coder-0.5B-Instruct
apr list
apr run ~/.cache/pacha/models/1e3be9285aea6923.safetensors "2+2?"
full log of output
Read the full README
apr pull hf://Qwen/Qwen2.5-Coder-0.5B-Instruct
== APR Pull ===

Model: hf://Qwen/Qwen2.5-Coder-0.5B-Instruct/model.safetensors

Downloading (streaming)...
 10% 20% 30% 40% 50% 60% 70% 80% 90% 100%
✓ Downloaded successfully
  Path: ~/.cache/pacha/models/1e3be9285aea6923.safetensors
  Size: 942.3 MB
...
Usage:
  apr run ~/.cache/pacha/models/1e3be9285aea6923.safetensors
  apr serve ~/.cache/pacha/models/1e3be9285aea6923.safetensors

apr list
=== Cached Models ===

NAME                                     SIZE         FORMAT       PATH
--------------------------------------------------------------------------------------------------------
1e3be9285aea6923                         942.3 MB     SafeTensors  ~/.cache/pacha/models/1e3be9285aea6923.safetensors (orphan)

Total: 1 models (0 tracked + 1 orphans), 942.3 MB used
apr run ~/.cache/pacha/models/1e3be9285aea6923.safetensors "what is 2+2?"
=== APR Run ===

Source: ~/.cache/pacha/models/1e3be9285aea6923.safetensors
[GH-189] Loaded tokenizer from ~/.cache/pacha/models/1e3be9285aea6923.tokenizer.json: 22 special tokens

Output:
2 + 2 equals 4.

Completed in 4.82s (cached)

apr run ~/.cache/pacha/models/1e3be9285aea6923.safetensors "can you help me summarize quick sort algorithm, in less than 100 words"
=== APR Run ===

Source: ~/.cache/pacha/models/1e3be9285aea6923.safetensors
[GH-189] Loaded tokenizer from ~/.cache/pacha/models/1e3be9285aea6923.tokenizer.json: 22 special tokens

Output:
Quick sort is a divide-and-conquer algorithm that sorts an array of elements. It works by selecting a 'pivot' element from the array and partitioning the

Completed in 7.03s (cached)
$
For release notes see GitHub Releases.
What is Aprender?
A complete ML framework in pure Rust. One cargo install, one apr binary,
the full model lifecycle — inference, training, quantization, profiling,
publishing — all backed by YAML provable contracts that fail CI on drift.
At HEAD
| Metric | Count | Source of truth |
|---|---|---|
| Workspace crates | 81 workspace crates | cargo metadata --no-deps (NOT ls crates/ — 4 are excluded, 1 has no Cargo.toml) |
| Provable contracts | 2010 provable contracts | contracts/census.json .n_files — the set pv lint walks (pv census, ONT-001 ONT-1; regenerated by make contracts, written by make readme-sync, guarded by scripts/check_readme_claims.sh) |
| CLI commands | 113 CLI commands | contracts/apr-cli-commands-v1.yaml §commands (parse the list; apr --help also lists help itself, and grep -c '^ - name:' gives 119 — other same-indent name: keys exist in the file) |
| Book CLI chapters | 114 chapters | ls book/src/cli/*.md |
| Book lib chapters | 73 chapters | ls book/src/lib/*.md (parity with pub mod) |
These numbers are enforced by contracts/readme-claims-v1.yaml.
Drift between this table and live repo state fails bash scripts/check_readme_claims.sh
→ see FALSIFY-README-001..006.
Verified this release
Verified matrix for 0.69.1, from the ladder receipts:
A pass cell means apr run completed on that host without falling back and its golden output matched. It does not mean chat, code and serve passed: the ladder records those verbs but its green does not read them.
A non-pass cell names the gates the receipt records, which is not always the cause: a reason apr qa computed in the same run is not carried here unless the receipt accounts for it (qa_rc is the tell).
| Model rung | gx10 | lambda |
|---|---|---|
qwen2-1.5b-q4km | pass | pass |
qwen3-1.7b-q4km | pass | pass |
qwen3-8b-q4km | pass | pass |
qwen35-0.8b-q4km | pass | pass |
qwen35-2b-q4km | pass | pass |
qwen35-4b-q4km | pass | pass |
qwen35-9b-q4km | pass | pass |
qwen35-27b-q4km | FAIL | pass |
inv:Qwen3-30B-A3B-Instruct-2507-Q4_K_M.gguf | FAIL | FAIL |
inv:Qwen3-Coder-30B-A3B-Instruct-Q4_K_M.gguf | FAIL | FAIL |
inv:qwen2.5-coder-0.5b-instruct-q4_k_m.gguf | pass | pass |
inv:qwen2.5-coder-1.5b-instruct-fp16.apr | pass | — |
inv:qwen2.5-coder-1.5b-instruct-q4_k_m.apr | pass | — |
inv:qwen2.5-coder-1.5b-instruct-q4_k_m.gguf | pass | pass |
inv:qwen2.5-coder-1.5b-instruct-q4k.apr | pass | pass |
inv:qwen2.5-coder-32b-instruct-q4_k_m.gguf | pass | — |
inv:qwen2.5-coder-7b-instruct-q4_k_m.gguf | pass | pass |
inv:Qwen2.5-0.5B-Instruct-IQ3_M.gguf | — | pass |
inv:Qwen2.5-0.5B-Instruct-IQ4_XS.gguf | — | pass |
inv:Qwen2.5-0.5B-Instruct-f16.gguf | — | FAIL |
inv:Qwen3.5-0.8B-IQ4_XS.gguf | — | FAIL |
inv:Qwen3.5-0.8B-UD-IQ2_XXS.gguf | — | FAIL |
inv:Qwen3.5-35B-A3B-UD-IQ4_XS.gguf | — | FAIL |
inv:Qwen3.5-4B-UD-Q4_K_XL.gguf | — | pass |
inv:qwen2.5-coder-0.5b-instruct.apr | — | FAIL |
inv:qwen2.5-coder-1.5b-instruct-q4k-v2.apr | — | pass |
inv:qwen2.5-coder-1.5b-instruct-st.apr | — | pass |
inv:qwen2.5-coder-1.5b-q4k.apr | — | pass |
inv:tinyllama-1.1b-chat-v1.0.Q4_K_M.gguf | — | pass |
- gx10: 17 rung(s), 17 required, 3 not green —
apr 0.69.1 (9b7739951) - lambda: 26 rung(s), 26 required, 7 not green —
apr 0.69.1 (9b7739951)
Known issue — Qwen3 MoE (30B-A3B) on GB10: not claimed for 0.70; planned for 0.70.1 (#3715). Every verb times out at 600 s on the 20k-token rung on GB10 (sm_121), so qwen3moe on GB10 is withdrawn from this release's claims (
cells.declaimed).
Known issue — GB10 dense models: prompt processing unbatched; planned for 0.70.1 (#4590). Output is correct; only prefill speed is affected. On GB10 (sm_121) every dense model (Qwen2.5, Qwen3) is withdrawn from this release's claims (
cells.declaimedincontracts/model-capability-ladder-v1.yaml); Qwen3.5 on GB10 and every model on other hosts are still claimed and gated.
Command surface
| Stage | Commands |
|---|---|
| Inference | apr run, apr chat, apr serve |
| Training | apr finetune, apr train, apr pretrain, apr distill |
| Model ops | apr convert, apr quantize, apr merge, apr export, apr compile |
| Inspection | apr inspect, apr validate, apr tensors, apr diff, apr trace, apr lint |
| Profiling | apr profile, apr bench, apr qa |
| Registry | apr pull, apr list, apr rm, apr publish, apr registry |
| GPU | apr gpu, apr parity, apr ptx |
| Observability | apr tui, apr monitor, apr cbtop |
Cookbook
End-to-end recipes (data prep → train → quantize → publish → serve) live in
paiml/apr-cookbook — 1,825 worked examples (apr-cookbook, 2026-09-12),
with local book/src/ walkthroughs. The count is the
[[example]] entries the cookbook declares, pinned and gated by
contracts/readme-claims-v1.yaml — it lives in another
repository, so it carries the date it was measured rather than pretending to be live.
git clone https://github.com/paiml/apr-cookbook
cd apr-cookbook
cargo run --example bundle_static_model         # any example
mdbook serve book                               # walkthrough docs
Install
cargo install aprender    # installs the `apr` binary
apr --version
A Qwen story
Eight beats, one narrative, every core command group. Anchored on the Qwen
series so the story scales from a 494-MB safetensors model to a 30 B-parameter
MoE GGUF. Every beat is a falsifier in
contracts/qwen-story-v1.yaml; the runnable
form is scripts/qwen-story.sh; nightly cron is
.github/workflows/qwen-story-daily.yml;
the dogfood gate is /apr-dogfood Gate 18.
# Reproduce locally (uses ~/models cache; ~3-5 min on RTX 4090):
bash scripts/qwen-story.sh
Beat 1 — Discover (Registry)
apr pull hf://Qwen/Qwen2.5-Coder-0.5B-Instruct      # 494 MB safetensors
apr list                                            # confirm cached
Beat 2 — Trust (QA gates)
apr qa qwen2.5-coder-1.5b-instruct-q4k              # 12 falsifiable gates
apr validate qwen2.5-coder-1.5b-instruct-q4k --quality   # scores the checks that ran
apr lint qwen2.5-coder-1.5b-instruct-q4k            # best-practice signals
Beat 3 — Explore (Inspection)
apr inspect --json qwen2.5-coder-1.5b-instruct-q4k  # arch, params, tensors
apr tensors --json qwen2.5-coder-1.5b-instruct-q4k  # 339 tensors with shapes
apr tree qwen2.5-coder-1.5b-instruct-q4k            # layer architecture
Beat 4 — Adapt (Model ops)
apr export qwen2.5-coder-1.5b-instruct-q4k --format gguf -o roundtrip.gguf
apr diff qwen2.5-coder-1.5b-instruct-q4k roundtrip.gguf  # tensor-by-tensor delta
apr convert model.safetensors --quantize q4_k -o quantized.apr
Beat 5 — Use (Inference)
apr run qwen2.5-coder-1.5b-instruct-q4k "fn sum(a: i32, b: i32) -> i32 {" --max-tokens 16
apr chat qwen2.5-coder-1.5b-instruct-q4k            # interactive REPL
apr code -p "review this Python function" --max-turns 1   # agent mode (PMAT-182)
Beat 6 — Serve (REST API)
apr serve run qwen2.5-coder-1.5b-instruct-q4k --port 8080
curl -s localhost:8080/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"qwen","messages":[{"role":"user","content":"What is 2+2?"}],"max_tokens":8}'
# → {"choices":[{"message":{"content":"2 + 2 equals 4."}}],...}
Beat 7 — Operate (Profiling)
apr profile qwen2.5-coder-7b-instruct-q4_k_m        # Roofline analysis
apr gpu --json                                      # VRAM, sm_*, cuda version
apr serve plan qwen2.5-coder-7b-instruct-q4_k_m     # capacity plan before run
Beat 8 — Scale (MoE introspection)
apr inspect --json Qwen3-Coder-30B-A3B-Instruct     # arch=qwen3moe, 30 B params
apr tensors --json Qwen3-Coder-30B-A3B-Instruct     # 579 tensors (MoE expert layout)
0.69.1 does not support
qwen3moeon CUDA. Mixture-of-experts models (Qwen3-30B-A3B-Instruct-2507,Qwen3-Coder-30B-A3B-Instruct) run on the CPU only:apr run <model>works, andapr run --gpu <model>refuses before loading, naming the architecture and exiting 12 rather than generating on the CPU and reporting a fallback. The MoE GPU forward is #3714 and lands in 0.70.0. Introspection above (inspect,tensors) is unaffected — it reads the header, not a forward.
Publish (separate flow)
# Publish a derived model to HuggingFace Hub (see SPEC-HF-PUBLISH-001 for the 12-file pipeline)
apr stamp ckpt.apr --tokenizer /path/to/qwen-tokenizer --license Apache-2.0 -o staging/model.apr
apr export staging/model.apr --format gguf --quantize int4 -o staging/model-q4k.gguf
apr publish staging/ paiml/my-model-v1 --library-name aprender --license Apache-2.0
When run with PMAT_HUNT=1 (default), each beat emits a manifest of high-risk
untested code in the command modules it just exercised. A nightly cron opens an
issue when this manifest grows so untested branches in command handlers can't
accumulate quietly. See contracts/qwen-story-v1.yaml.
Publishing a model? See SPEC-HF-PUBLISH-001 for the 12-file integration pipeline, three-path verification protocol, and HF API gotchas (NDJSON commits, LFS batch sizing, Q4_K stride constraints).
Library usage
[dependencies]
aprender = "0.35"
use aprender::linear_regression::LinearRegression;
use aprender::traits::Estimator;

let model = LinearRegression::new();
model.fit(&x_train, &y_train)?;
let predictions = model.predict(&x_test)?;
Algorithms: Linear/Logistic Regression, Decision Trees, Random Forest, GBM, Naive Bayes, KNN, SVM, K-Means, PCA, ARIMA, ICA, GLMs, graph algorithms, Bayesian inference, text + audio processing.
Architecture
Monorepo, flat crates/aprender-* layout (same pattern as
Polars,
Burn,
Nushell):
paiml/aprender/
├── Cargo.toml                      # Workspace root + `cargo install aprender`
├── crates/
│   ├── aprender-core/              # ML library (use aprender::*)
│   ├── apr-cli/                    # CLI logic (count in the table above)
│   ├── aprender-compute/           # SIMD/GPU compute kernels
│   ├── aprender-gpu/               # CUDA PTX
│   ├── aprender-serve/             # Inference server
│   ├── aprender-train/             # Training loops
│   ├── aprender-orchestrate/       # Agents + RAG
│   ├── aprender-contracts/         # Provable contracts engine
│   ├── aprender-profile/           # Profiling
│   ├── aprender-db/ aprender-graph/ aprender-rag/
│   └── ... (**84** directories — NOT the crate count: see the table above)
├── contracts/                      # provable YAML contracts (count in the table above)
└── book/                           # mdBook documentation
Performance
Every published throughput or comparator figure lives with the run that produced
it. The measurement ledger is evidence/parity/LEDGER.md;
the rules a figure must satisfy before it may be quoted anywhere — including on
this page — are in
docs/specifications/PP-LLAMA-001-MASTER.md.
This section carried a three-row table of tok/s figures until 2026-09-02. None
of the three cited a receipt, and the RTX 4090 row asserted a rate the tree's own
paired measurement contradicts, so all three are withdrawn rather than restated
(PP-LLAMA-001 §2.1, PP-12). A withdrawal that reprints the number leaves the
number on the page.
The harnesses that reproduce the comparisons, without their numbers: candle-vs-apr for inference and ground-truth-apr-ludwig for training. A figure from either belongs on this page only once it carries a receipt in the ledger.
Provable contracts
Every CLI command and kernel is bound to a YAML contract with equations, preconditions, postconditions, and falsification tests:
equations:
  validate_exit_code:
    formula: exit_code = if score < 50 then 5 else 0
    invariants:
    - score < 50 implies exit_code != 0
falsification_tests:
- id: FALSIFY-CLI-001
  prediction: apr validate bad-model.apr exits non-zero
The tree carries 2010 contracts across inference, training, quantization, attention, FFN, tokenization, model formats, CLI safety — and this README itself.
Migration from old crates
| Old | New | Status |
|---|---|---|
trueno = "0.18" | aprender-compute = "0.33" | Shim available |
entrenar = "0.7" | aprender-train = "0.33" | Shim available |
realizar = "0.8" | aprender-serve = "0.33" | Shim available |
batuta = "0.7" | aprender-orchestrate = "0.33" | Shim available |
Old repositories are archived. All development happens here.
Contributing
git clone https://github.com/paiml/aprender
cd aprender
cargo test --workspace --lib
cargo check --workspace
apr --help
The README's own gate — a merge-path CI step runs exactly this line, which is what lets this fence stay bash:
setsid --wait bash scripts/check_readme_claims.sh # README contract gate (as CI runs it)
License
MIT
Compatibility
- Runs on
- CUDA, WebGPU
What shows it
- CUDA: aprender feature cuda, apr-cli feature cuda, aprender-cbtop feature cuda, aprender-cgp feature cuda, aprender-compute feature cuda, aprender-core feature cuda, aprender-cuda-edge feature cuda, aprender-gpu feature cuda, aprender-profile feature cuda-tracing (dependency cudarc), aprender-serve feature cuda, aprender-train feature cuda, aprender-train-distill feature cuda, aprender-zram feature cuda, aprender-zram-core feature cuda (dependency cudarc)
- WebGPU: aprender feature wgpu, apr-cli feature wgpu, aprender-compute feature gpu (dependency wgpu), aprender-db feature gpu (dependency wgpu), aprender-distribute feature gpu (dependency wgpu), aprender-gpu feature wgpu (dependency wgpu), aprender-graph feature gpu (dependency wgpu), aprender-present-lib feature gpu (dependency wgpu), aprender-profile feature gpu-tracing (dependency wgpu)
- Native code
- Required
- Binds native code: libsqlite3-sys, zstd-sys, tree-sitter (feature full), alsa-sys (feature audio-alsa), nvml-wrapper-sys (feature nvml) and 1 more
- Build uses a native toolchain: bindgen (feature bindgen)
- Python bindings
- No Python binding crate found
- License
- MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Next-generation ML framework in pure Rust — `cargo install aprender` for the `apr` CLI |
15,442 downloads over 30 days | 31 | 140 | 0.72.3 | CUDA, WebGPU | Binds native code: libsqlite3-sys, zstd-sys, tree-sitter (feature full), alsa-sys (feature audio-alsa), nvml-wrapper-sys (feature nvml) and 1 more. Build uses a native toolchain: bindgen (feature bindgen) | MIT |
|
tch-rs Featured
Rust wrappers for the PyTorch C++ api (libtorch). Python bindings |
1,190,464 downloads over 30 days | 124 | 5,518 | 0.26.0 | CUDA | Binds native code: tch, torch-sys. Build uses a native toolchain: cc | Apache-2.0 OR MIT |
|
burn Featured
Flexible and Comprehensive Deep Learning Framework in Rust |
521,465 downloads over 30 days | 391 | 16,257 | 0.22.1 | CUDA, WebGPU, Metal, ROCm, Vulkan | Binds native code: netlink-sys (feature iroh), nvml-wrapper-sys (feature sys-metrics), torch-sys (feature tch) | Apache-2.0 OR MIT |
|
mlx-rs Featured
Unofficial rust wrapper for Apple's mlx machine learning library. |
33,398 downloads over 30 days | 36 | 389 | 0.34.0 | Metal | Binds native code: mach-sys, mlx, mlx-sys. Build uses a native toolchain: bindgen, cc, cmake | Apache-2.0 OR MIT |
|
boostr Listed
ML framework on numr for training and inference on CPU, CUDA and WebGPU: attention, quantization, inference scheduling and distributed execution. Models include LLaMA, Mamba2, Qwen3.5, Whisper, Kokoro, VITS, VoxCPM2, Silero VAD, CLAP and super-resolution. Loads SafeTensors and GGUF. |
1,265 downloads over 30 days | 7 | 20 | 0.11.2 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
Modern Rust bindings for Apple's Metal Performance Shaders Graph framework |
398 downloads over 30 days | 2 | Not measured | 0.2.0 | Metal | No native code found | MIT |
|
ruv-fann Listed
A pure Rust implementation of the Fast Artificial Neural Network (FANN) library Python bindings |
270 downloads over 30 days | 7 | 388 | 0.2.1 | CUDA, WebGPU | Binds native code: libsqlite3-sys, win-sys, torch-sys (feature neural-networks). Build uses a native toolchain: cc | Apache-2.0 OR MIT |
All projects in Tabular data and classic MLAll projects in Train models
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- It has 0 active dependents and 0 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days. The repository route reads 140 stars, 25 forks and 6 contributors. It needs 4,539 stars, 434 forks and 79 contributors together.
What else the check found
- The last activity is on 8 Nov 2026, 1 day ago. The rules expect an update within 365 days. Dormancy rule
Exact rules: Listed, Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 0.72.3 base 300, raised to the 365-day floor: E = 365 daysdormancy: last activity 2026-11-08, 1 days ago, E = 365: activefeatured: not featured: active_users 0 < 11 and new_adopters 0 < 9 and repository route stars 140 (needs 4539), forks 25 (needs 434), contributors 6 (needs 79)listed: listed: no archive, new or featured rule applies
Crates77 crates
- aprender Primary
- apr-cli
- apr-format
- aprender-build-sha
- aprender-cbtop
- aprender-cgp
- aprender-common
- aprender-compute
- aprender-contracts
- aprender-contracts-cli
- aprender-contracts-macros
- aprender-contrastive-data
- aprender-core
- aprender-cuda-edge
- aprender-cupti
- aprender-data
- aprender-db
- aprender-distribute
- aprender-explain
- aprender-fft
- aprender-gpu
- aprender-graph
- aprender-image
- aprender-mcp
- aprender-monte-carlo
- aprender-orchestrate
- aprender-present-cli
- aprender-present-core
- aprender-present-layout
- aprender-present-lib
- aprender-present-terminal
- aprender-present-test
- aprender-present-test-macros
- aprender-present-widgets
- aprender-present-yaml
- aprender-profile
- aprender-profile-core
- aprender-ptx-debug
- aprender-qa-certify
- aprender-qa-gen
- aprender-quant
- aprender-rag
- aprender-rag-cli
- aprender-rand
- aprender-registry
- aprender-serve
- aprender-shell
- aprender-simulate
- aprender-solve
- aprender-sparse
- aprender-tensor
- aprender-test-cli
- aprender-test-derive
- aprender-test-js-gen
- aprender-test-lib
- aprender-test-showcase
- aprender-train
- aprender-train-bench
- aprender-train-common
- aprender-train-distill
- aprender-train-inspect
- aprender-train-lora
- aprender-train-shell
- aprender-tsp
- aprender-update
- aprender-verify
- aprender-verify-ml
- aprender-viz
- aprender-zram
- aprender-zram-adaptive
- aprender-zram-cli
- aprender-zram-core
- aprender-zram-generator
- forjar-contracts
- forjar-contracts-macros
- provable-contracts
- provable-contracts-macros
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption0 active dependents, 0 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 0 | crates.io database dump | Yes | |
| New dependents (365 days) | 0 | crates.io database dump | Yes | |
| Peak active dependents | 0 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: 1 day ago3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-08 | GitHub repository | Yes | |
| Latest release | 2026-11-02 | crates.io database dump | Yes | |
| First release | 2025-11-18 | crates.io database dump | Yes | |
| Latest version | 0.72.3 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 0 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 137 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | none | crates.io database dump | Yes |
Distribution94 releases, 15,442 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 94 | crates.io database dump | Yes | |
| Downloads over 30 days | 15442 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository140 stars, 25 forks, 6 contributors, 4,744 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 140 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 25 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 6 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 4744 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | CUDA, WebGPU | crates.io database dump | No | |
| What shows each backend | CUDA: aprender feature cuda, apr-cli feature cuda, aprender-cbtop feature cuda, aprender-cgp feature cuda, aprender-compute feature cuda, aprender-core feature cuda, aprender-cuda-edge feature cuda, aprender-gpu feature cuda, aprender-profile feature cuda-tracing (dependency cudarc), aprender-serve feature cuda, aprender-train feature cuda, aprender-train-distill feature cuda, aprender-zram feature cuda, aprender-zram-core feature cuda (dependency cudarc); WebGPU: aprender feature wgpu, apr-cli feature wgpu, aprender-compute feature gpu (dependency wgpu), aprender-db feature gpu (dependency wgpu), aprender-distribute feature gpu (dependency wgpu), aprender-gpu feature wgpu (dependency wgpu), aprender-graph feature gpu (dependency wgpu), aprender-present-lib feature gpu (dependency wgpu), aprender-profile feature gpu-tracing (dependency wgpu) | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: libsqlite3-sys, zstd-sys, tree-sitter (feature full), alsa-sys (feature audio-alsa), nvml-wrapper-sys (feature nvml) and 1 more. Build uses a native toolchain: bindgen (feature bindgen) | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 31 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.