burn
Library Featured
Flexible and Comprehensive Deep Learning Framework in Rust
- Downloads
- 521,465
- Dependents
- 391
- Stars
- 16,257
- Forks
- 1,119
- Contributors
- 365
- Commits
- 3,769
- Latest release
- 0.22.1 ·
About
A tensor library and deep learning framework for numerical computing, training and inference.
Training and inference usually live in separate worlds. Models are typically trained in Python then exported to an open format like ONNX or optimized for production engines like vLLM, ONNX Runtime, or TensorRT. This export step is often brittle and lossy, ruling out complex architectures and advanced deployment use cases.
Burn unifies the two. By executing multi-platform tensor operations via a single, unified API, the exact code used for training is the exact code that runs in production. This makes workloads like on-device personalization and federated learning straightforward, while enabling teams to go from prototype to deployment in a single codebase.
Burn preserves the intuitive ergonomics of PyTorch, with dynamic shapes and graphs, but JIT-compiles streams of tensor operations, performing automatic kernel fusion. You get the flexibility of dynamic graphs without the performance drop.
Read the full README
Rust for Research?
Rust used to be a tough sell for research: long compilation times disrupted the fast edit-compile-run loop that draws researchers to Python. Burn changes this paradigm. Designed around incremental compilation, modifying model code recompiles in under 5 seconds, even in release mode. This delivers a Python-like feedback loop with the speed and safety of Rust.
Ecosystem
Burn is the core of a growing, fully open-source Rust AI ecosystem. You are not adopting a single library, you are joining a stack that spans GPU compute, model interop and domain toolkits, with plenty of room to help shape what comes next.
| Category | Project | Description |
|---|---|---|
| Compute | CubeCL | GPU compute language and compiler behind Burn's accelerated backends. Write kernels once in Rust, run on CUDA, ROCm, Metal, Vulkan and WebGPU. Usable standalone. |
| Model interop | burn-onnx | Import ONNX models into Burn as native Rust code |
burn-store | Save, load and import model weights, including PyTorch and Safetensors | |
| Domains | burn-vision | Computer vision operators and building blocks |
burn-rl | Reinforcement learning building blocks | |
burn-dataset | Dataset loading, transforms and ready-made sources | |
| Models | models | Curated pre-trained models and examples built with Burn |
| Tooling | burn-bench | Benchmark and compare backends, tracking performance over time |
Burn's CubeCL backends (CUDA, ROCm, Metal, Vulkan, WebGPU,
CPU) compose with autodiff, fusion and remote-execution decorators, while the pure-Rust Flex
CPU/no_std backend composes with autodiff only. See
Supported Backends below for the full matrix.
Every project here is open-source and actively developed. Want to help build the Rust AI ecosystem? The good first issues are a great place to start, and the Contributing guide will get you set up.
Community crates 🌱
These crates are not maintained by Tracel, but they are part of the same Rust AI story. Anything that helps you load data, build environments, or ship models belongs here. Built something that fits? Open a PR to add it!
| Category | Crate | Description |
|---|---|---|
| Data & loading | polars | Fast DataFrames for tabular data |
| arrow-rs | Apache Arrow columnar memory format | |
| image | Image decoding, encoding and processing | |
| hf-hub | Download models and datasets from the Hugging Face Hub | |
| Tokenization & NLP | tokenizers | Fast, production-ready tokenizers |
| rust-bert | Ready-to-use NLP pipelines and transformer models | |
| Numerical & linear algebra | ndarray | N-dimensional arrays |
| nalgebra | Linear algebra | |
| Classical ML | linfa | Classical ML toolkit, in the spirit of scikit-learn |
| smartcore | Classical ML algorithms, no BLAS/LAPACK required | |
| Inference & runtimes | candle | Minimalist ML framework with a focus on LLM inference |
| mistral.rs | Fast, multimodal LLM inference engine | |
| ort | ONNX Runtime bindings for hardware-accelerated inference | |
| tract | Pure-Rust inference for ONNX and NNEF models | |
| wonnx | 100% Rust, WebGPU-accelerated ONNX runtime for native and the web | |
| LLM apps & RAG | rig | Build modular LLM applications and agents |
| langchain-rust | LangChain-style chain orchestration | |
| Embeddings & vector search | fastembed | Generate text embeddings and rerank locally |
| qdrant | Vector search engine, written in Rust | |
| lancedb | Embedded, developer-friendly vector database | |
| Computer vision | kornia-rs | Low-level 3D computer vision library |
| Simulation & environments | rapier | Physics engine for robotics and RL environments |
| Visualization | rerun | Multimodal data and CV/robotics visualization |
| plotters | Plotting and charting |
Backend
Burn strives to be as fast as possible on as many hardwares as possible, with robust implementations. We believe this flexibility is crucial for modern needs where you may train your models in the cloud, then deploy on customer hardwares, which vary from user to user.
Supported Backends
Most backends support all operating systems, so we don't mention them in the tables below.
GPU Backends:
| CUDA | ROCm | Metal | Vulkan | WebGPU | |
|---|---|---|---|---|---|
| Nvidia | ☑️ | - | - | ☑️ | ☑️ |
| AMD | - | ☑️ | - | ☑️ | ☑️ |
| Apple | - | - | ☑️ | - | ☑️ |
| Intel | - | - | - | ☑️ | ☑️ |
| Qualcom | - | - | - | ☑️ | ☑️ |
| Wasm | - | - | - | - | ☑️ |
CPU Backends:
| Cpu (CubeCL) | Flex | |
|---|---|---|
| X86 | ☑️ | ☑️ |
| Arm | ☑️ | ☑️ |
| Wasm | - | ☑️ |
| no-std | - | ☑️ |
The two native CPU backends are independent. Cpu (cpu feature) is the CubeCL
runtime for the CPU: it JIT-compiles the same kernels as the GPU backends through LLVM and supports
fusion. Flex (flex feature) is a pure-Rust eager backend with no
native dependencies that also runs on Wasm and no_std.
Migration: LibTorch was deprecated in
0.22.0and has been removed frommain. For GPU acceleration, use a CubeCL backend (CUDA, ROCm, Metal, Vulkan, WebGPU). For CPU execution, use the CubeCL CPU backend orburn-flex.
Burn's backend architecture lets you swap backends while keeping the same model code. You can enable
multiple backends in the same application and choose the device for your tensors and modules at
runtime through Device. This gives you the freedom to use different backends side by side and
select the hardware best suited to each workload.
Autodifferentiation and automatic kernel fusion integrate with the same tensor and module APIs, so models benefit from these capabilities on supported backends without changing their implementation.
Autodiff: Bringing backpropagation to any backend 🔄
In application code, autodiff is runtime context carried by tensors. Devices provide the default context for newly created tensors, and each tensor can later enable or remove autodiff independently. Enabling autodiff permits graph recording; it does not by itself make a tensor retain gradients.
Internally, Burn implements this by decorating a concrete backend, so autodiff cannot execute by
itself. Enable it on a device before creating tensors or initializing a model. With the autodiff
and wgpu features enabled:
use burn::tensor::{Device, Distribution, Tensor};

fn main() {
    let device = Device::wgpu(Default::default()).autodiff();

    let x: Tensor<2> = Tensor::random([32, 32], Distribution::Default, &device);
    let y: Tensor<2> = Tensor::random([32, 32], Distribution::Default, &device).require_grad();

    let tmp = x.clone() + y.clone();
    let tmp = tmp.matmul(x);
    let tmp = tmp.exp();

    let grads = tmp.backward();
    let y_grad = y.grad(&grads).unwrap();
    println!("{y_grad}");
}
backward() checks graph participation at runtime. Enable autodiff before the forward pass and call
require_grad() on source leaves whose gradients you need. is_autodiff(), is_tracked(), and
is_require_grad() inspect autodiff association, graph participation, and gradient retention
respectively. See the autodiff guide.
See the Autodiff Backend README for more details.
Fusion: Backend decorator that brings kernel fusion to supported backends
This backend decorator enhances a backend with kernel fusion, provided that the inner backend
supports it. Note that you can compose this backend with other backend decorators such as Autodiff.
All first-party accelerated backends (like WGPU and CUDA) use Fusion by default (burn/fusion
feature flag), so you typically don't need to apply it manually.
#[cfg(not(feature = "fusion"))]
pub type Cube = burn_cubecl::CubeBackend;

#[cfg(feature = "fusion")]
pub type Cube = burn_fusion::Fusion<burn_cubecl::CubeBackend>;
Device::autodiff().gradient_checkpointing() enables the balanced gradient-checkpointing strategy,
which trades recomputation for reduced activation storage during training.
See the Fusion Backend README for more details.
Remote (Beta): Backend decorator for remote backend execution, useful for distributed computations
Remote execution has a client and a server. The server's devices select the compute backend;
clients use a remote Device with the same tensor API. Iroh, the default transport, reaches a
server across any network, authenticated and encrypted; see the server example
and the distributed computing guide. On a
trusted network, WebSocket is the simplest setup: enable remote-server, remote-websocket, and
cuda on the server, and remote-websocket plus autodiff on the client:
use burn::remote::RemoteHost;
use burn::server::{RemoteServer, ServeError, WebSocketTransport};
use burn::tensor::{Device, Distribution, Tensor};

fn main_server() -> Result<(), ServeError> {
    RemoteServer::new([Device::cuda(0)]).serve(WebSocketTransport::new(3000))
}

fn main_client() -> Result<(), burn::remote::ConnectError> {
    let host = RemoteHost::websocket("ws://localhost:3000");
    let device = Device::remote_options(&host).init()?.autodiff();
    let tensor_gpu = Tensor::<2>::random([3, 3], Distribution::Default, &device);
    Ok(())
}
Training & Inference
The whole deep learning workflow is made easy with Burn, as you can monitor your training progress with an ergonomic dashboard, and run inference everywhere from embedded devices to large GPU clusters.
Burn was built from the ground up with training and inference in mind. It's also worth noting how Burn, in comparison to frameworks like PyTorch, simplifies the transition from training to deployment, eliminating the need for code changes.
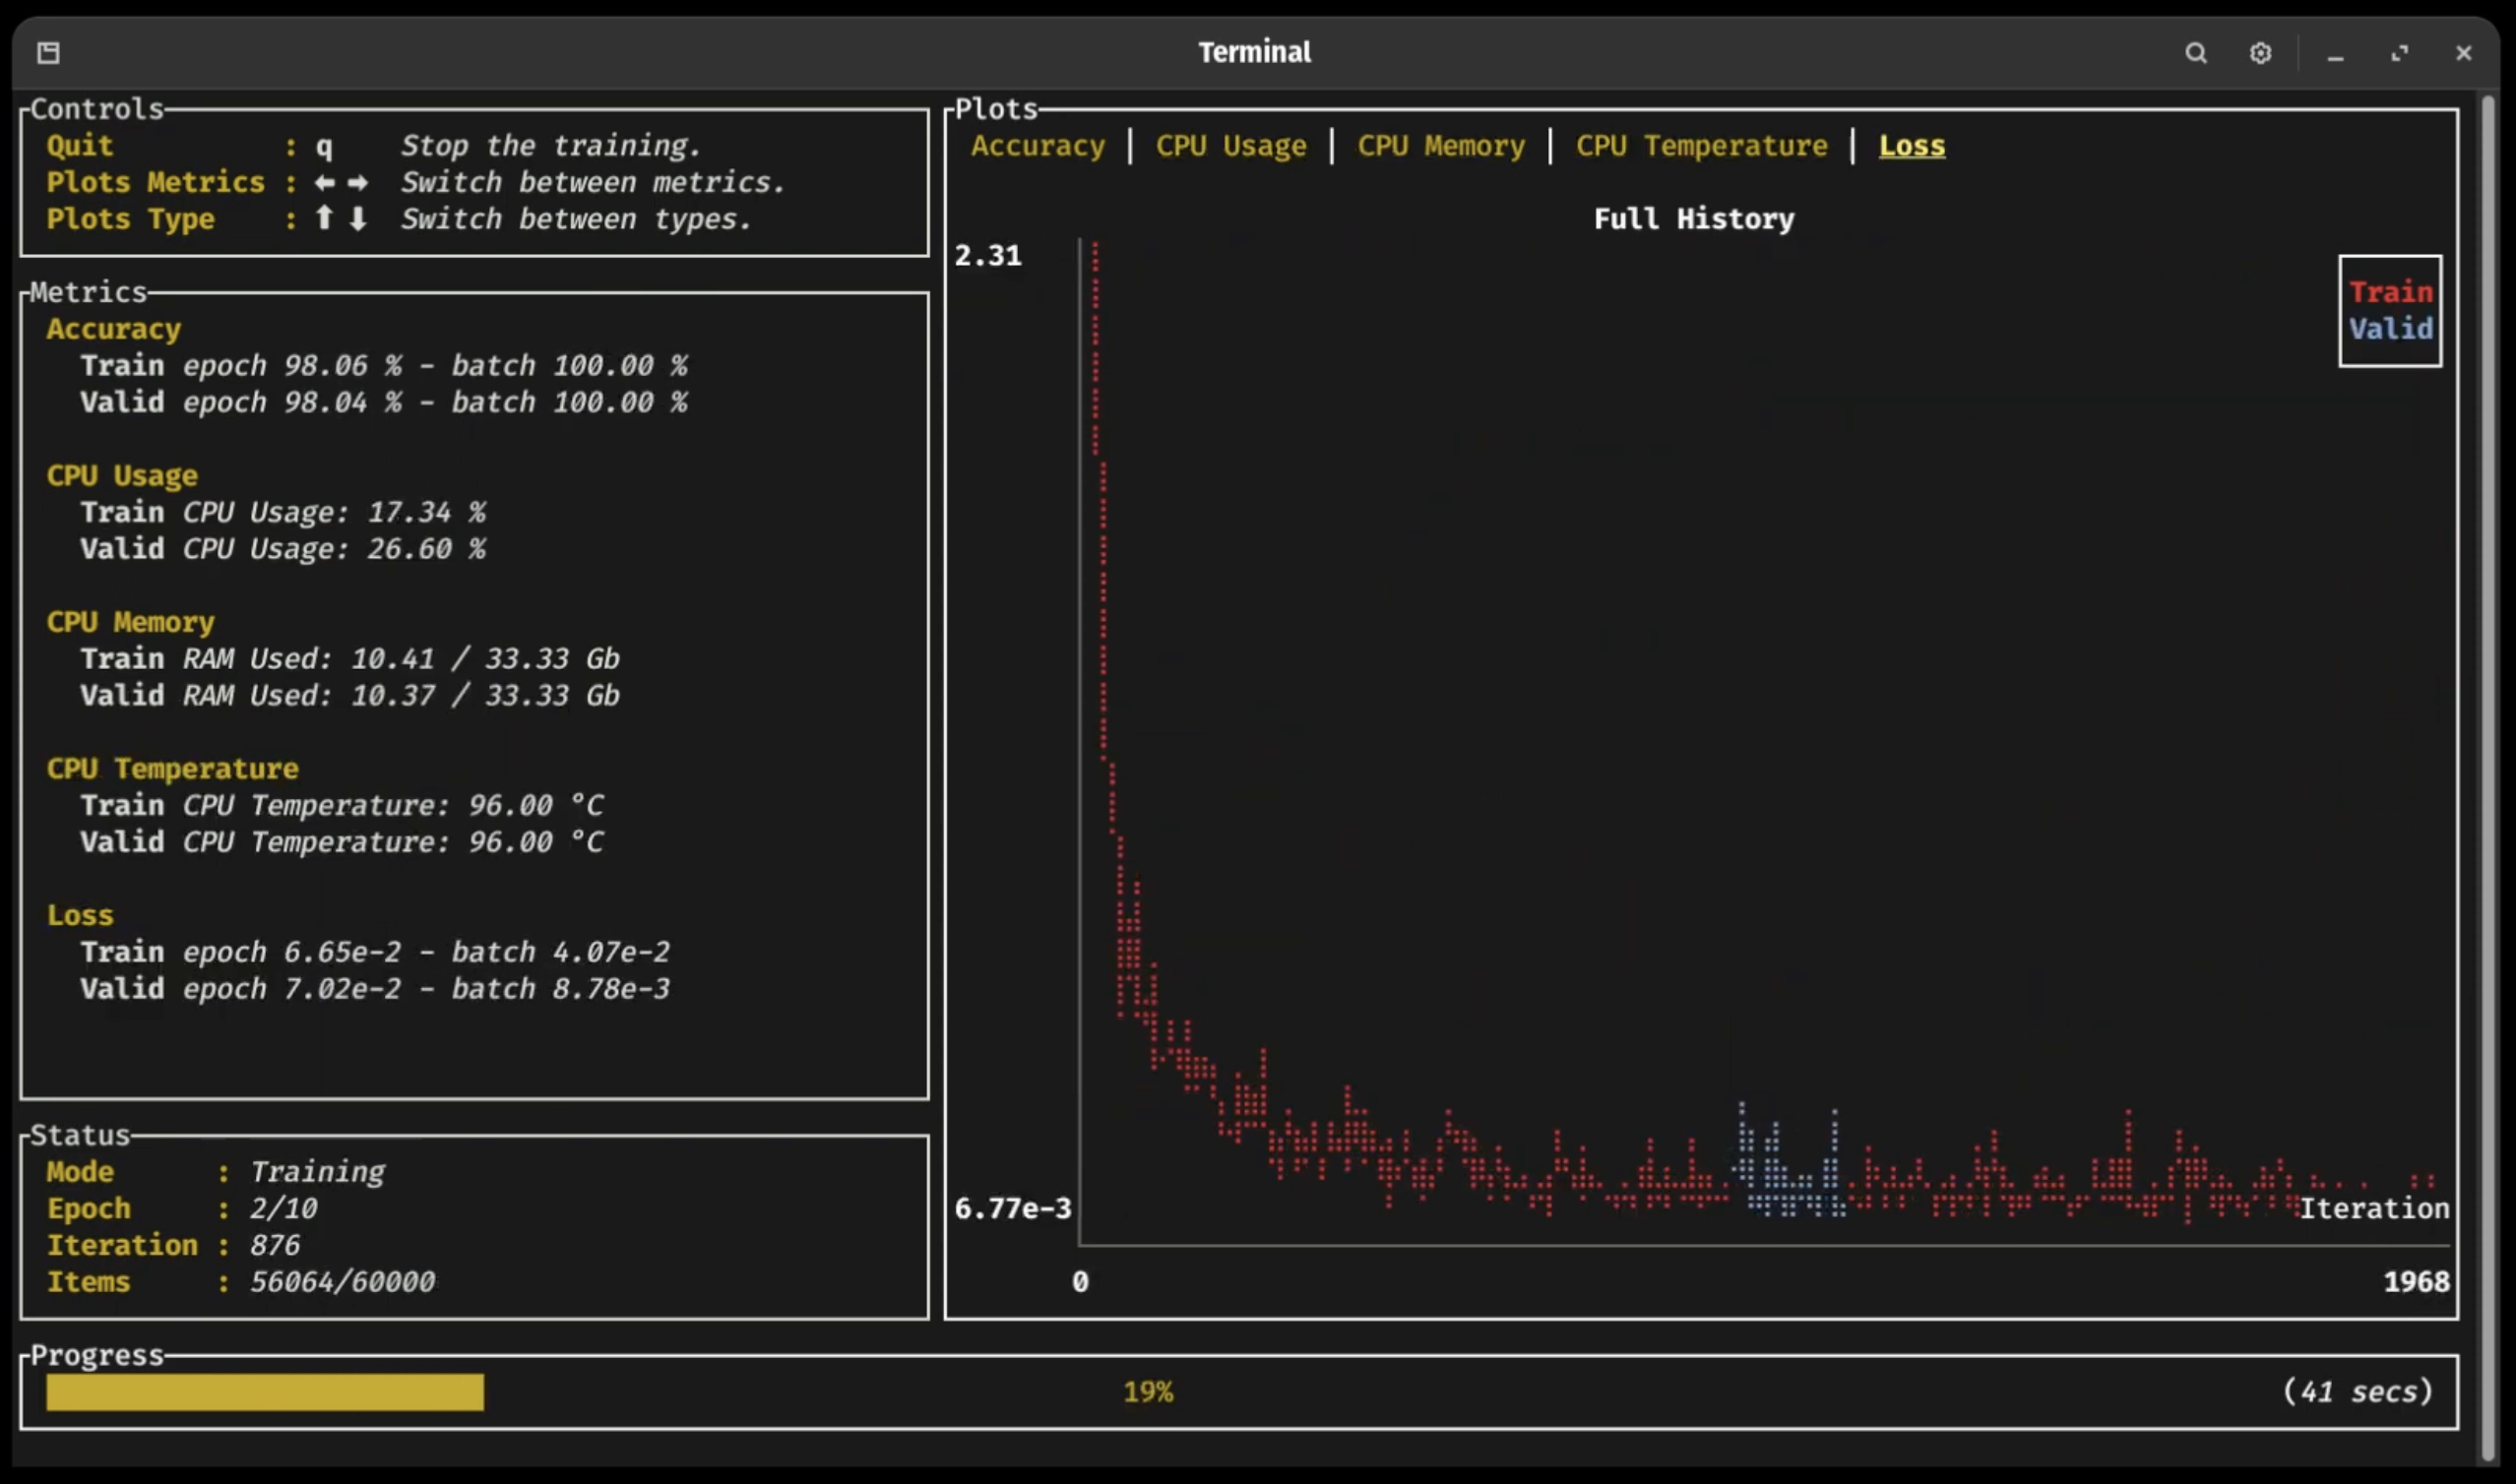
Click on the following sections to expand 👇
Training Dashboard 📈
As you can see in the previous video (click on the picture!), a new terminal UI dashboard based on the Ratatui crate allows users to follow their training with ease without having to connect to any external application.
You can visualize your training and validation metrics updating in real-time and analyze the lifelong progression or recent history of any registered metrics using only the arrow keys. Break from the training loop without crashing, allowing potential checkpoints to be fully written or important pieces of code to complete without interruption 🛡
ONNX Support 🐫
Burn supports importing ONNX (Open Neural Network Exchange) models through the burn-onnx crate, allowing you to easily port models from TensorFlow or PyTorch to Burn. The ONNX model is converted into Rust code that uses Burn's native APIs, enabling the imported model to run on any Burn backend (CPU, GPU, WebAssembly) and benefit from all of Burn's optimizations like automatic kernel fusion.
Our ONNX support is further described in this section of the Burn Book 🔥.
Note: This crate is in active development and currently supports a limited set of ONNX operators.
Importing PyTorch or Safetensors Models 🚚
You can load weights from PyTorch or Safetensors formats directly into your Burn-defined models. This makes it easy to reuse existing models while benefiting from Burn's performance and deployment features.
Learn more in the Saving & Loading Models section of the Burn Book.
Inference in the Browser 🌐
Several of our backends can run in WebAssembly environments: Flex for CPU execution, and WGPU for GPU acceleration via WebGPU. This means that you can run inference directly within a browser. We provide several examples of this:
- MNIST where you can draw digits and a small convnet tries to find which one it is! 2️⃣ 7️⃣ 😰
- Image Classification where you can upload images and classify them! 🌄
Embedded: no_std support ⚙️
Burn's core components support no_std. This means it can run in bare metal environment such as embedded devices without an operating system.
As of now, only the Flex backend can be used in a no_std environment.
Benchmarks
To evaluate performance across different backends and track improvements over time, we provide a dedicated benchmarking suite.
Run and compare benchmarks using burn-bench.
Getting Started
Just heard of Burn? You are at the right place! Just continue reading this section and we hope you can get on board really quickly.
The Burn Book 🔥
To begin working effectively with Burn, it is crucial to understand its key components and philosophy. This is why we highly recommend new users to read the first sections of The Burn Book 🔥. It provides detailed examples and explanations covering every facet of the framework, including building blocks like tensors, modules, and optimizers, all the way to advanced usage, like coding your own GPU kernels.
The project is constantly evolving, and we try as much as possible to keep the book up to date with new additions. However, we might miss some details sometimes, so if you see something weird, let us know! We also gladly accept Pull Requests 😄
Examples 🙏
Let's start with a code snippet that shows how intuitive the framework is to use! In the following, we declare a neural network module with some parameters along with its forward pass.
use burn::nn;
use burn::module::Module;
use burn::tensor::Tensor;

#[derive(Module, Debug)]
pub struct PositionWiseFeedForward {
    linear_inner: nn::Linear,
    linear_outer: nn::Linear,
    dropout: nn::Dropout,
    gelu: nn::Gelu,
}

impl PositionWiseFeedForward {
    pub fn forward<const D: usize>(&self, input: Tensor<D>) -> Tensor<D> {
        let x = self.linear_inner.forward(input);
        let x = self.gelu.forward(x);
        let x = self.dropout.forward(x);

        self.linear_outer.forward(x)
    }
}
We have a somewhat large amount of examples in the repository that shows how to use the framework in different scenarios.
Following the book:
- Basic Workflow : Creates a custom CNN
Moduleto train on the MNIST dataset and use for inference. - Custom Training Loop : Implements a basic training loop instead
of using the
Learner. - Custom WGPU Kernel : Learn how to create your own custom operation with the WGPU backend.
Additional examples:
- Custom CSV Dataset : Implements a dataset to parse CSV data for a regression task.
- Regression : Trains a simple MLP on the California Housing dataset to predict the median house value for a district.
- Custom Image Dataset : Trains a simple CNN on custom image dataset following a simple folder structure.
- Custom Renderer : Implements a custom renderer to display the
Learnerprogress. - Image Classification Web : Image classification web browser demo using Burn, WGPU and WebAssembly.
- MNIST Inference on Web : An interactive MNIST inference demo in the browser.
- MNIST Training : Demonstrates how to train a custom
Module(MLP) with theLearnerconfigured to log metrics and keep training checkpoints. - PyTorch Import Inference : Imports a PyTorch model pre-trained on MNIST to perform inference on a sample image with Burn.
- Text Classification : Trains a text classification transformer model on the AG News or DbPedia dataset. The trained model can then be used to classify a text sample.
- Text Generation : Trains a text generation transformer model on the DbPedia dataset.
- Wasserstein GAN MNIST : Trains a WGAN model to generate new handwritten digits based on MNIST.
For more practical insights, you can clone the repository and run any of them directly on your computer!
Pre-trained Models 🤖
We keep an updated and curated list of models and examples built with Burn, see the tracel-ai/models repository for more details.
Don't see the model you want? Don't hesitate to open an issue, and we may prioritize it. Built a model using Burn and want to share it? You can also open a Pull Request and add your model under the community section!
Why use Rust for AI? 🦀
Deep Learning is a special form of software where you need very high level abstractions as well as extremely fast execution time. Rust is the perfect candidate for that use case since it provides zero-cost abstractions to easily create neural network modules, and fine-grained control over memory to optimize every detail. To this day, the mainstream solution has been to offer APIs in Python but rely on bindings to low-level languages such as C/C++. This reduces portability, increases complexity and creates friction between researchers and engineers. Rust's approach to abstractions is versatile enough to tackle this two-language dichotomy, and Cargo makes it easy to build, test and deploy from any environment, which is usually a pain in Python.
Rust's AI ecosystem is young, but it is real and growing quickly. Foundational pieces are already
here: Burn and CubeCL for training and compute,
candle for inference, Hugging Face's tokenizers and
safetensors, and polars and ndarray for data. Betting on Rust today means betting on a stack
that is growing, and one where contributors still shape the direction. The pieces that don't exist
yet are opportunities rather than dead-ends (see Contributing).
Rust is also what makes one-stack-everywhere possible: a single self-contained binary with no Python
runtime to ship, running from servers down to no_std embedded targets.
Deprecation Note
Since0.14.0, the internal structure for tensor data has changed. The previousDatastruct was deprecated and officially removed since0.17.0in favor of the newTensorDatastruct, which allows for more flexibility by storing the underlying data as bytes and keeping the data type as a field. If you are usingDatain your code, make sure to switch toTensorData.
Loading Model Records From Previous Versions ⚠️
Burn 0.22 uses burnpack for native records and cannot directly read legacy Recorder formats such
as .mpk, .bin, or JSON. Load the checkpoint in a compatible older Burn project, export the model
weights through burn-store, and import them into your 0.22 model. See
Migrating checkpoints for an example and
the distinction between transferring weights and resuming training state.
For records saved before 0.14.0, an earlier migration step may also be needed: use Burn 0.14,
0.15, or 0.16 with the record-backward-compat feature to load and re-save the record with the
newer tensor-data representation. For legacy binary records, first use the version that wrote them
to export a self-describing format such as NamedMpkFileRecorder. This historical migration does
not convert records to the format required by 0.22; follow the checkpoint migration guide afterward.
Community
If you are excited about the project, don't hesitate to join our Discord! We try to be as welcoming as possible to everybody from any background. You can ask your questions and share what you built with the community!
Contributing
Before contributing, please read the Contributing Guidelines and our Code of Conduct. The Contributor Book covers architecture, environment setup, and guides for common tasks.
Status
Burn is currently in active development, and there will be breaking changes. While any resulting issues are likely to be easy to fix, there are no guarantees at this stage.
License
Burn is distributed under the terms of either the MIT License or the Apache License, Version 2.0. Unless otherwise noted, this applies to all contents of this repository, including source code, examples, documentation, and code snippets in the Burn Book and Contributor Book. See the licenses for details.
Third-party materials and externally downloaded datasets or models remain subject to their respective licenses.
Opening a pull request is assumed to signal agreement with these licensing terms.
Compatibility
- Runs on
- CUDA, WebGPU, Metal, ROCm, Vulkan
What shows it
- CUDA: burn feature cuda, burn-core feature cuda, burn-cubecl feature cuda, burn-dispatch feature cuda, burn-linalg feature cuda, burn-signal feature tch (dependency tch), burn-store feature cuda, burn-tensor feature cuda, burn-vision feature cuda
- WebGPU: burn feature webgpu, burn-core feature webgpu, burn-cubecl feature webgpu, burn-dispatch feature webgpu, burn-linalg feature webgpu, burn-signal feature webgpu, burn-store feature wgpu, burn-tensor feature webgpu, burn-vision feature webgpu, burn-wgpu feature webgpu
- Metal: burn feature metal, burn-core feature metal, burn-cubecl feature metal, burn-dispatch feature metal, burn-linalg feature metal, burn-signal feature metal, burn-store feature metal, burn-tensor feature metal, burn-vision feature metal, burn-wgpu feature metal
- ROCm: burn feature rocm, burn-core feature rocm, burn-dispatch feature rocm, burn-linalg feature rocm, burn-signal feature rocm, burn-tensor feature rocm, burn-vision feature rocm
- Vulkan: burn feature vulkan, burn-core feature vulkan, burn-cubecl feature vulkan, burn-dispatch feature vulkan, burn-linalg feature vulkan, burn-signal feature vulkan, burn-tensor feature vulkan, burn-vision feature vulkan, burn-wgpu feature vulkan
- Native code
- Optional
- Binds native code: netlink-sys (feature iroh), nvml-wrapper-sys (feature sys-metrics), torch-sys (feature tch)
- Python bindings
- No Python binding crate found
- License
- Apache-2.0 OR MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Flexible and Comprehensive Deep Learning Framework in Rust |
521,465 downloads over 30 days | 391 | 16,257 | 0.22.1 | CUDA, WebGPU, Metal, ROCm, Vulkan | Binds native code: netlink-sys (feature iroh), nvml-wrapper-sys (feature sys-metrics), torch-sys (feature tch) | Apache-2.0 OR MIT |
|
candle Featured
Minimalist ML framework. Python bindings Also in Tensors and GPU compute. |
1,766,495 downloads over 30 days | 692 | 21,287 | 0.11.1 | CUDA, Metal | Binds native code: accelerate-src (feature accelerate), intel-mkl-src (feature mkl), alsa-sys (feature encodec) | Apache-2.0 OR MIT |
|
tch-rs Featured
Rust wrappers for the PyTorch C++ api (libtorch). Python bindings Also in Run and serve models. |
1,190,464 downloads over 30 days | 124 | 5,518 | 0.26.0 | CUDA | Binds native code: tch, torch-sys. Build uses a native toolchain: cc | Apache-2.0 OR MIT |
|
mlx-rs Featured
Unofficial rust wrapper for Apple's mlx machine learning library. Also in Run and serve models. |
33,398 downloads over 30 days | 36 | 389 | 0.34.0 | Metal | Binds native code: mach-sys, mlx, mlx-sys. Build uses a native toolchain: bindgen, cc, cmake | Apache-2.0 OR MIT |
|
boostr Listed
ML framework on numr for training and inference on CPU, CUDA and WebGPU: attention, quantization, inference scheduling and distributed execution. Models include LLaMA, Mamba2, Qwen3.5, Whisper, Kokoro, VITS, VoxCPM2, Silero VAD, CLAP and super-resolution. Loads SafeTensors and GGUF. Also in Tensors and GPU compute. |
1,265 downloads over 30 days | 7 | 20 | 0.11.2 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
rumus Listed
A native-Rust deep learning framework with explicit memory safety and hardware acceleration Also in Train models. |
52 downloads over 30 days | 0 | 202 | 0.4.0 | WebGPU | No native code found | Apache-2.0 OR MIT |
All projects in Tensors and GPU computeAll projects in Run and serve modelsAll projects in Train models
Why FeaturedIt passes every Featured gate.
What it meets
- It has 94 active dependents and 83 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days.
- Active dependents are at 100% of their peak. Featured needs at least 50%.
- Docs are present. The release commit or a manifest ties the crate to the repository.
- No vulnerability advisory stays unpatched past the grace window. At least one version is neither a prerelease nor 0.0.x.
- The last activity is on 8 Nov 2026, 1 day ago. The rules expect an update within 1200 days. Dormancy rule
Exact rules: Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 0.22.1 base 300, doubled for 521465 downloads per month, doubled for 94 active users: E = 1200 daysdormancy: last activity 2026-11-08, 1 days ago, E = 1200: activefeatured: featured: active_users 94, new_adopters 83, former_glory 1
Crates36 crates
- burn Primary
- burn-autodiff
- burn-backend
- burn-collective
- burn-compute
- burn-core
- burn-cpu
- burn-cubecl
- burn-cubecl-fusion
- burn-cuda
- burn-dataset
- burn-dispatch
- burn-flex
- burn-fusion
- burn-group
- burn-hip
- burn-instrument
- burn-instrument-report
- burn-ir
- burn-jit
- burn-linalg
- burn-nn
- burn-optim
- burn-pack
- burn-remote
- burn-rl
- burn-rocm
- burn-router
- burn-signal
- burn-store
- burn-tensor
- burn-tensor-testgen
- burn-train
- burn-vision
- burn-wgpu
- pytorch-reader
Related projects
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption94 active dependents, 83 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 94 | crates.io database dump | Yes | |
| New dependents (365 days) | 83 | crates.io database dump | Yes | |
| Peak active dependents | 93.5 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: 1 day ago3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-08 | GitHub repository | Yes | |
| Latest release | 2026-10-29 | crates.io database dump | Yes | |
| First release | 2022-07-27 | crates.io database dump | Yes | |
| Latest version | 0.22.1 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 16 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 35 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | none | crates.io database dump | Yes |
Distribution50 releases, 521,465 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 50 | crates.io database dump | Yes | |
| Downloads over 30 days | 521465 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository16,257 stars, 1,119 forks, 365 contributors, 3,769 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 16257 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 1119 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 365 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 3769 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | Apache-2.0 OR MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | CUDA, WebGPU, Metal, ROCm, Vulkan | crates.io database dump | No | |
| What shows each backend | CUDA: burn feature cuda, burn-core feature cuda, burn-cubecl feature cuda, burn-dispatch feature cuda, burn-linalg feature cuda, burn-signal feature tch (dependency tch), burn-store feature cuda, burn-tensor feature cuda, burn-vision feature cuda; WebGPU: burn feature webgpu, burn-core feature webgpu, burn-cubecl feature webgpu, burn-dispatch feature webgpu, burn-linalg feature webgpu, burn-signal feature webgpu, burn-store feature wgpu, burn-tensor feature webgpu, burn-vision feature webgpu, burn-wgpu feature webgpu; Metal: burn feature metal, burn-core feature metal, burn-cubecl feature metal, burn-dispatch feature metal, burn-linalg feature metal, burn-signal feature metal, burn-store feature metal, burn-tensor feature metal, burn-vision feature metal, burn-wgpu feature metal; ROCm: burn feature rocm, burn-core feature rocm, burn-dispatch feature rocm, burn-linalg feature rocm, burn-signal feature rocm, burn-tensor feature rocm, burn-vision feature rocm; Vulkan: burn feature vulkan, burn-core feature vulkan, burn-cubecl feature vulkan, burn-dispatch feature vulkan, burn-linalg feature vulkan, burn-signal feature vulkan, burn-tensor feature vulkan, burn-vision feature vulkan, burn-wgpu feature vulkan | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: netlink-sys (feature iroh), nvml-wrapper-sys (feature sys-metrics), torch-sys (feature tch) | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 391 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.