sherpa-onnx
Library Featured
Safe Rust wrapper for sherpa-onnx speech recognition toolkit
- Downloads
- 259,599
- Dependents
- 28
- Stars
- 15,834
- Forks
- 1,858
- Contributors
- 273
- Commits
- 2,187
- Latest release
- 2.0.1 ·
About
Supported functions
| Speech recognition | Speech synthesis | Source separation |
|---|---|---|
| ✔️ | ✔️ | ✔️ |
| Speaker identification | Speaker diarization | Speaker verification |
|---|---|---|
| ✔️ | ✔️ | ✔️ |
Supported platforms
| Architecture | Android | iOS | Windows | macOS | linux | HarmonyOS |
|---|---|---|---|---|---|---|
| x64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ | |
| x86 | ✔️ | ✔️ | ||||
| arm64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ |
| arm32 | ✔️ | ✔️ | ✔️ | |||
| riscv64 | ✔️ |
Supported programming languages
| 1. C++ | 2. C | 3. Python | 4. JavaScript |
|---|---|---|---|
| ✔️ | ✔️ | ✔️ | ✔️ |
| 5. Java | 6. C# | 7. Kotlin | 8. Swift |
|---|---|---|---|
| ✔️ | ✔️ | ✔️ | ✔️ |
| 9. Go | 10. Dart | 11. Rust | 12. Pascal |
|---|---|---|---|
| ✔️ | ✔️ | ✔️ | ✔️ |
It also supports WebAssembly.
Supported frameworks
Flutter
| Architecture | Android | iOS | Windows | macOS | Linux | Web |
|---|---|---|---|---|---|---|
| x64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ | |
| x86 | ✔️ | ✔️ | ||||
| arm64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ |
| arm32 | ✔️ | ✔️ |
- Pre-built Flutter demo apps: flutter releases
Tauri
| Architecture | Android | iOS | Windows | macOS | Linux |
|---|---|---|---|---|---|
| x64 | ✔️ | ✔️ | ✔️ | ✔️ | |
| x86 | ✔️ | ||||
| arm64 | ✔️ | ✔️ | ✔️ | ✔️ | ✔️ |
| arm32 | ✔️ |
- Pre-built Tauri demo apps: tauri releases
Supported NPUs
Introduction
This repository supports running the following functions locally
Read the full README
- Speech-to-text (i.e., ASR); both streaming and non-streaming are supported
- Text-to-speech (i.e., TTS)
- Speaker diarization
- Speaker identification
- Speaker verification
- Spoken language identification
- Audio tagging
- VAD (e.g., silero-vad)
- Speech enhancement (e.g., gtcrn, DPDFNet, VoxLock)
- Keyword spotting
- Source separation (e.g., spleeter, UVR)
on the following platforms and operating systems:
- x86,
x86_64, 32-bit ARM, 64-bit ARM (arm64, aarch64), RISC-V (riscv64), RK NPU, Ascend NPU - Linux, macOS, Windows, openKylin
- Android, WearOS
- iOS
- HarmonyOS
- NodeJS
- WebAssembly
- NVIDIA Jetson Orin NX (Support running on both CPU and GPU)
- NVIDIA Jetson Nano B01 (Support running on both CPU and GPU)
- Raspberry Pi
- RV1126
- LicheePi4A
- VisionFive 2
- 旭日X3派
- 爱芯派
- RK3588
- SpacemiT-K1
- SpacemiT-K3
- etc
with the following APIs
- C++, C, Python, Go,
C# - Java, Kotlin, JavaScript
- Swift, Rust
- Dart, Object Pascal
Links for Huggingface Spaces
You can visit the following Huggingface spaces to try sherpa-onnx without installing anything. All you need is a browser.
| Description | URL | 中国镜像 |
|---|---|---|
| Speaker diarization | Click me | 镜像 |
| Speech recognition | Click me | 镜像 |
| Speech recognition with Whisper | Click me | 镜像 |
| Speech synthesis | Click me | 镜像 |
| Generate subtitles | Click me | 镜像 |
| Audio tagging | Click me | 镜像 |
| Source separation | Click me | 镜像 |
| Spoken language identification with Whisper | Click me | 镜像 |
We also have spaces built using WebAssembly. They are listed below:
| Description | Huggingface space | ModelScope space |
|---|---|---|
| Voice activity detection with silero-vad | Click me | 地址 |
| Real-time speech recognition (Chinese + English) with Zipformer | Click me | 地址 |
| Real-time speech recognition (Chinese + English) with Paraformer | Click me | 地址 |
| Real-time speech recognition (Chinese + English + Cantonese) with Paraformer-large | Click me | 地址 |
| Real-time speech recognition (English) | Click me | 地址 |
| VAD + speech recognition (Chinese) with Zipformer CTC | Click me | 地址 |
| VAD + speech recognition (Chinese + English + Korean + Japanese + Cantonese) with SenseVoice | Click me | 地址 |
| VAD + speech recognition (English) with Whisper tiny.en | Click me | 地址 |
| VAD + speech recognition (English) with Moonshine tiny | Click me | 地址 |
| VAD + speech recognition (English) with Zipformer trained with GigaSpeech | Click me | 地址 |
| VAD + speech recognition (Chinese) with Zipformer trained with WenetSpeech | Click me | 地址 |
| VAD + speech recognition (Japanese) with Zipformer trained with ReazonSpeech | Click me | 地址 |
| VAD + speech recognition (Thai) with Zipformer trained with GigaSpeech2 | Click me | 地址 |
| VAD + speech recognition (Chinese 多种方言) with a TeleSpeech-ASR CTC model | Click me | 地址 |
| VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-large | Click me | 地址 |
| VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-small | Click me | 地址 |
| VAD + speech recognition (多语种及多种中文方言) with Dolphin-base | Click me | 地址 |
| Speech synthesis (Piper, English) | Click me | 地址 |
| Speech synthesis (Piper, German) | Click me | 地址 |
| Speech synthesis (Matcha, Chinese) | Click me | 地址 |
| Speech synthesis (Matcha, English) | Click me | 地址 |
| Speech synthesis (Matcha, Chinese+English) | Click me | 地址 |
| Speaker diarization | Click me | 地址 |
| Voice cloning with ZipVoice (Chinese+English) | Click me | 地址 |
| Voice cloning with Pocket TTS (English) | Click me | 地址 |
Links for pre-built Android APKs
You can find pre-built Android APKs for this repository in the following table
| Description | URL | 中国用户 |
|---|---|---|
| Speaker diarization | Address | 点此 |
| Streaming speech recognition | Address | 点此 |
| Simulated-streaming speech recognition | Address | 点此 |
| Text-to-speech | Address | 点此 |
| Voice activity detection (VAD) | Address | 点此 |
| VAD + non-streaming speech recognition | Address | 点此 |
| Two-pass speech recognition | Address | 点此 |
| Audio tagging | Address | 点此 |
| Audio tagging (WearOS) | Address | 点此 |
| Speaker identification | Address | 点此 |
| Spoken language identification | Address | 点此 |
| Keyword spotting | Address | 点此 |
Links for pre-built Flutter APPs
Real-time speech recognition
Text-to-speech
| Description | URL | 中国用户 |
|---|---|---|
| Android (arm64-v8a, armeabi-v7a, x86_64) | Address | 点此 |
| Linux (x64) | Address | 点此 |
| macOS (x64) | Address | 点此 |
| macOS (arm64) | Address | 点此 |
| Windows (x64) | Address | 点此 |
Note: You need to build from source for iOS.
Links for pre-built Lazarus APPs
Generating subtitles
Links for pre-trained models
| Description | URL |
|---|---|
| Speech recognition (speech to text, ASR) | Address |
| Text-to-speech (TTS) | Address |
| VAD | Address |
| Keyword spotting | Address |
| Audio tagging | Address |
| Speaker identification (Speaker ID) | Address |
| Spoken language identification (Language ID) | See multi-lingual Whisper ASR models from Speech recognition |
| Punctuation | Address |
| Speaker segmentation | Address |
| Speech enhancement | Address |
| Source separation | Address |
Some pre-trained ASR models (Streaming)
Please see
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-transducer/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-paraformer/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/online-ctc/index.html
for more models. The following table lists only SOME of them.
| Name | Supported Languages | Description |
|---|---|---|
| sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20 | Chinese, English | See also |
| sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16 | Chinese, English | See also |
| sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23 | Chinese | Suitable for Cortex A7 CPU. See also |
| sherpa-onnx-streaming-zipformer-en-20M-2023-02-17 | English | Suitable for Cortex A7 CPU. See also |
| sherpa-onnx-streaming-zipformer-korean-2024-06-16 | Korean | See also |
| sherpa-onnx-streaming-zipformer-fr-2023-04-14 | French | See also |
Some pre-trained ASR models (Non-Streaming)
Please see
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-transducer/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-paraformer/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/offline-ctc/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/telespeech/index.html
- https://k2-fsa.github.io/sherpa/onnx/pretrained_models/whisper/index.html
for more models. The following table lists only SOME of them.
| Name | Supported Languages | Description |
|---|---|---|
| sherpa-onnx-nemo-parakeet-tdt-0.6b-v2-int8 | English | It is converted from https://huggingface.co/nvidia/parakeet-tdt-0.6b-v2 |
| Whisper tiny.en | English | See also |
| Moonshine tiny | English | See also |
| sherpa-onnx-zipformer-ctc-zh-int8-2025-07-03 | Chinese | A Zipformer CTC model |
| sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17 | Chinese, Cantonese, English, Korean, Japanese | 支持多种中文方言. See also |
| sherpa-onnx-paraformer-zh-2024-03-09 | Chinese, English | 也支持多种中文方言. See also |
| sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01 | Japanese | See also |
| sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24 | Russian | See also |
| sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24 | Russian | See also |
| sherpa-onnx-zipformer-ru-2024-09-18 | Russian | See also |
| sherpa-onnx-zipformer-korean-2024-06-24 | Korean | See also |
| sherpa-onnx-zipformer-thai-2024-06-20 | Thai | See also |
| sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04 | Chinese | 支持多种方言. See also |
Useful links
- Documentation: https://k2-fsa.github.io/sherpa/onnx/
- Bilibili 演示视频: https://search.bilibili.com/all?keyword=%E6%96%B0%E4%B8%80%E4%BB%A3Kaldi
How to reach us
Please see https://k2-fsa.github.io/sherpa/social-groups.html for 新一代 Kaldi 微信交流群 and QQ 交流群.
Projects using sherpa-onnx
VocaRead
iOS app for reading EPUBs, PDFs, and documents aloud. It uses sherpa-onnx to synthesize speech locally with Piper voices and can import books from OPDS catalogs.
Sherpa Voice / @siteed/sherpa-onnx.rn
React Native wrapper and demo app for validating sherpa-onnx on iOS, Android, and Web, including ASR, TTS, VAD, KWS, speaker ID, diarization, language ID, punctuation, audio tagging, and speech enhancement.
SmartVoice
SmartVoice is a local speech application for speech recognition and text-to-speech. Its
smartvoice-autovirtual model matches each request's task and language against an editable routing table, then dynamically routes it to the most suitable installed model. sherpa-onnx powers CPU inference; a web interface and HTTP API are included.
Speed of Sound
A voice-typing application for the Linux desktop (GTK4/Adwaita). It captures microphone audio, transcribes it offline using Sherpa ONNX ASR models, optionally polishes the text with an LLM, and types the result into the active window via XDG Remote Desktop Portal keyboard simulation.
VoxSherpa TTS
VoxSherpa TTS is a 100% offline Android Text-to-Speech app powered by Sherpa-ONNX. It supports Kokoro-82M, Piper, and VITS engines with multilingual support including Hindi, English, British English, Japanese, Chinese and 50+ more languages.
- Download APK (All Versions)
- Android 11+ · 100% offline · No telemetry
| Generate | Models | Library | Settings |
|---|---|---|---|
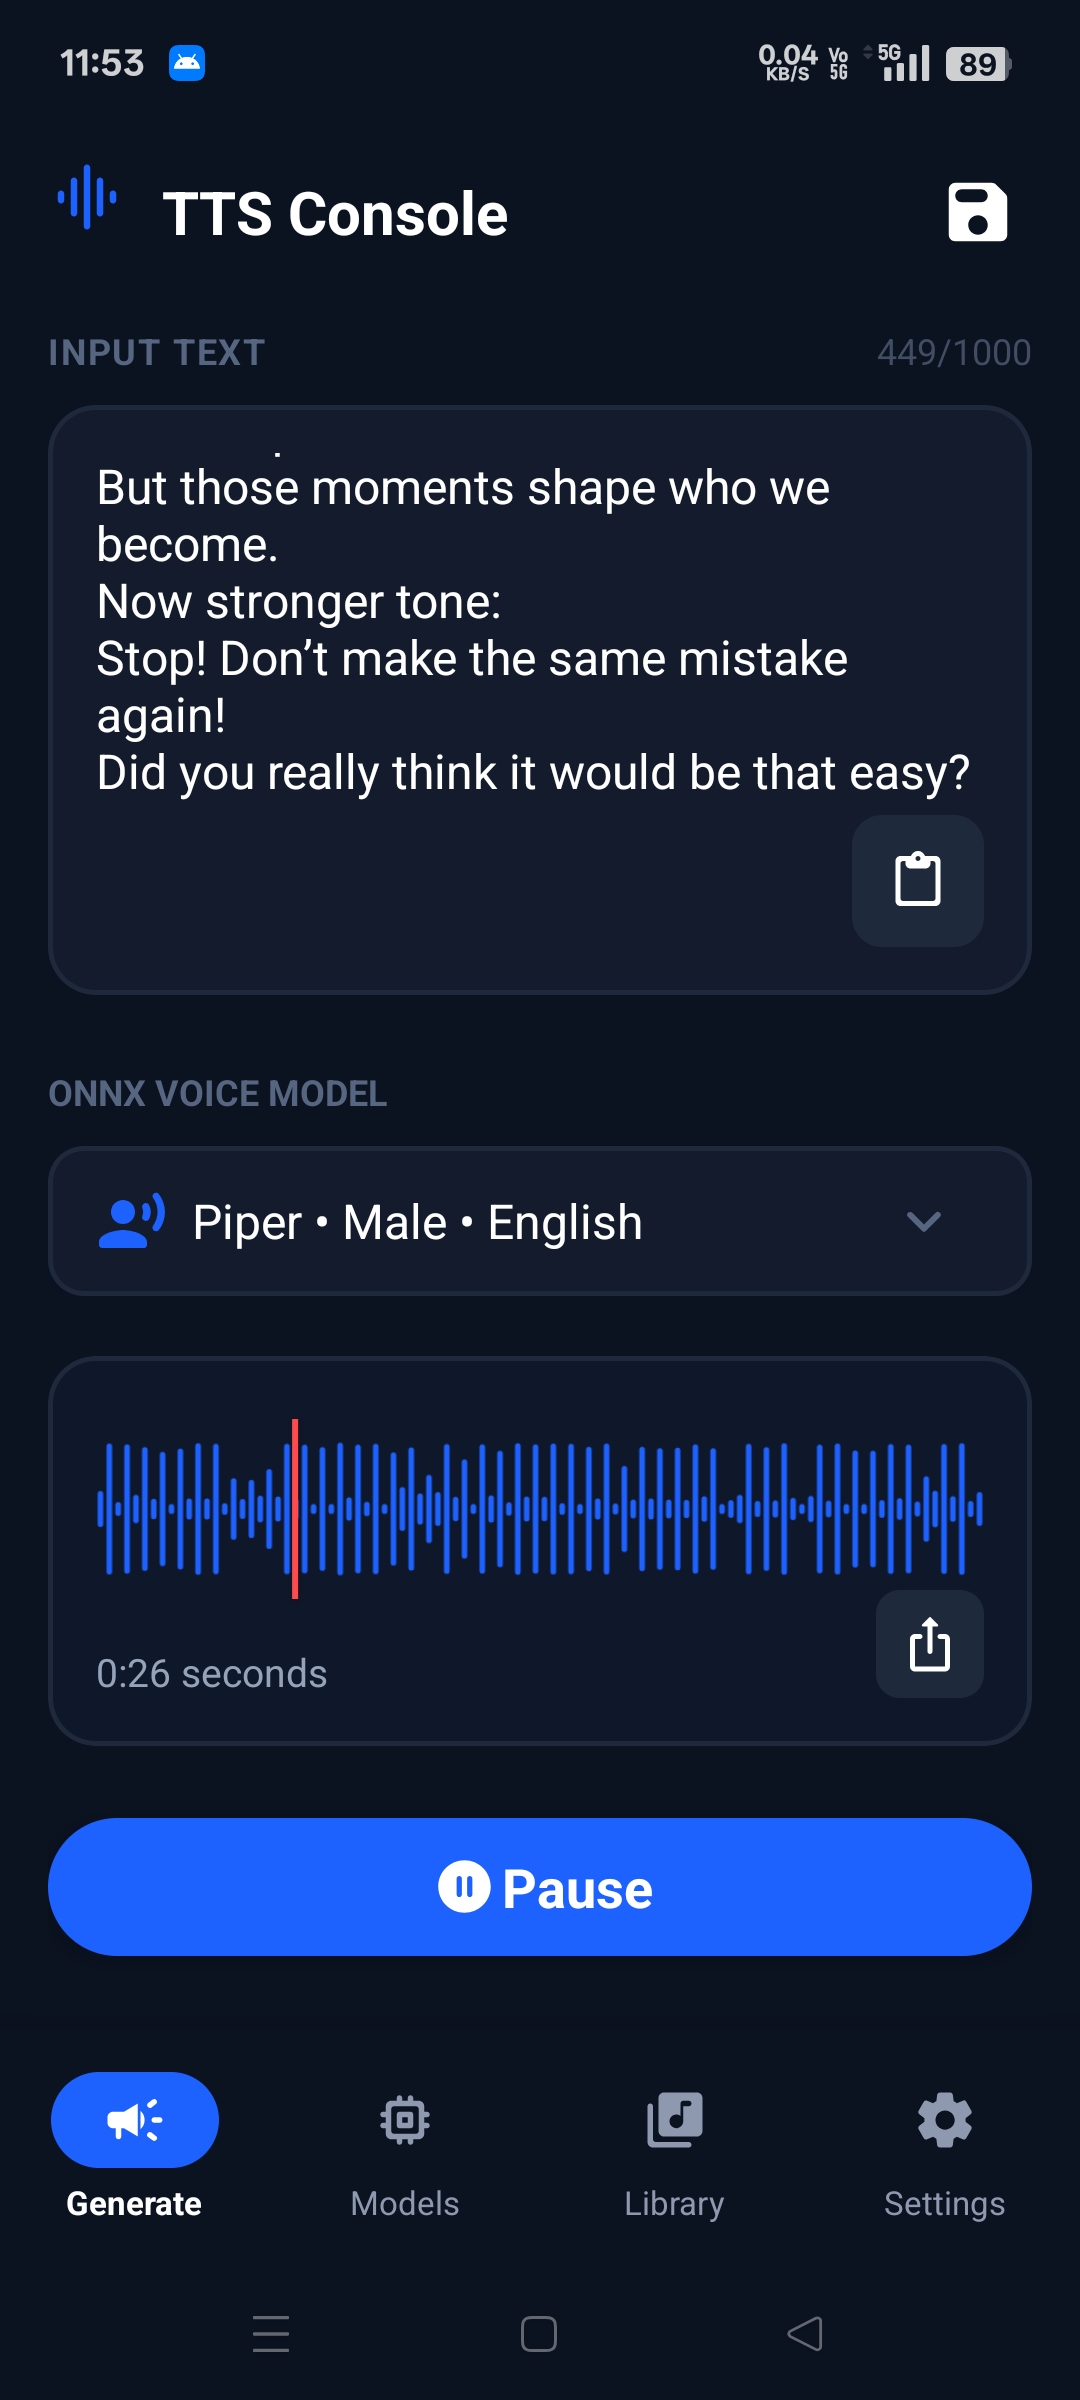 | 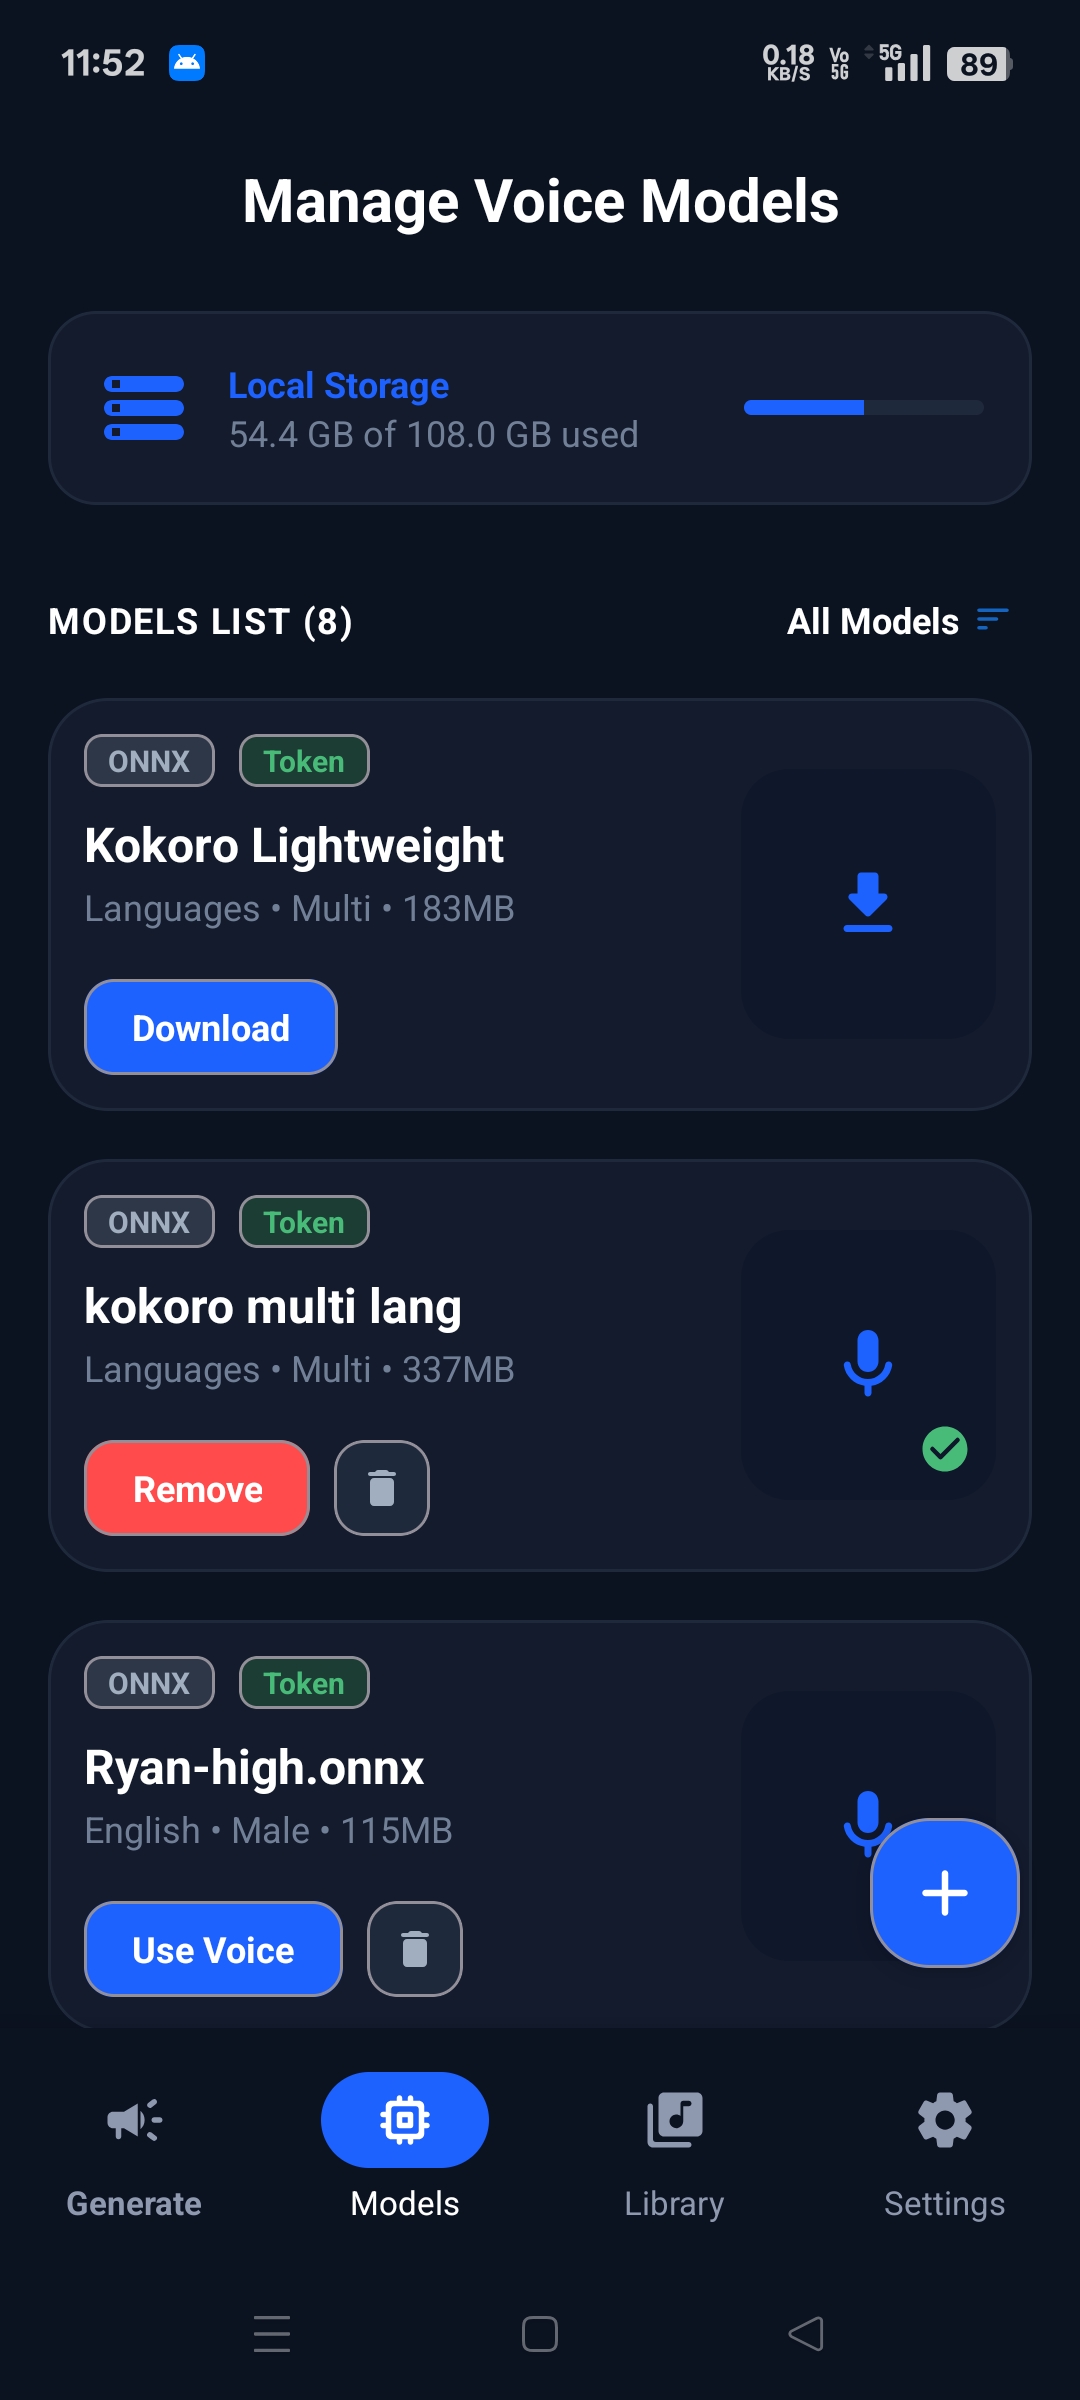 | 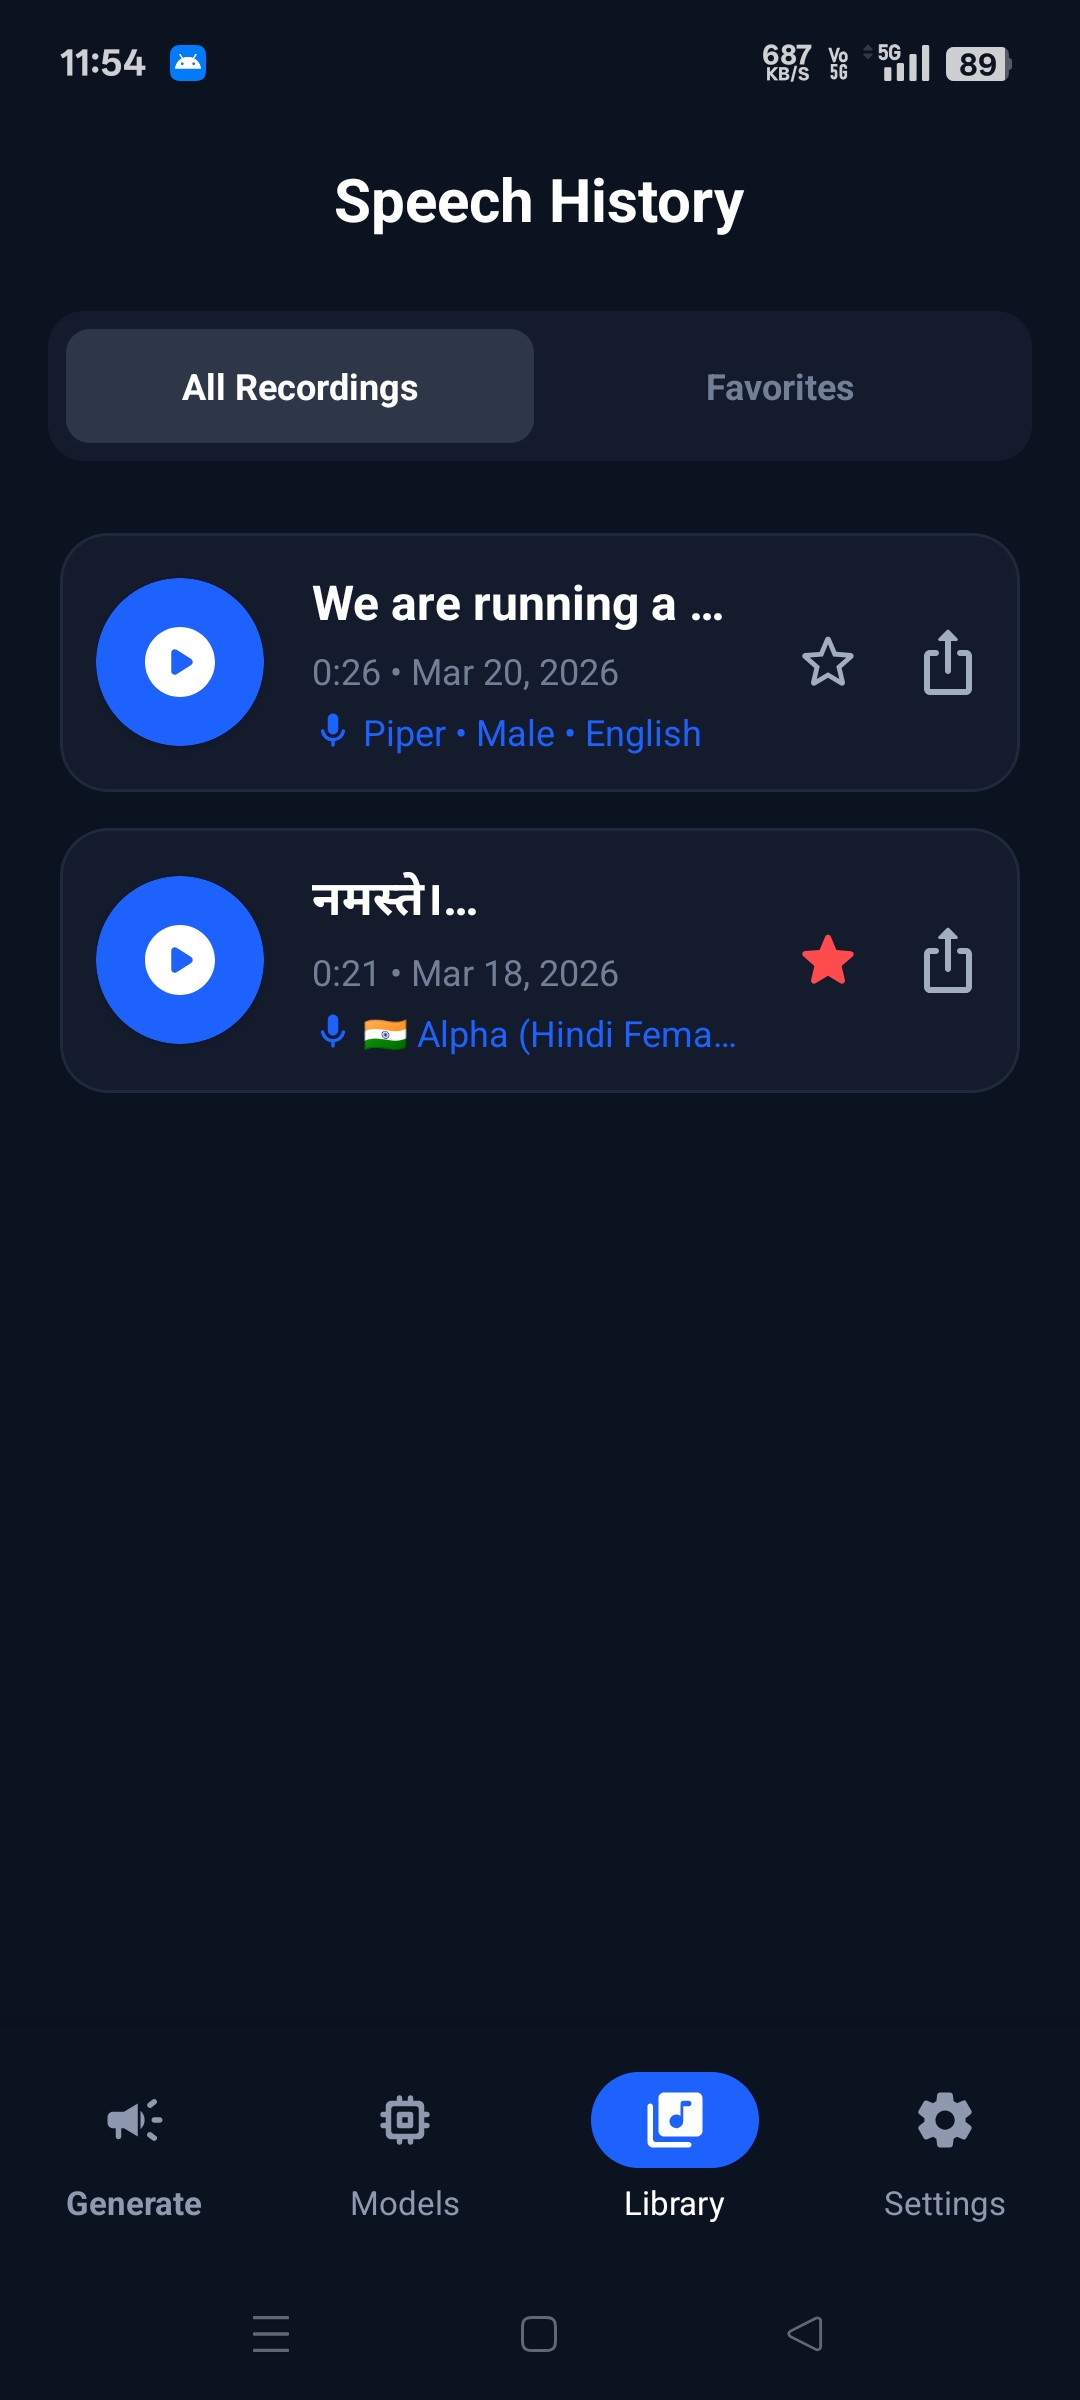 | 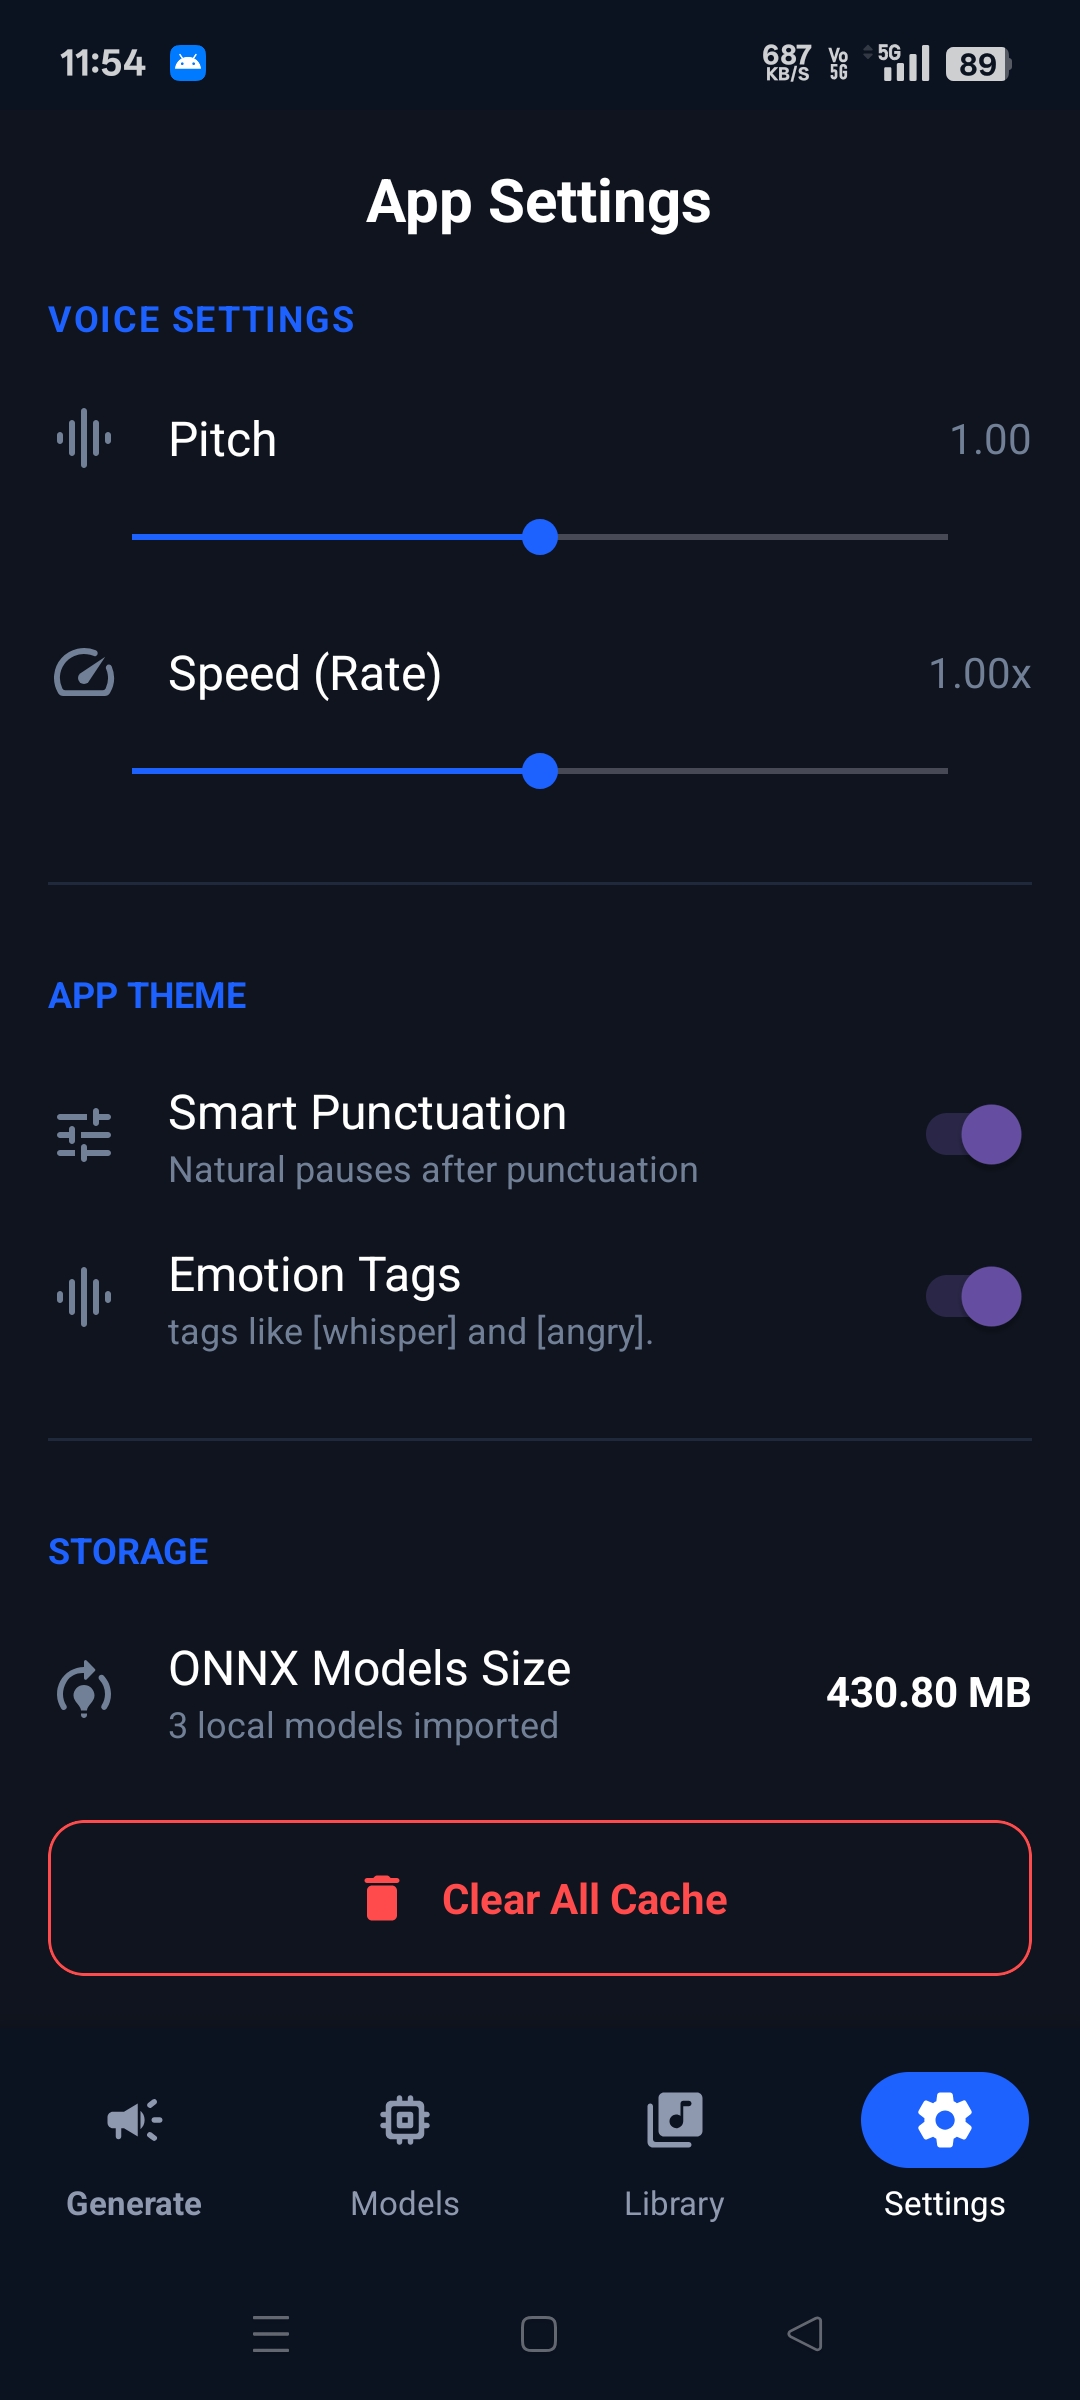 |
BreezeApp from MediaTek Research
BreezeAPP is a mobile AI application developed for both Android and iOS platforms. Users can download it directly from the App Store and enjoy a variety of features offline, including speech-to-text, text-to-speech, text-based chatbot interactions, and image question-answering
| 1 | 2 | 3 |
|---|---|---|
Open-LLM-VTuber
Talk to any LLM with hands-free voice interaction, voice interruption, and Live2D taking face running locally across platforms
See also https://github.com/t41372/Open-LLM-VTuber/pull/50
voiceapi
Streaming ASR and TTS based on FastAPI
It shows how to use the ASR and TTS Python APIs with FastAPI.
腾讯会议摸鱼工具 TMSpeech
Uses streaming ASR in C# with graphical user interface.
Video demo in Chinese: 【开源】Windows实时字幕软件(网课/开会必备)
lol互动助手
It uses the JavaScript API of sherpa-onnx along with Electron
Video demo in Chinese: 爆了!炫神教你开打字挂!真正影响胜率的英雄联盟工具!英雄联盟的最后一块拼图!和游戏中的每个人无障碍沟通!
Sherpa-ONNX 语音识别服务器
A server based on nodejs providing Restful API for speech recognition.
QSmartAssistant
一个模块化,全过程可离线,低占用率的对话机器人/智能音箱
It uses QT. Both ASR and TTS are used.
Flutter-EasySpeechRecognition
It extends ./flutter-examples/streaming_asr by downloading models inside the app to reduce the size of the app.
Note: [Team B] Sherpa AI backend also uses sherpa-onnx in a Flutter APP.
sherpa-onnx-unity
sherpa-onnx in Unity. See also #1695, #1892, and #1859
xiaozhi-esp32-server
本项目为xiaozhi-esp32提供后端服务,帮助您快速搭建ESP32设备控制服务器 Backend service for xiaozhi-esp32, helps you quickly build an ESP32 device control server.
See also
KaithemAutomation
Pure Python, GUI-focused home automation/consumer grade SCADA.
It uses TTS from sherpa-onnx. See also ✨ Speak command that uses the new globally configured TTS model.
Open-XiaoAI KWS
Enable custom wake word for XiaoAi Speakers. 让小爱音箱支持自定义唤醒词。
Video demo in Chinese: 小爱同学启动~˶╹ꇴ╹˶!
C++ WebSocket ASR Server
It provides a WebSocket server based on C++ for ASR using sherpa-onnx.
Go WebSocket Server
It provides a WebSocket server based on the Go programming language for sherpa-onnx.
Making robot Paimon, Ep10 "The AI Part 1"
It is a YouTube video, showing how the author tried to use AI so he can have a conversation with Paimon.
It uses sherpa-onnx for speech-to-text and text-to-speech.
| 1 |
|---|
TtsReader - Desktop application
A desktop text-to-speech application built using Kotlin Multiplatform.
MentraOS
Smart glasses OS, with dozens of built-in apps. Users get AI assistant, notifications, translation, screen mirror, captions, and more. Devs get to write 1 app that runs on any pair of smart glasses.
It uses sherpa-onnx for real-time speech recognition on iOS and Android devices. See also https://github.com/Mentra-Community/MentraOS/pull/861
It uses Swift for iOS and Java for Android.
flet_sherpa_onnx
Flet ASR/STT component based on sherpa-onnx. Example a chat box agent
achatbot-go
a multimodal chatbot based on go with sherpa-onnx's speech lib api.
fcitx5-vinput
Local offline voice input plugin for Fcitx5 (Linux input method framework). It uses C++ with offline ASR for speech recognition, supporting push-to-talk, command mode, and optional LLM post-processing.
Video demo in Chinese: fcitx5-vinput
Wake Word
A VS Code extension for hands-free voice-activated coding. It uses sherpa-onnx for real-time keyword spotting (KWS) to detect custom wake phrases and trigger VS Code commands by voice. Audio capture is handled by decibri, a cross-platform Node.js microphone streaming library with prebuilt native binaries.
SmartSub
SmartSub is a local-first cross-platform desktop application for the complete subtitle production pipeline: audio/video transcription, subtitle translation, proofreading, and subtitle burning/muxing.
It natively integrates sherpa-onnx to power three offline ASR engines — FunASR, Qwen3-ASR, and FireRedASR — delivering high-accuracy Chinese and multilingual speech recognition entirely on-device, with no file uploads required.
Fono
Talk to your computer. Fono is an open-source (GPL-3.0), complete voice-AI stack (speech-to-text, text-to-speech, a local LLM, wake word, speaker ID) in one small binary for the Linux, macOS, and Windows desktop. Press a key and speak: it types into any app, answers as a voice assistant, or drives a coding agent.
It uses sherpa-onnx's Supertonic TTS models for text-to-speech, with the Supertonic text frontend ported to Rust. See also #3750, which fixes dropped diacritics in the Supertonic frontend for Romanian, Czech, Polish, Hungarian, Turkish, Vietnamese, and other non-English Latin-script languages.
Domia
Domia is an open-source local AI companion you talk to, living entirely on hardware you own. Each Domia is its own character, with a distinct personality, voice, emotional state, and memory of you and its place — and it acts, not just talks: skills connect it to the real world over MCP, Home Assistant included. Domia nodes form a local peer-to-peer mesh that shares speech and reasoning compute, while room satellites bring each companion into the spaces where you live without giving up its identity. No cloud, no accounts, and no data leaving your network.
Domia runs sherpa-onnx in-process for keyword spotting, voice activity detection, streaming and offline speech recognition, and text-to-speech. Speech engines and models are selected through per-companion configuration, making it easy to match supported sherpa-onnx models to different hardware.
qwen-audio-agent
A realtime full-duplex voice runtime for AI coding agents (Claude Code, Codex, OpenCode, and other ACP agents). It uses sherpa-onnx keyword spotting with the 3M-parameter zh-en transducer model to implement a local voice wake word: the app sleeps on idle but keeps the microphone open, and the wake phrase brings the session back with no cloud calls.
Suflyor
An Android teleprompter that scrolls the script as you read it aloud. It runs two streaming Zipformer models on the phone (Russian small-ru-vosk int8 and English en-2023-06-26) and boosts the words of the script as hotwords with modified beam search. A floating window shows the text over the camera app while it records video.
- Download APK
- Website
- Android 10+ · no internet permission · GPL-3.0
Loud Caption
An open-source Flutter app for Android that turns nearby speech into large, high-contrast captions for people with hearing loss. SenseVoice ASR and Silero VAD run fully on-device through sherpa-onnx's Dart API; translation is optional and also local. No account, analytics, or cloud audio.
- Download APK
- Android 8.0+ · arm64-v8a · MIT (app code)
Recly
An open-source recorder for Galaxy Watch, Android, Apple Watch, iPhone, macOS, and Windows. Recordings go to the user's own Google Drive; there is no Recly server. The Android phone app (which also transcribes Galaxy Watch recordings) and the Windows app use sherpa-onnx for on-device transcription: Silero VAD splits each recording into speech segments, and sherpa-onnx's INT8 export of Qwen3-ASR 0.6B transcribes them. The ~1 GB model is downloaded on demand.
China Unicom 中国联通安卓 App
The Android App (version
>= 12.14.1 (2026.07.28)) usessherpa-onnxKotlin API for keyword spotting.
China Life 中国人寿 App
The Android App (version
>= 3.5.46 (2026.03.23)) usessherpa-onnxKotlin API for keyword spotting.
deepseek-harness
It uses the JavaScript npm package sherpa-onnx-node with SenseVoice for local speech recognition.
akou
An open-source (GPL-3.0-or-later) call and meeting recorder for macOS that transcribes on the machine. It records the microphone and the call audio on two channels, shows a live transcript, and lets a terminal agent such as Claude Code or Codex follow and question the call over MCP. The same core runs as a self-hosted transcription server in Docker.
It runs sherpa-onnx-node in a Bun Worker: silero-vad
splits each channel into speech segments, Parakeet TDT 0.6B v3 (OfflineRecognizer)
or streaming Nemotron (OnlineRecognizer) writes the live transcript, and TitaNet
embeddings (SpeakerEmbeddingExtractor) help tell the speakers on the call apart.
After the call, Parakeet is the fast engine of the final pass and one of the
engines of the fused pass. The larger Qwen3-ASR model runs outside sherpa-onnx, on
llama-server.
bot-reborn
A $4 toy robot driven by an old Android phone, all from one web page in Chrome. sherpa-onnx runs in the page as WebAssembly: Silero VAD decides when someone is actually talking, so only real speech is sent to STT, and an optional keyword spotter (
sherpa-onnx-kws-zipformer-zh-en-3M-2025-12-20) handles the wake word. Both run from one combined build, with the VAD symbols exported from the KWS WebAssembly target.
- Build write-up
- Live page (Chrome on Android)
Voltip
An open-source (AGPL-3.0) push-to-talk dictation app for Windows, macOS, Linux and Android: hold a hotkey, speak, and the text is inserted at the cursor in the focused app. The desktop app uses the sherpa-onnx Rust crate for on-device recognition with SenseVoice and Paraformer, a streaming Zipformer for the live preview while the user speaks, and Silero VAD to trim silence and to split recordings of up to two hours at pauses. Models are downloaded on demand.
Outmake
A free Mac app (Apple silicon, macOS 26) for running open models on the Mac itself. Its Kokoro, Kitten, Piper and Supertonic voices run on sherpa-onnx: the app downloads the osx-arm64 shared build and speaks through
sherpa-onnx-offline-tts, so those voices need no Python.
Compatibility
- Runs on
- GPU support unknown
What shows it
- no dependency or feature matches a backend row
- Native code
- Required
- Binds native code: sherpa-onnx, sherpa-onnx-sys
- Python bindings
- No Python binding crate found
- License
- Apache-2.0
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Safe Rust wrapper for sherpa-onnx speech recognition toolkit |
259,599 downloads over 30 days | 28 | 15,834 | 2.0.1 | GPU support unknown | Binds native code: sherpa-onnx, sherpa-onnx-sys | Apache-2.0 |
|
jpreprocess Listed
Japanese text preprocessor for Text-to-Speech application (OpenJTalk rewrite in rust language). Also in Speech and audio. |
14,491 downloads over 30 days | 7 | 61 | 0.15.0 | GPU support unknown | No native code found | BSD-3-Clause |
|
Safe wrapper around the Vosk API Speech Recognition Toolkit Also in Speech and audio. |
7,299 downloads over 30 days | 4 | 182 | 0.3.1 | GPU support unknown | Binds native code: vosk-sys | MIT |
|
silero Listed
Production-oriented Rust wrapper for the Silero VAD ONNX model. Also in Run and serve models. |
1,888 downloads over 30 days | 3 | 6 | 0.7.0 | CUDA, ROCm | Binds native code: ort-sys (feature coreml) | Apache-2.0 OR MIT |
|
A Rust implementation of the Qwen3 Text-to-Speech (TTS) model inference. Also in Run and serve models. |
204 binary downloads per release | Not applicable | 237 | Not measured | Not measured | None stated | |
|
kitten-tts-rs Listed
Rust port of KittenTTS — ultra-lightweight ONNX-based text-to-speech Also in Run and serve models. |
3 downloads over 30 days | 0 | 314 | 0.2.2 | CUDA | Binds native code: audiopus_sys, mp3lame-sys, ort-sys | Apache-2.0 |
|
voxr New
Audio and speech on boostr: compressed-audio decode, resampling, DSP and grapheme to phoneme, with speech synthesis (Kokoro, VITS), voice cloning (VoxCPM2), transcription with word timings (Whisper), voice activity (Silero) and audio-text scoring (CLAP), on CPU or CUDA. Also in Speech and audio. |
642 downloads over 30 days | 2 | 2 | 0.9.1 | CUDA | No native code found | Apache-2.0 |
All projects in Run and serve modelsAll projects in Speech and audio
Why FeaturedIt passes every Featured gate.
What it meets
- It has 20 active dependents and 20 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days.
- Active dependents are at 100% of their peak. Featured needs at least 50%.
- Docs are present. The release commit or a manifest ties the crate to the repository.
- No vulnerability advisory stays unpatched past the grace window. At least one version is neither a prerelease nor 0.0.x.
- The last activity is on 7 Nov 2026, 2 days ago. The rules expect an update within 1200 days. Dormancy rule
Check notes
- the latest release was packaged from a dirty working tree
Exact rules: Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 2.0.1 base 300, doubled for 259599 downloads per month, doubled for 20 active users: E = 1200 daysdormancy: last activity 2026-11-07, 2 days ago, E = 1200: activefeatured: featured: active_users 20, new_adopters 20, former_glory 1
Crates2 crates
- sherpa-onnx Primary
- sherpa-onnx-sys
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption20 active dependents, 20 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 20 | crates.io database dump | Yes | |
| New dependents (365 days) | 20 | crates.io database dump | Yes | |
| Peak active dependents | 18.5 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: 2 days ago3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-07 | GitHub repository | Yes | |
| Latest release | 2026-10-27 | crates.io database dump | Yes | |
| First release | 2026-02-23 | crates.io database dump | Yes | |
| Latest version | 2.0.1 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 40 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 40 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | none | crates.io database dump | Yes |
Distribution33 releases, 259,599 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 33 | crates.io database dump | Yes | |
| Downloads over 30 days | 259599 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository15,834 stars, 1,858 forks, 273 contributors, 2,187 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 15834 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 1858 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 273 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 2187 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | Apache-2.0 | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | GPU support unknown | crates.io database dump | No | |
| What shows each backend | no dependency or feature matches a backend row | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: sherpa-onnx, sherpa-onnx-sys | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 28 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.