ollamaMQ
App Listed
High-performance LLM backends proxy with per-user fair-share queuing, round-robin scheduling, and a real-time TUI dashboard. Built in Rust.
- Downloads
- 8
- Dependents
- Not applicable
- Stars
- 133
- Forks
- 16
- Contributors
- 3
- Commits
- 67
- Latest release
- 0.5.0 ·
About
ollamaMQ is a high-performance, asynchronous message queue dispatcher and load balancer designed to sit in front of one or more Ollama or LM Studio API instances. It acts as a smart proxy that queues incoming requests from multiple users and dispatches them in parallel to multiple backends using a fair-share round-robin scheduler with least-connections load balancing.
Read the full README
🚀 Features
- Multi-Backend Load Balancing: Distribute requests across multiple Ollama or LM Studio instances using a Least Connections + Round Robin strategy. Automatically detects backend API type (Ollama
/api/*vs OpenAI/v1/*) and routes each request only to a compatible backend — even when a specific model is requested, so an Ollama-family call never reaches an LM Studio server that merely lists the same model. - Model-Aware Routing: Automatically identifies the requested model from the request body and routes it only to backends that list that model. Among those, selection is load-aware: first to backends where the model is already loaded and ready (Ollama
/api/ps, LM Studio loaded instances; vLLM-style backends that don't report loaded state count as ready when they list the model), then to cold backends with nothing loaded, and only as a last resort to a backend that would have to evict a different loaded model — so a request forqwen3.8-27bgoes to the server that has it in GPU memory instead of making a busy server with another model load it. Name matching is deterministic and bounded — exact,:tag/case-insensitive, or publisher-/quant-suffixed variants of the same id (qwen3.8-27breachesunsloth/qwen3.8-27b@q8_0) — but never arbitrary substrings (so it will not be routed to an unrelated...-abliteratedbuild). - Smart Model Matching: Robust matching that handles common variations like
:latesttags and case-insensitivity. For example, a request forllama3will correctly matchllama3:lateston the backend. - Model Control: Load and unload models on connected backends (Ollama and LM Studio 0.3.6+) directly from the TUI (
L/U) or the admin HTTP API — without touching the backend servers themselves. - Parallel Processing: Unlike basic proxies,
ollamaMQcan process multiple requests simultaneously (one per available backend), significantly increasing throughput for multiple users. - Aggregated Model Listings:
GET /api/tagsandGET /v1/modelsare answered by the proxy from every compatible backend at once, not routed to one of them. Each backend's own listing is merged (so per-model metadata likesize,digestanddetailsis preserved exactly as that backend reported it) and deduplicated by name/id. Clients therefore see everything the proxy can route to, and the list no longer changes from one poll to the next depending on which backend happened to answer. - Backend Health Checks: Automatically monitors backend status every 10 seconds. All backends are probed concurrently, each request bounded by its own 5-second timeout, so one unresponsive backend can't hold up everyone else's status. Probes cover both API type (Ollama vs OpenAI) and the list of currently available models (via
/api/tagsand/v1/models). Endpoints a backend rejects are remembered and skipped until re-checked, so incompatible backends don't spam warnings. Offline instances are temporarily skipped and marked in the TUI. - Fail-Fast for Unsatisfiable Requests: If no online backend can ever serve a queued request (wrong API family or model absent everywhere), it is answered with
503afterstuck_timeoutseconds instead of hanging forever. Requests merely waiting for a busy or loading backend are unaffected. - Per-Model Concurrency Limits: Each model entry's
max_concurrent_requestscaps how many in-flight requests one backend may serve for that model, bounded globally bysettings.max_concurrent_per_backend(default 1 — the historical one-request-per-backend behavior; raise it to let a single backend handle several requests at once). The limit is keyed on the model's base name, so it applies no matter how the client spells it —qwen3.8-27b,qwen/qwen3.8-27bandunsloth/qwen3.8-27b@q8_0all draw on the same budget as the configured entry. - Metadata Reads Never Queue:
/,/api/tags,/api/ps,/api/version,/api/show,/v1/modelsand/v1/models/{model}don't run inference, so they neither wait for a free backend slot nor occupy one — a chat UI polling/api/tagson a timer is answered immediately instead of queueing behind a multi-minute generation (or a model load) with the defaultmax_concurrent_per_backend: 1. - Per-User Queuing: Each user (identified by the
X-User-IDheader) has their own FIFO queue, capped at 100 waiting requests — beyond that the proxy answers429rather than growing the queue. - Bounded Memory: A queued request holds its whole body until a backend takes it, so bodies are capped two ways:
settings.max_body_bytesper request (default 64 MiB,413beyond it) andsettings.max_queued_bytesacross all queues at once (default 512 MiB,503beyond it). A request is always admitted when the queues are empty, so an oversized body can never lock the proxy out of making progress./api/blobs/{digest}keeps a separate 1 GiB allowance for model-layer uploads. - Fair-Share Scheduling: Prevents any single user from monopolizing all available backends. A user's turn is decided by their recent load: every dispatched request adds to a score that halves every 5 minutes, so a long-idle user isn't punished for past traffic and a newcomer can't monopolize the proxy while "catching up". Requests are charged when dispatched regardless of outcome, so a client whose requests always fail or disconnect can't keep jumping the queue.
- Transparent Header Forwarding: Full support for all HTTP headers (including
X-User-ID) passed to and from the backend, ensuring compatibility with tools like Claude Code. - VIP & Boost Modes: Absolute priority (VIP) or increased frequency (Boost) for specific users.
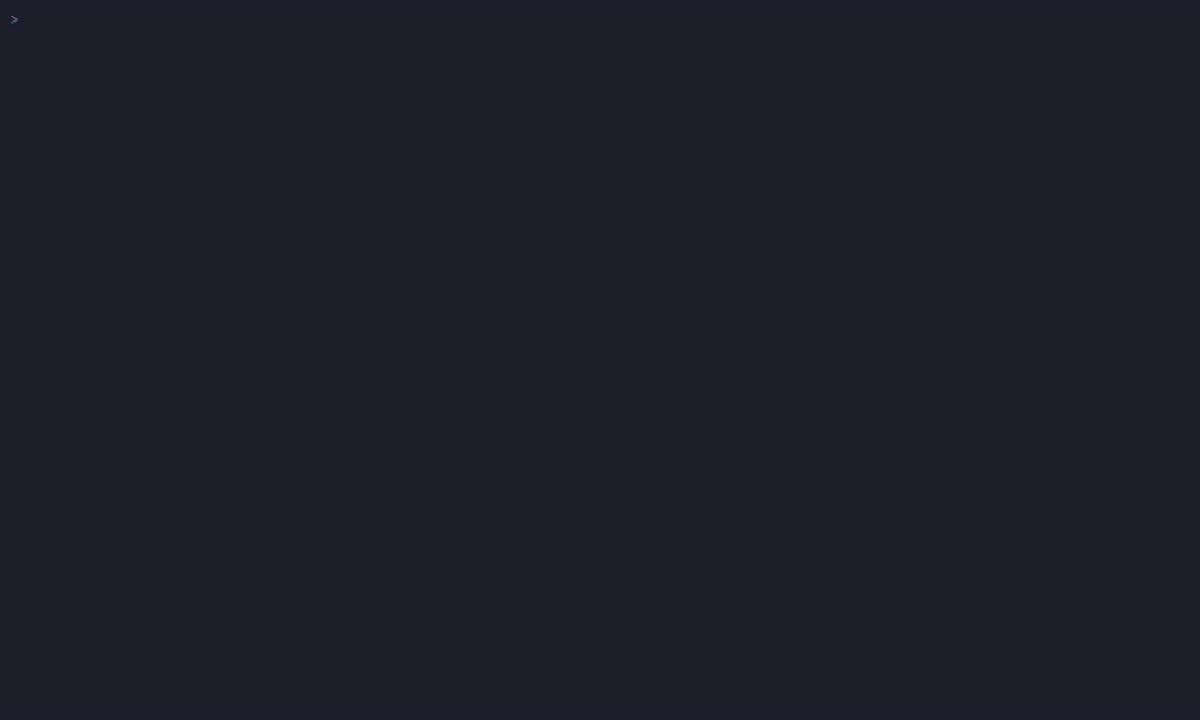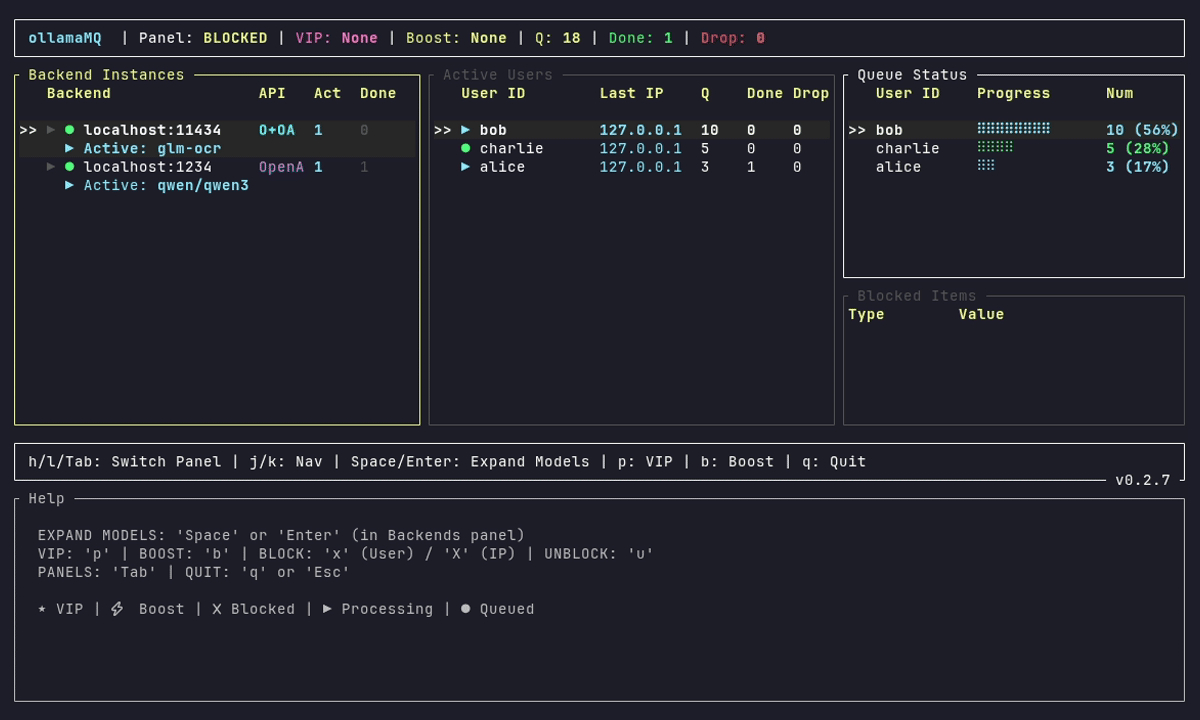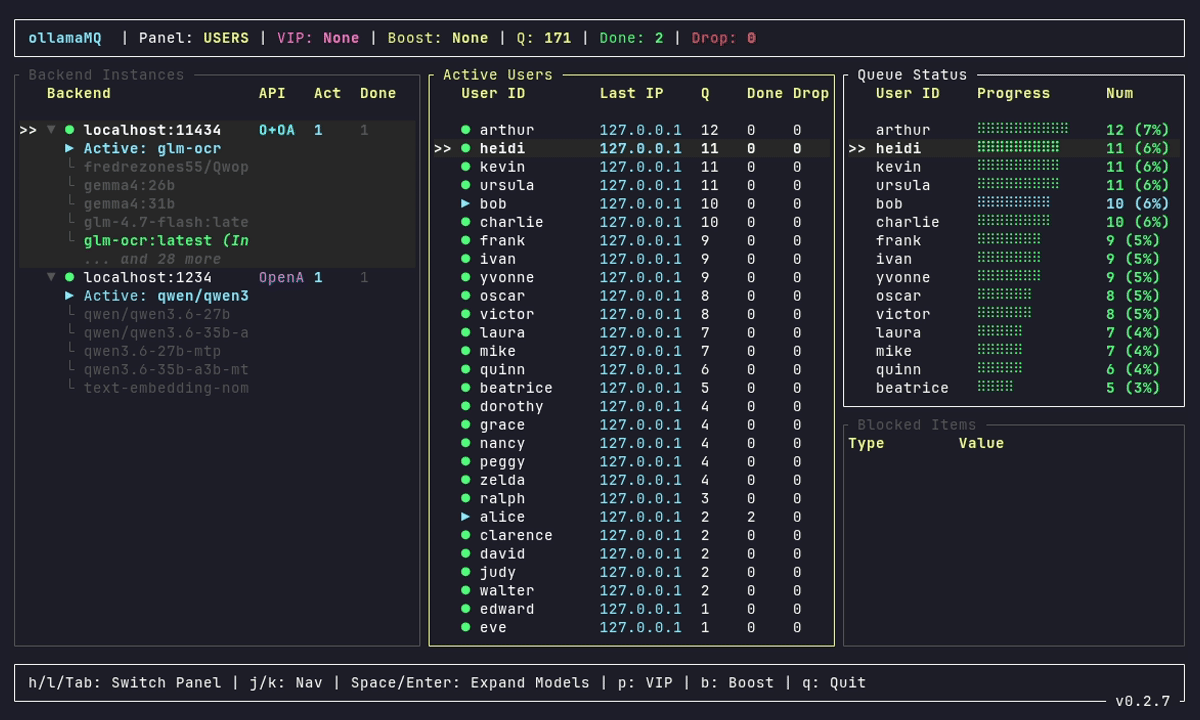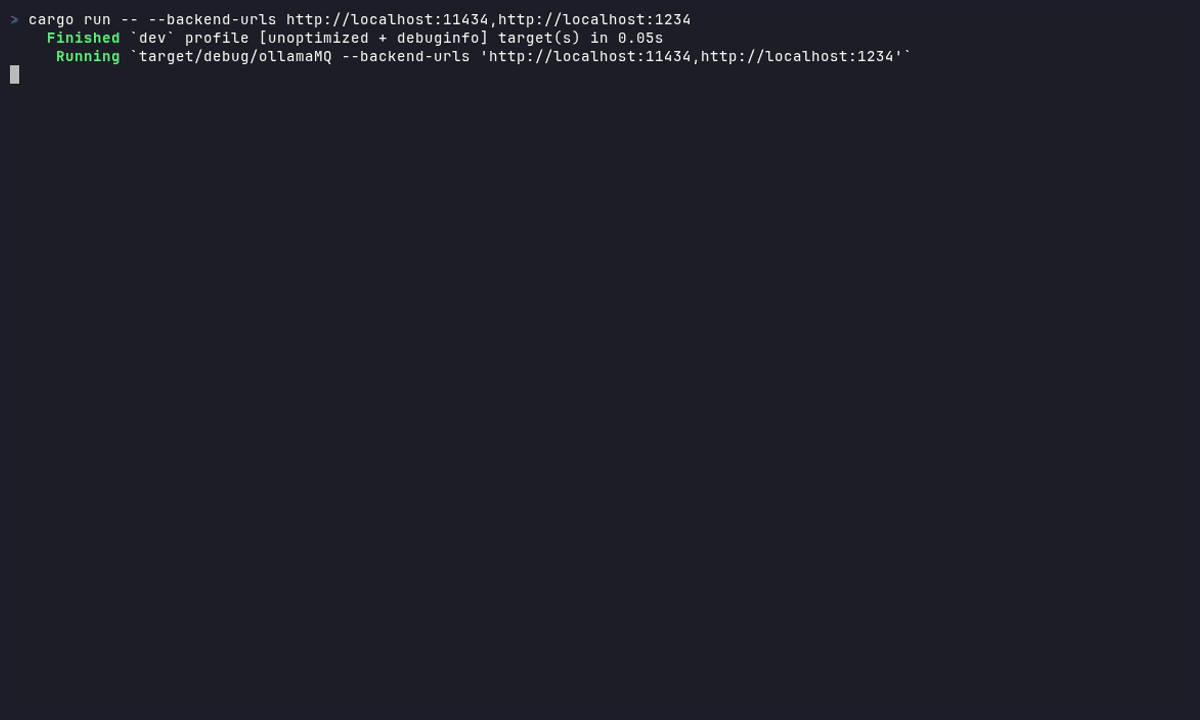
- Real-Time TUI Dashboard: Monitor backend health, active requests, queue depths, and throughput in real-time.
- OpenAI Compatibility: Supports standard OpenAI-compatible endpoints.
- Async Architecture: Built on
tokioandaxumfor high concurrency.
🛠️ Installation
Ensure you have Rust (2024 edition or later) and Ollama installed.
Option 1: Install via Cargo (Recommended)
cargo install ollamaMQ
Option 2: From Source
Clone the repository:
git clone https://github.com/Chleba/ollamaMQ.git
cd ollamaMQ
Build and install locally:
cargo install --path .
🏃 Usage
Docker Installation
Using Docker Compose (Recommended)
- Ensure Docker and Docker Compose are installed.
- Start your local Ollama instance (defaulting to
localhost:11434). - Run:
docker compose up -d
Using Docker CLI
First build the image from the local Dockerfile:
docker build -t chlebon/ollamamq .
Then run the container:
docker run -d \
  --name ollamamq \
  -p 11435:11435 \
  --restart unless-stopped \
  chlebon/ollamamq
API Proxying
Point your LLM clients to the ollamaMQ port (11435) and include the X-User-ID header.
Supported Endpoints:
GET /health(Internal health check)GET /(Backend Status)POST /api/generatePOST /api/chatPOST /api/embedPOST /api/embeddingsGET /api/tags(answered by the proxy — merged from all Ollama-compatible backends; decision-model backends contribute their model names, never a live listing, since they implement no/api/*route)POST /api/showPOST /api/createPOST /api/copyDELETE /api/deletePOST /api/pullPOST /api/pushGET/HEAD/POST /api/blobs/{digest}GET /api/psGET /api/versionPOST /v1/chat/completions(OpenAI Compatible)POST /v1/completions(OpenAI Compatible)POST /v1/embeddings(OpenAI Compatible)GET /v1/models(OpenAI Compatible — answered by the proxy, merged from all backends that can list models, and always answered in OpenAI'sdata/idenvelope regardless of which backend answered first)GET /v1/models/{model}(OpenAI Compatible)POST /v1/systemone(System One decision models — CLM, Laya, Kev; routed to those backends only)
Example (cURL):
curl -X POST http://localhost:11435/api/chat \
  -H "X-User-ID: developer-1" \
  -d '{
    "model": "qwen3.5:35b",
    "messages": [{"role": "user", "content": "Explain quantum computing."}],
    "stream": true
  }'
Decision-model backends (System One)
A third backend family: "decision model" servers — clm-serve (CLM), laya-serve (Laya), kev.serve (Kev) — which answer POST /v1/systemone with typed decisions (choice / score / noul) instead of text. The body is passed through byte-for-byte (never parsed), and it goes only to backends of this family: these servers implement no /api/* route at all, so /api/chat, /api/tags and /v1/chat/completions are never sent to them, and they never answer a route their family cannot serve — such a request is refused, not misrouted. Only /v1/systemone is proxied; /v1/rank and Kev's /v1/systemone/permute|separate are not.
- Detection — a backend answering
GET /v1/modelswith{"models":[{"name":…}]}(CLM, Kev) is identified as System One; a 2xxGET /healthmarks a backend online when nothing else identifies it. Laya exposes no listing endpoint and therefore cannot be positively detected — pin it withkind: systemoneon the backend entry. Auth on all three isAuthorization: Bearer <key>, which is exactly what the existingtoken:key already sends (CLM_API_KEY/LAYA_API_KEY/KEV_API_KEY). - Model names — CLM and Kev are listed by the probe automatically. A Laya server has nothing to list, so its checkpoints must be declared under
models:: there, amodels:entry makes a name routable, not merely pinned, and amodels:entry with nobackends:selector is admitted on every backend — use an explicit selector as soon as you run more than one backend. - Listings — decision-model names appear in the aggregated
GET /v1/modelsandGET /api/tagseven though only/v1/systemonecan serve them. That is deliberate: ollamaMQ aggregates one namespace and routes by capability./v1/modelsalways answers in OpenAI'sdata/id,/api/tagsalways in Ollama'smodels/name; names for a backend that cannot list anything are synthesised from proxy state and appended after the live entries, so real metadata (size,digest,description) always wins. - Model control is not available for this family — see Model Control.
- ⚠️
laya-servebinds0.0.0.0:8000andclm-servebinds0.0.0.0:8700open by default — anyone on the LAN can run inference against them. Bind them to loopback or set their API key.kev.servebinds127.0.0.1:8008. clm-serveneeds a separate vLLM pooling encoder (defaulthttp://127.0.0.1:8090/v1/embeddings) and answers502while that is down. That is CLM replying, not ollamaMQ declaring the backend dead.
curl -X POST http://localhost:11435/v1/systemone \
  -H "X-User-ID: developer-1" \
  -d '{"model": "clm-latest", "state": "billed twice, refund please or we cancel",
       "questions": {"refund": {"type": "noul", "instructions": "Is a refund justified?"}}}'
Model Control (Admin API)
Models can be loaded and unloaded on connected backends without touching the backend servers. Supported backends:
- Ollama — no dedicated endpoint exists; loading is a
POST /api/generatewith an empty prompt (the scheduler loads the model and returns immediately), unloading is the same call withkeep_alive: 0. - LM Studio 0.3.6+ — the native
POST /api/v1/models/load/POST /api/v1/models/unloadendpoints (unload targets a specific loaded instance). Older LM Studio versions are detected and a friendly error points at thelms load/lms unloadCLI. - Plain OpenAI backends (vLLM, etc.) have no control API and are rejected with a clear error.
- System One decision-model servers (CLM, Laya, Kev) have no model-control API either — no load/unload, no
keep_alive, not even/api/ps. Residency is configured on the server itself (e.g.LAYA_PRELOAD,LAYA_MAX_LOADED), so amodels:entry for these backends only makes the name routable and pins it; it never starts a load.
All three endpoints are served by the proxy itself (they are never proxied to a backend) and are protected by the same optional OLLAMA_MQ_API_KEY auth as the proxy routes.
GET /admin/models
Per-backend inventory: index, URL, online status, detected API type, LM Studio flag, active request count, available models, currently loaded models, and any in-flight control operation.
curl -s http://localhost:11435/admin/models | python3 -m json.tool
POST /admin/models/load and POST /admin/models/unload
Body:
{ "backend": 0, "model": "llama3", "num_ctx": 16384, "keep_alive": 3600, "identifier": "big-ctx" }
backend accepts:
- a numeric index (0-based, in the order of
--backend-urls), - a URL (exact or substring match), or
"any"— the proxy picks a suitable online, idle backend (for load: the first backend where the model resolves; for unload: the first backend that actually has it loaded).
model is resolved against each backend's model list: exact match, then :latest/case-insensitive, then a unique substring (admin ops only). Ambiguous names are rejected — the proxy never guesses.
Optional fields (load only):
num_ctx— max context window, sent as Ollamaoptions.num_ctxor LM Studiocontext_length(omitted = backend default).keep_alive— overrides--load-keep-alive(seconds) for this load.-1= keep forever.identifier— free-form label shown with the operation in the TUI and API responses.
Responses:
| Status | Meaning |
|---|---|
202 | Accepted — the operation started in the background (response body contains the canonical model name and the backend URL). |
400 | Bad request — empty model, backend offline, unsupported backend type, or unloading a model that is not loaded. |
404 | Unknown backend, model not found on the backend, or no suitable backend for "any". |
409 | Conflict — another control operation is already in flight on that backend, or the backend is busy with active requests. |
# Load (llama3 resolves to llama3:latest)
curl -s -X POST http://localhost:11435/admin/models/load \
  -H "Content-Type: application/json" \
  -d '{"backend": 0, "model": "llama3"}'

# Unload by URL (frees GPU memory on Ollama)
curl -s -X POST http://localhost:11435/admin/models/unload \
  -H "Content-Type: application/json" \
  -d '{"backend": "http://10.0.0.2:11434", "model": "qwen2.5:7b"}'

# Let the proxy pick a backend
curl -s -X POST http://localhost:11435/admin/models/load \
  -H "Content-Type: application/json" \
  -d '{"backend": "any", "model": "llama3:latest"}'

# With API-key auth enabled
curl -s http://localhost:11435/admin/models -H "Authorization: Bearer supersecret"
Note: Ollama keeps a model loaded for keep_alive seconds only (its own default is 5 minutes). A control "load" sends the --load-keep-alive value (default 24 h) so the model actually stays resident; an "unload" sends keep_alive: 0.
Logging
ollamaMQ uses tracing and behaves differently depending on the mode:
- TUI mode (default, interactive terminal): Logs are written to the
ollamamq.logfile in the current working directory. This keeps the terminal clear for the dashboard. Default level isinfo. --no-tuimode (Docker/CI/service): Logs are written to stderr at a default level ofdebug, so you can see everything — backend health checks, per-request routing, backend detection, and errors. This is ideal for capturing output via the systemd journal, Docker, or piping to a file.
Override the level at any time with the standard RUST_LOG environment variable:
# Most verbose (all debug detail)
RUST_LOG=debug ollamaMQ --no-tui

# Quieter (info + errors only)
RUST_LOG=info ollamaMQ --no-tui
Running as a systemd Service
To run ollamaMQ as a background service with full log visibility in the journal:
Copy the provided service file to your system's unit directory:
sudo cp ollamamq.service /etc/systemd/system/Edit the file and set the correct
ExecStartpath to your installed binary (e.g.~/.cargo/bin/ollamaMQ) and your backend URLs:ExecStart=/usr/local/bin/ollamaMQ --no-tui --port 11435 --backend-urls http://localhost:11434Note: If you installed
ollamaMQwithcargo install, the binary is at~/.cargo/bin/ollamaMQ, not/usr/local/bin/ollamaMQ. PointExecStartat the real path, or create a symlink so the default path works:# Find the real path which ollamaMQ # Option A: edit ExecStart to use the real path # Option B: symlink it to the expected location sudo ln -s "$HOME/.cargo/bin/ollamaMQ" /usr/local/bin/ollamaMQReload systemd, then enable and start the service:
sudo systemctl daemon-reload
sudo systemctl enable --now ollamamq
Follow the logs in real time via the journal:
journalctl -u ollamamq -fOr show the most recent 100 lines:
journalctl -u ollamamq -n 100
Because --no-tui defaults to debug logging on stderr, all dispatcher events (backend health, request routing, errors) are captured in the journal — no separate log file needed.
⚙️ Configuration (appconf.yaml)
Everything about your ollamaMQ instance lives in one YAML file with three sections: backends (what to connect to), settings (runtime options) and models (which models to load where). The default path is appconf.yaml in the working directory; override it with -c/--model-config. A missing file is fine — defaults apply.
# --- Backends: every Ollama / LM Studio / OpenAI-compatible server you want to use
backends:
  - http://10.137.1.1:11434      # plain URL — no auth
  - url: http://10.137.1.2:1234   # object form adds an optional API token,
    token: "some-api-key"         # sent as `Authorization: Bearer <token>`
  - url: http://10.137.1.3:8000   # and can pin the API family for a backend
    kind: systemone               # nothing can detect (a Laya-style server)

# --- Runtime settings (all optional — defaults shown)
settings:
  port: 11435                  # proxy listen port (default 11435)
  host: 127.0.0.1              # bind interface; use 0.0.0.0 for LAN/Docker access (default 127.0.0.1)
  timeout: 300                 # per-request timeout in seconds (default 300)
  load_keep_alive: 86400       # how long model-control loads stay resident; -1 = forever (default 86400)
  allow_all_routes: false      # also proxy non-standard endpoints as fallback (default false)
  stuck_timeout: 60            # fail-fast 503 after N s when no backend can ever serve a queued request (default 60)
  max_concurrent_per_backend: 1  # global cap of in-flight requests per backend; raise to let one backend handle several at once (default 1).
                                 # Metadata reads (/api/tags, /api/ps, /api/show, /v1/models, ...) are exempt: they
                                 # neither wait for a slot nor take one.
  max_body_bytes: 67108864       # largest request body accepted, 413 beyond it (default 64 MiB).
                                 # /api/blobs/{digest} keeps its own 1 GiB allowance.
  max_queued_bytes: 536870912    # total bytes of request bodies waiting in all queues, 503 beyond it
                                 # (default 512 MiB); a request is always admitted when the queues are empty
  request_log_path: ollamamq-requests.jsonl   # request/response JSONL log file (default shown)
  request_log_max_bytes: 10485760             # rotate when the file exceeds this (default 10 MiB)
  request_log_max_files: 5                    # rotated files kept as .0 .1 ... (default 5)
  log_content_limit: 65536                    # max body bytes captured per record, min 1024 (default 64 KiB)

# --- Models to load on startup / reload, via the model-control logic
models:
  - name: "gpt-oss:120b"        # model name as the backend knows it
    identifier: "my-gpt"        # label attached to this entry's load op (TUI / admin API)
    max_ctx: 128000             # context window — Ollama num_ctx / LM Studio context_length
    keep_alive: 86400           # seconds the model stays resident after load (Ollama; -1 = forever)
    max_concurrent_requests: 3  # in-flight requests allowed for this model on one backend (default 1)
    backends:                   # which backends to load it on — every backend whose URL contains the string is
                                #   targeted, so `- :11434` covers all backends on that port. A non-empty list also
                                #   PINS routing for this model (see below); omitted/empty = any suitable backend
      - http://10.137.1.1:11434
Upgrading:
max_body_bytesreplaces a flat 1 GiB limit that applied to every route. If you push bodies larger than 64 MiB through anything other than/api/blobs/{digest}, raise it.
How it's applied:
backendsandsettingsare read at startup only — restart to change them.- A backend's optional
tokenis sent asAuthorization: Bearer <token>on every request the proxy makes to that backend — proxied inference, model listings/metadata reads, health probes and model load/unload. It's meant for backends behind an authenticated reverse proxy (LM Studio, vLLM, …). Client credentials are for proxy-level authentication and never reach the backend: when a token is configured it always wins — any clientAuthorizationheader is replaced and any clientX-Api-Keyheader is stripped; without a configured token the client's ownAuthorization/X-Api-Keyheaders are forwarded untouched. modelsis applied automatically at startup (once backend probes have run) and re-applied any time you pressrin the TUI. Application is additive: each target endpoint is checked live first (Ollama/api/ps, LM Studio loaded instances), so models already resident there — e.g. still loaded from an earlier run because of longkeep_alive— are skipped instead of being loaded twice; everything else gets a load started. It never unloads anything, and loads for the same backend run one at a time (backends reject parallel control ops). Every attempt, including skips, is reported in the TUI Logs panel (⟳ CTL) and in the log output.- A backend won't accept a load while it is serving requests, so each entry waits for that backend to go idle (up to 5 minutes) before loading. Without this, restarting the proxy under live traffic meant every configured model was refused on the spot and never retried — leaving models unloaded, or loaded with the wrong
max_ctx. - Explicit CLI flags override file values when given (e.g.
--backend-urlsoverbackends,--port/--host/--timeoutoversettings). - A non-empty
models[].backendslist also pins routing: requests for that model are only sent to the listed backends (case-insensitive substring URL match, the same rule as load targeting) and never to other suitable ones. If none of the pinned backends is online/eligible, the request fails with HTTP 503 afterstuck_timeout(error:no configured backend available for model '<model>') instead of being routed elsewhere. Ifbackendsis empty/omitted, or the model is not in the config at all, the existing behavior applies — any online backend that lists the model may serve it. - A
models:entry does two things: it loads the model where the backend supports control, and it makes the name routable on the selected backends even where nothing can list it. The second half is the only way to reach a decision-model server with no listing endpoint (Laya), and it applies to backends without model control as well — for them the entry names and pins, it does not load.
See appconf.yaml.example for a fully commented template.
Request logging
Every proxied request (IN) and upstream response (OUT) is written as JSON lines to settings.request_log_path (default ollamamq-requests.jsonl). Each line is one JSON object:
| field | meaning |
|---|---|
ts | unix time in milliseconds |
dir | IN (proxied request) or OUT (upstream response) |
user | client address |
model | model name, when resolvable (otherwise null) |
backend | upstream backend URL (may be null; <all backends> for aggregated model listings) |
method | HTTP method |
path | request path |
status | response status code (responses only) |
bytes | total body size in bytes |
content_type | body content type |
content | body preview, truncated to log_content_limit with a ...[truncated: N bytes total] marker |
Rotation: when the file exceeds request_log_max_bytes it is renamed to .0 (existing .0 → .1, etc.), at most request_log_max_files rotated files are kept and the oldest is deleted. The current file size is re-read at startup, so sizing/rotation survives restarts.
TUI: the bottom "Requests" panel shows these newest-first with a one-line content preview; press Enter on a row for the full-content detail view (j/k or PgUp/PgDn scroll, q/Esc/Enter close).
Note: request/response headers are deliberately not logged — this keeps API keys out of the file.
🐳 Docker
Docker Compose
The included docker-compose.yml provides a ready-to-use configuration:
services:
  ollamamq:
    build: .
    image: chlebon/ollamamq:latest
    container_name: ollamamq
    ports:
      - "11435:11435"
    environment:
      # URLs of backend servers (Ollama, LM Studio, etc.)
      - BACKEND_URLS=http://host.docker.internal:11434,http://host.docker.internal:1234
      - PORT=11435
      - TIMEOUT=300
      - RUST_LOG=info
    command: ["--no-tui"]
    extra_hosts:
      - "host.docker.internal:host-gateway"
    restart: unless-stopped
    healthcheck:
      test: ["CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:11435/health"]
      interval: 30s
      timeout: 10s
      retries: 3
      start_period: 10s
Note for Linux Users: When running in Docker on Linux to access a host-based Ollama:
- Listen on all interfaces: Ollama must be configured to listen on
0.0.0.0. You can do this by settingexport OLLAMA_HOST=0.0.0.0before starting the Ollama service (or editing the systemd unit file). - Firewall: Ensure your firewall (e.g.,
ufw) allows traffic from the Docker bridge (usually172.17.0.1/16) to port11434. - Host Gateway: The
extra_hostssetting indocker-compose.ymlmapshost.docker.internalto your host's IP address.
Dockerfile
The Dockerfile uses a multi-stage build:
- Build stage: Uses
rust:1.97-alpine(pinned) to compile the release binary - Runtime stage: Uses
alpine:3.20with onlyca-certificatesfor a minimal footprint (~10MB)
Environment Variables
| Variable | Description | Default |
|---|---|---|
BACKEND_URLS | URLs of the backend servers (Ollama, LM Studio, …) | http://localhost:11434 |
OLLAMA_URLS | Legacy alias for BACKEND_URLS (used only when BACKEND_URLS is unset) | — |
PORT | Port for ollamaMQ to listen on | 11435 |
HOST | Host/interface to bind to | 0.0.0.0 |
TIMEOUT | Request timeout in seconds | 300 |
OLLAMA_MQ_API_KEY | Optional API key; enables auth when set | (unset — auth disabled) |
🔒 Security (Optional API-Key Auth)
By default, ollamaMQ only listens on loopback (127.0.0.1), so it is only reachable from the local machine. If you expose it to the network with --host 0.0.0.0, set the OLLAMA_MQ_API_KEY environment variable to a secret key to protect the proxy. Auth is opt-in: if the variable is unset or empty, behavior is unchanged and no key is required.
When a key is set, every request except /health must present it via one of two headers:
Authorization: Bearer <key>X-API-Key: <key>
Requests with a missing or wrong key get 401 Unauthorized ({"error":"unauthorized"}). The /health endpoint always stays unauthenticated so health checks and Docker healthchecks keep working.
# Enable auth
OLLAMA_MQ_API_KEY=supersecret ollamaMQ --no-tui

# Call the API with the key (either header works)
curl -X POST http://localhost:11435/api/chat \
  -H "Authorization: Bearer supersecret" \
  -H "X-User-ID: developer-1" \
  -d '{"model": "llama3", "messages": [{"role": "user", "content": "Hi"}]}'

# ...or with X-API-Key
curl http://localhost:11435/api/tags -H "X-API-Key: supersecret"

# /health never requires a key
curl http://localhost:11435/health
In Docker, just pass the variable through — the binary reads it directly from the environment:
docker run -d --name ollamamq -p 11435:11435 \
  -e OLLAMA_MQ_API_KEY=supersecret \
  chlebon/ollamamq
Port Configuration
- 11435: The proxy port that clients connect to (exposed by default)
- 11434: The Ollama server port (internal, not exposed)
To change the proxy port, use the PORT environment variable:
docker run -d \
  --name ollamamq \
  -p 8080:8080 \
  -e PORT=8080 \
  chlebon/ollamamq
📦 Publishing to Docker Hub
To publish a new version of ollamaMQ to Docker Hub, follow these steps:
Update Version: Update the version number in
Cargo.toml.Build and Tag:
# Build the image for the current version
docker build -t chlebon/ollamamq:v0.2.4 .

# Tag it as latest
docker tag chlebon/ollamamq:v0.2.4 chlebon/ollamamq:latest
Push to Hub:
# Log in to Docker Hub (if not already logged in)
docker login

# Push the versioned tag
docker push chlebon/ollamamq:v0.2.4

# Push the latest tag
docker push chlebon/ollamamq:latest
🧪 Development
Stress Testing
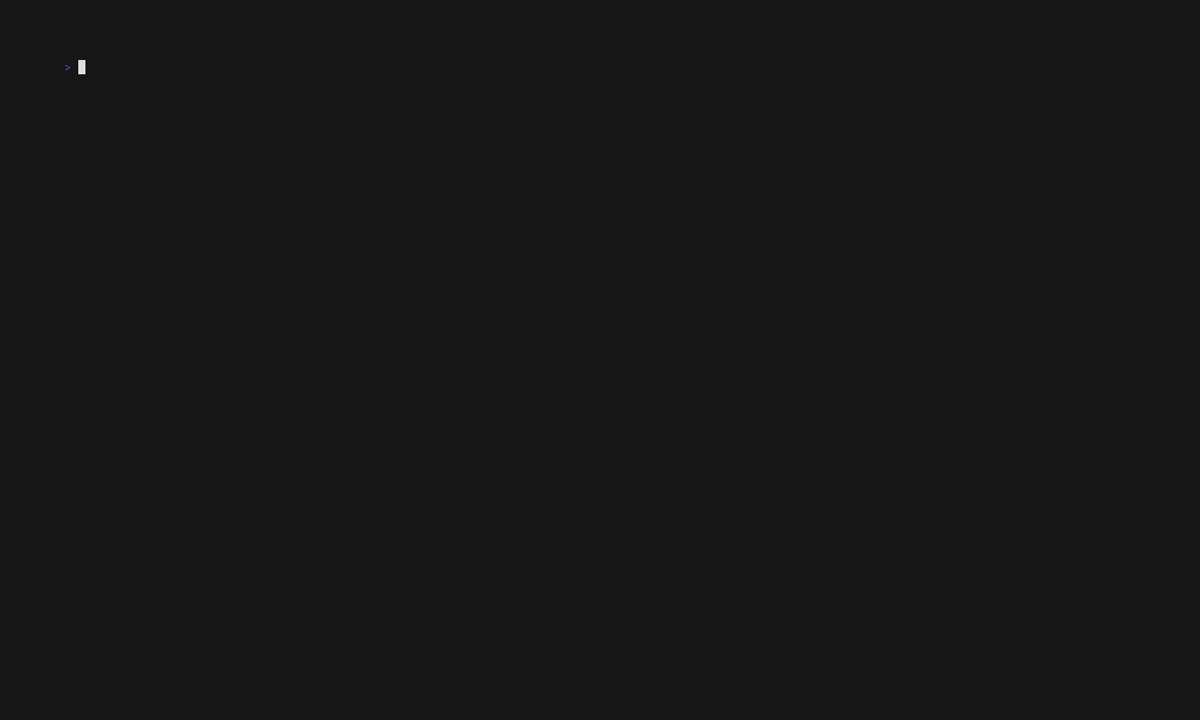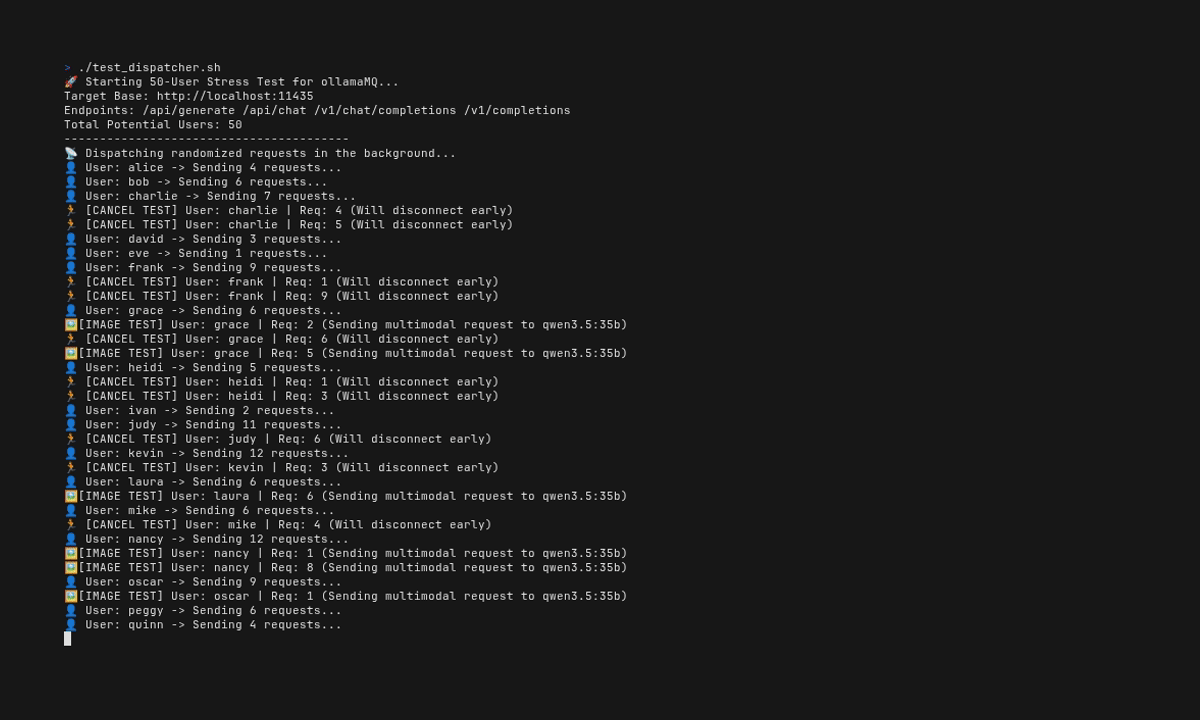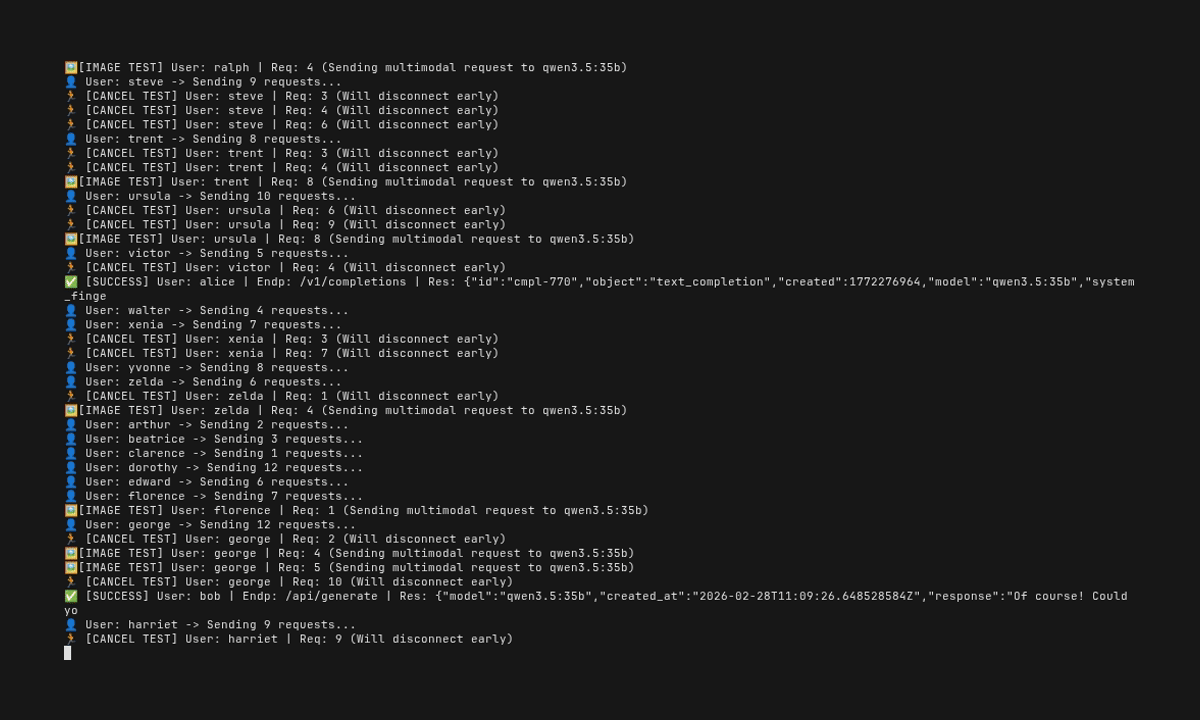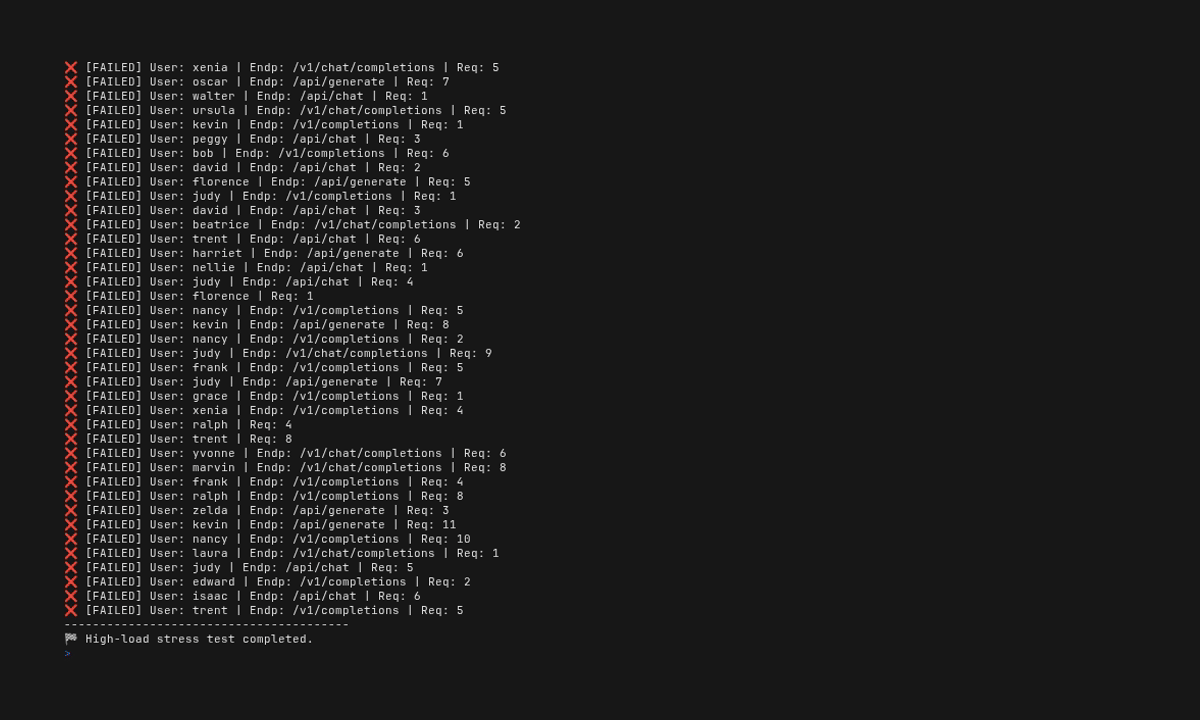
You can use the provided test_dispatcher.sh script to simulate multiple users and verify the dispatcher's behavior under load:
./test_dispatcher.sh
📝 License
This project is licensed under the MIT License - see the LICENSE file for details (if applicable).
Compatibility
- Runs on
- GPU support unknown
What shows it
- no dependency or feature matches a backend row
- Native code
- None found
- No native code found
- Python bindings
- No Python binding crate found
- License
- MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
High-performance LLM backends proxy with per-user fair-share queuing, round-robin scheduling, and a real-time TUI dashboard. Built in Rust. |
8 downloads over 30 days | Not applicable | 133 | 0.5.0 | GPU support unknown | No native code found | MIT |
|
All-in-one LLM CLI tool featuring Shell Assistant, Chat-REPL, RAG, AI Tools & Agents, with access to OpenAI, Claude, Gemini, Ollama, Groq, and more. |
28,422 binary downloads per release | Not applicable | 10,556 | 0.30.0 | GPU support unknown | No native code found | Apache-2.0 OR MIT |
|
llm Featured
A Rust library unifying multiple LLM backends. |
7,669 downloads over 30 days | 34 | 365 | 1.3.8 | GPU support unknown | Binds native code: alsa-sys (feature audio-example) | MIT |
|
aisdk Listed
An open-source Rust library for building AI-powered applications, inspired by the Vercel AI SDK. It provides a robust, type-safe, and easy-to-use interface for interacting with various Large Language Models (LLMs). |
36,877 downloads over 30 days | 4 | 263 | 0.6.1 | GPU support unknown | No native code found | MIT |
|
Terminal UI to chat with large language models (LLM) using different model backends, and integrations with your favourite editors! |
5,642 binary downloads per release | Not applicable | 772 | 0.13.0 | GPU support unknown | No native code found | MIT |
|
A high-performance AI Gateway written in Rust, providing OpenAI-compatible APIs with intelligent routing, load balancing, and enterprise features |
34 binary downloads per release | Not applicable | 123 | 0.10.1 | GPU support unknown | No native code found | MIT |
|
An open protocol that gives AI agents a secure, sandboxed place to run code and use tools — with lean context usage. AXP works alongside MCP |
Not measured | Not applicable | 3 | Not measured | Not measured | Not measured | Apache-2.0 |
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- The check holds no value for Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days. A gate that lacks its signal does not pass.
What else the check found
- The last activity is on 30 Oct 2026, 10 days ago. The rules expect an update within 365 days. Dormancy rule
Not measured: Homebrew installs on request over 365 days, Repology repository families, Docker pull growth over 90 days.
Exact rules: Listed, Featured app. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: app: E = 365 daysdormancy: last activity 2026-10-30, 10 days ago, E = 365: activefeatured: not featured: unknown homebrew_on_request_365d, repology_families, docker_pull_growth_90dlisted: listed: no archive, new or featured rule applies
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the GitHub repository description
- crates.io database dump, fetched
- GitHub releases, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption0 binary downloads per release4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | Not measured | Yes | ||
| New dependents (365 days) | Not measured | Yes | ||
| Peak active dependents | Not measured | Yes | ||
| Active dependents as a share of the peak | Not measured | Yes | ||
| Binary downloads per release | 0 | GitHub releases | Yes |
MaintenanceLatest human commit: 10 days ago4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-10-30 | GitHub repository | Yes | |
| Latest release | 2026-09-27 | GitHub releases | Yes | |
| First release | 2026-02-27 | crates.io database dump | Yes | |
| Latest version | 0.5.0 | crates.io database dump | No | |
| Days the oldest outside issue waits for a reply | 9 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 2 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | No | |
| Published docs | Not measured | Yes | ||
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityNot measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | Not measured | Yes | ||
| RustSec unmaintained advisory | Not measured | Yes | ||
| Deprecation notice | Not measured | Yes | ||
| Deprecated requirement | Not measured | Yes |
Distribution15 releases, 8 downloads over 30 days6 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 15 | crates.io database dump | No | |
| Downloads over 30 days | 8 | crates.io database dump | No | |
| Binary downloads over the last 3 releases | 0 | GitHub releases | Yes | |
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | Not measured | Yes | ||
| Crate deleted from crates.io | Not measured | Yes |
Repository133 stars, 16 forks, 3 contributors, 67 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 133 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 16 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 3 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 67 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | GPU support unknown | crates.io database dump | No | |
| What shows each backend | no dependency or feature matches a backend row | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | No native code found | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | Not measured | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.