llmserve
App Listed
TUI for serving local LLM models. Pick a model, pick a backend, serve it.
- Downloads
- 424
- Dependents
- Not applicable
- Stars
- 417
- Forks
- 26
- Contributors
- 4
- Commits
- 86
- Latest release
- 0.0.7 ·
About

Any model. Any backend. One TUI to serve them all.
If you're like me, you've got dozens of GGUF and MLX models scattered across LM Studio, HuggingFace cache, and random directories — and you want to quickly spin one up with whichever inference engine happens to be installed. llmserve is the front door for that. It finds your models, finds your backends, and gets out of the way.
It auto-detects locally installed inference engines (llama-server, KoboldCpp, LocalAI, MLX, and more), discovers model files across multiple locations, and lets you launch servers with live log output — all from a single interactive TUI. No config files to write, no CLI flags to remember.
Sister project: Use llmfit to figure out which models fit your hardware, then use llmserve to actually run them.
Install
Quick install (macOS / Linux)
curl -fsSL https://llmserve.axjns.dev/install.sh | sh
Homebrew
brew trust AlexsJones/llmserve
brew tap AlexsJones/llmserve
brew install llmserve
Homebrew 5.1.15+ refuses to load formulae from untrusted third-party taps, so
brew trustis required beforebrew install. On older versions thebrew trustline is unnecessary (and unavailable); skip it.
Cargo
cargo install llmserve
Read the full README
From source
cargo install --path .
Usage
llmserve
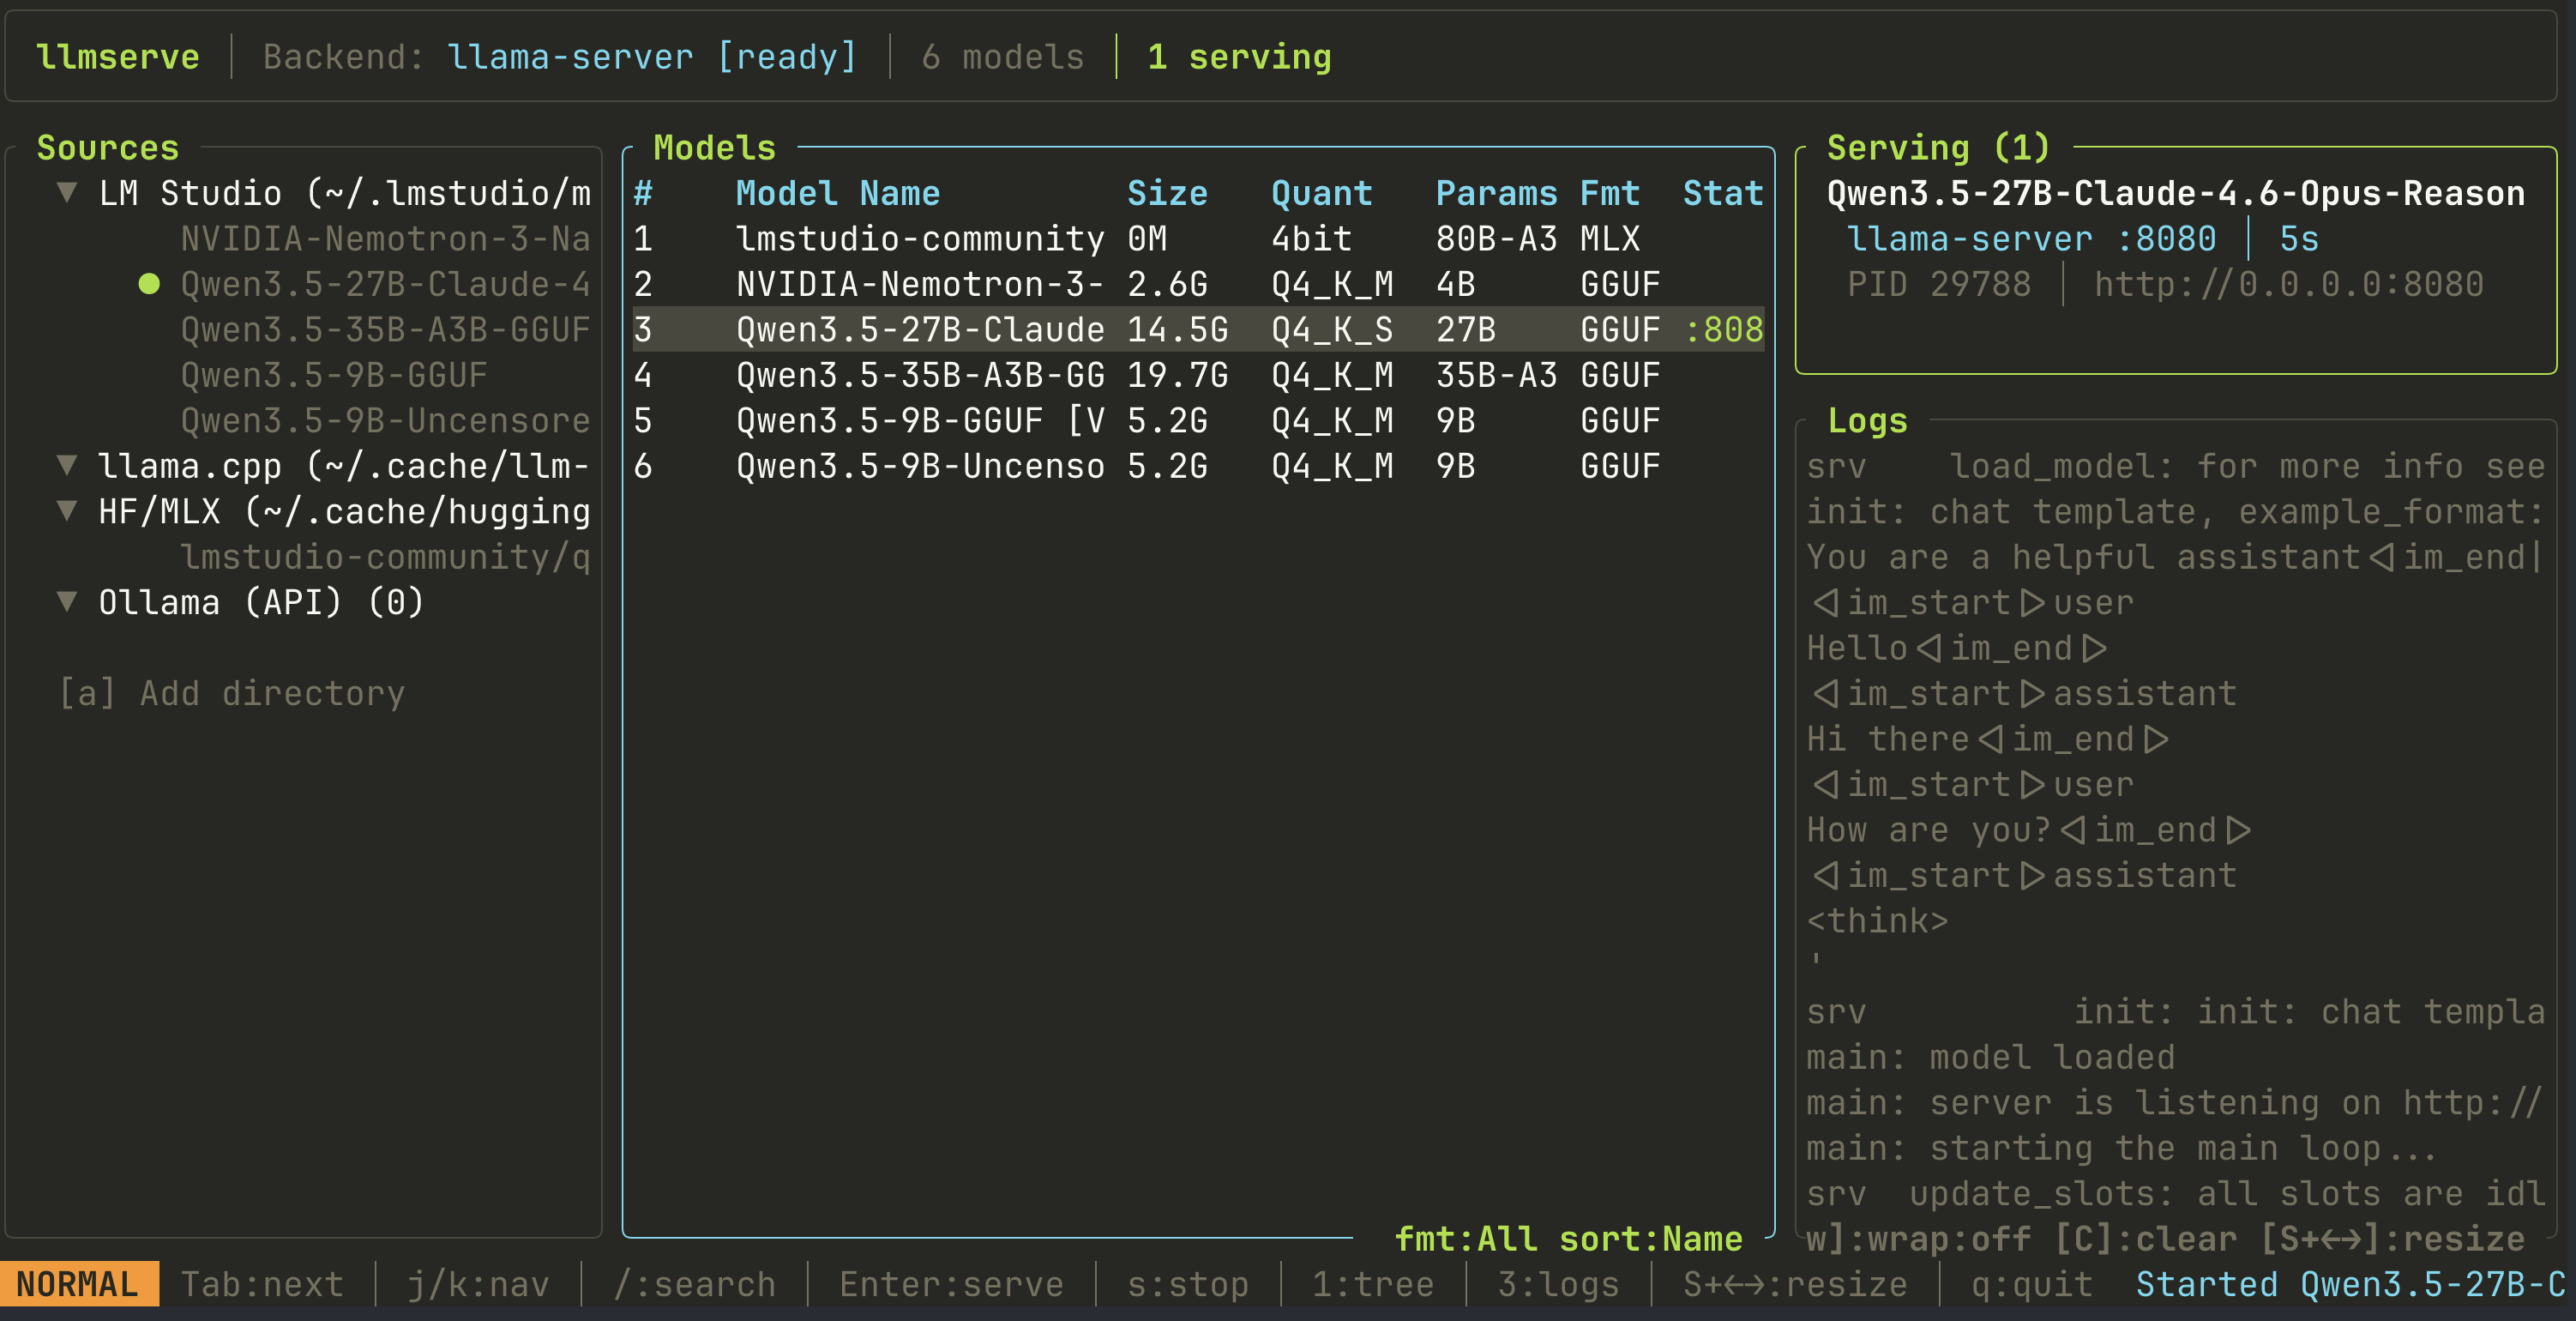
The TUI has three panels:
| Panel | Position | Toggle | Description |
|---|---|---|---|
| Sources | Left | 1 | File tree of model locations with counts and serving indicators |
| Models | Center | Always on | Searchable, sortable model table with serve status |
| Serve/Logs | Right | 3 | Running server cards + live backend output logs |
Focus cycles between visible panels with Tab. Resize the focused panel with Shift+Left/Shift+Right.
Keybindings
| Key | Action |
|---|---|
Tab | Cycle focus: Sources -> Models -> Logs |
1 / 3 | Toggle sources / logs panel |
j/k | Navigate (works in focused panel) |
g/G | Jump to top / bottom |
Ctrl-d/Ctrl-u | Half page down / up |
Shift+Left/Right | Resize focused panel |
Enter | Models: open serve dialog / Sources: filter by source |
Space | Sources: expand/collapse node |
a | Add model directory (with tab-completion) |
x | Remove custom directory (sources panel) |
/ | Search / filter models by name |
b | Pick default backend |
f | Cycle format filter (All / GGUF / MLX) |
o | Cycle sort (Name / Size / Source) |
s | Stop a server |
S | Stop all servers |
w | Toggle log word wrap |
C | Clear dead server logs |
r | Refresh models and backends |
t | Cycle theme |
q | Quit |
Serve dialog
When you press Enter on a model, a confirmation dialog opens:
| Key | Action |
|---|---|
h/l or Left/Right | Cycle through backends (shows availability + already-serving status) |
p or Tab | Edit port number |
Enter/y | Launch server |
Esc/n | Cancel |
The dialog shows the resolved preset for the selected backend (context size, flash attention, batch size, GPU layers, extra args).
Features
- Auto-detects inference backends — llama-server, KoboldCpp, LocalAI, MLX (Apple Silicon), Ollama, vLLM, LM Studio
- Source tree — collapsible file tree showing all model locations with model counts and green dots for serving models
- Add directories live — press
a, type a path with tab-completion, and the directory is scanned immediately and persisted to config - Filter by source — click a source in the tree to show only its models
- Per-backend presets — context size, batch size, GPU layers, threads, and extra CLI args per backend
- Serve multiple models — run different models on different backends simultaneously, each on its own auto-assigned port
- Live log output — stdout/stderr from inference backends streams into the logs panel in real-time with color-coded error/warning highlighting
- Crash diagnostics — when a server exits, its logs are preserved so you can see exactly what went wrong
- Word wrap — press
wto wrap long log lines in the logs panel - Resizable panels — Shift+arrows to grow/shrink any focused panel
- Toggleable panels —
1hides/shows sources,3hides/shows logs - 7 themes — Default, Dracula, Solarized, Nord, Monokai, Gruvbox, Catppuccin Mocha
- Vision model support — auto-detects
mmprojprojector files and passes--mmprojto llama-server
Configuration
Config lives at ~/.config/llmserve/config.toml. Created automatically on first run.
# Extra directories to scan for model files
extra_model_dirs = [
    "/path/to/more/models",
]

# Global defaults
preferred_port = 8080
preferred_host = "0.0.0.0"
default_ctx_size = 8192
flash_attn = true

# Preferred backend on startup (auto-detected if not set)
# default_backend = "llama-server"

# theme = "Dracula"
Backend presets
Each backend has its own preset that overrides global defaults. Missing fields fall back to the global value.
[presets.llama-server]
ctx_size = 8192
flash_attn = true
batch_size = 2048
gpu_layers = -1          # -1 = all layers to GPU
threads = 8
extra_args = ["--mlock", "--cont-batching"]

[presets.koboldcpp]
ctx_size = 8192
gpu_layers = -1
port = 5001

[presets.localai]
ctx_size = 8192
port = 8080

[presets.mlx]
ctx_size = 4096
port = 8081
| Field | Type | Description |
|---|---|---|
ctx_size | integer | Context window size |
host | string | Bind address |
port | integer | Bind port |
flash_attn | boolean | Enable flash attention (llama-server) |
batch_size | integer | Batch size for prompt processing |
gpu_layers | integer | GPU layers to offload (-1 = all) |
threads | integer | CPU threads for inference |
extra_args | string[] | Extra CLI arguments passed to the backend |
Backend detection
llmserve detects 7 backends at startup. Backends that can serve local model files are marked with a checkmark:
| Backend | Local GGUF | Local MLX | Detection | Env override |
|---|---|---|---|---|
| llama-server | Yes | — | which llama-server | — |
| KoboldCpp | Yes | — | binary + API :5001 | KOBOLDCPP_HOST |
| LocalAI | Yes | — | binary + API :8080 + Docker | LOCALAI_HOST |
| MLX | — | Yes | python3 -c "import mlx_lm" (macOS) | — |
| Ollama | — | — | GET :11434/api/tags | OLLAMA_HOST |
| vLLM | — | — | binary + API :8000 | VLLM_HOST |
| LM Studio | — | — | GET :1234/v1/models | LMSTUDIO_HOST |
Backends that can't serve local files (Ollama, vLLM, LM Studio) are detected but show a clear reason in the serve dialog. They use their own model registries or manage their own servers.
Model discovery
| Source | Default path |
|---|---|
| LM Studio | ~/.lmstudio/models/ |
| llama.cpp | ~/.cache/llm-models/ |
| HuggingFace/MLX | ~/.cache/huggingface/hub/ (mlx-community repos) |
| Ollama | Via API |
| Custom | extra_model_dirs in config |
Development
make build       # Debug build
make test        # Unit + integration tests (CI-safe)
make test-local  # All tests including local model serve rotation
make clippy      # Lint
make fmt         # Format
make install     # Install to ~/.cargo/bin
Project structure
src/
  main.rs       — Terminal init/restore, main loop
  lib.rs        — Module exports for integration tests
  app.rs        — App state, input modes, navigation, filtering, serve lifecycle
  backends.rs   — Backend detection (7 backends: llama-server, KoboldCpp, LocalAI, MLX, Ollama, vLLM, LM Studio)
  config.rs     — Config + per-backend presets, load/save TOML
  events.rs     — Crossterm event handling, vim-style keybindings
  models.rs     — Model discovery from disk + APIs
  server.rs     — Server launch/monitor/stop, non-blocking log capture
  theme.rs      — 7 color themes
  ui.rs         — Ratatui rendering (3-panel layout, popups, log viewer)
tests/
  serve_integration.rs — Integration tests (serve, verify HTTP, rotate backends)
Companion to llmfit
llmserve is designed as a companion to llmfit:
- llmfit answers: "Which models fit my hardware?" — scores models across quality, speed, fit, and context
- llmserve answers: "Let me serve this one right now" — picks a model, picks a backend, launches it
Both share the same TUI patterns (vim keys, ratatui, crossterm) and theme system.
License
Compatibility
- Runs on
- GPU support unknown
What shows it
- no dependency or feature matches a backend row
- Native code
- None found
- No native code found
- Python bindings
- No Python binding crate found
- License
- MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
TUI for serving local LLM models. Pick a model, pick a backend, serve it. |
424 binary downloads per release | Not applicable | 417 | 0.0.7 | GPU support unknown | No native code found | MIT |
|
Efficent platform for inference and serving local LLMs including an OpenAI compatible API server. Also in Build LLM apps and agents. |
138 binary downloads per release | Not applicable | 739 | Not measured | Not measured | MIT | |
|
Middleware for serving deep learning models with batched prediction Also in Run and serve models. |
76 downloads over 30 days | 0 | 22 | 0.2.5 | GPU support unknown | No native code found | Apache-2.0 |
|
Inference server for LLMs, speech and embeddings: OpenAI-compatible routes with streaming, plus speech synthesis (TTS) and transcription (ASR). Serves Llama, Mistral, Qwen, Mamba2, MLA+MoE and hybrid models from SafeTensors, AWQ, GPTQ and GGUF. Also in Build LLM apps and agents. |
8 binary downloads per release | Not applicable | 7 | 0.7.1 | CUDA, WebGPU | Binds native code: ring (feature distributed) | Apache-2.0 |
|
oxibonsai Listed
Pure Rust 1-bit LLM inference engine for PrismML Bonsai models — umbrella crate Also in Build LLM apps and agents. |
1 downloads over 30 days | 0 | 137 | 0.2.3 | CUDA, Metal | No native code found | Apache-2.0 |
|
needle-rs New
600 KB WASM runtime for Cactus Compute's Needle AI tool-calling models, Needle 3, 2 and 1 from one build. Browser, Cloudflare Workers, Node.js, Python, C FFI and no_std. Token-exact with the JAX reference. No backend, no API key. Also in Run and serve models. |
126 downloads over 30 days | 0 | 107 | 0.3.1 | GPU support unknown | No native code found | MIT |
|
Zero-overhead, terminal-native local-LLM orchestrator. Run any engine, any model via the same proxy. Also in Build LLM apps and agents. |
41 binary downloads per release | Not applicable | 288 | 0.11.0 | GPU support unknown | Binds native code: tree-sitter, tree-sitter-language | MIT |
All projects in Build LLM apps and agentsAll projects in Run and serve models
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- Every version is 0.0.x.
What else the check found
- The last activity is on 26 Oct 2026, 14 days ago. The rules expect an update within 365 days. Dormancy rule
Exact rules: Listed, Featured app. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: app: E = 365 daysdormancy: last activity 2026-10-26, 14 days ago, E = 365: activefeatured: not featured: every version is 0.0.xlisted: listed: no archive, new or featured rule applies
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- GitHub releases, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption424 binary downloads per release4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | Not measured | Yes | ||
| New dependents (365 days) | Not measured | Yes | ||
| Peak active dependents | Not measured | Yes | ||
| Active dependents as a share of the peak | Not measured | Yes | ||
| Binary downloads per release | 424 | GitHub releases | Yes |
MaintenanceLatest human commit: 14 days ago4 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-10-26 | GitHub repository | Yes | |
| Latest release | 2026-07-10 | GitHub releases | Yes | |
| First release | 2026-03-22 | crates.io database dump | Yes | |
| Latest version | 0.0.7 | crates.io database dump | No | |
| Days the oldest outside issue waits for a reply | 0 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 14 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | No | |
| Published docs | Not measured | Yes | ||
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityNot measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | Not measured | Yes | ||
| RustSec unmaintained advisory | Not measured | Yes | ||
| Deprecation notice | Not measured | Yes | ||
| Deprecated requirement | Not measured | Yes |
Distribution4 releases, 5 downloads over 30 days6 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 4 | crates.io database dump | No | |
| Downloads over 30 days | 5 | crates.io database dump | No | |
| Binary downloads over the last 3 releases | 1274 | GitHub releases | Yes | |
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | true | crates.io database dump | Yes | |
| Every version 0.0.x | true | crates.io database dump | Yes | |
| Every version yanked | Not measured | Yes | ||
| Crate deleted from crates.io | Not measured | Yes |
Repository417 stars, 26 forks, 4 contributors, 86 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 417 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 26 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 4 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 86 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | GPU support unknown | crates.io database dump | No | |
| What shows each backend | no dependency or feature matches a backend row | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | No native code found | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | Not measured | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.