connector-x
Library Listed
Load data from databases to dataframes, the fastest way.
- Downloads
- 4,951
- Dependents
- 5
- Stars
- 2,659
- Forks
- 229
- Contributors
- 75
- Commits
- 2,324
- Latest release
- 0.4.6 ·
About
Load data from  to
 , the fastest way.
ConnectorX enables you to load data from databases into Python in the fastest and most memory efficient way.
What you need is one line of code:
import connectorx as cx

cx.read_sql("postgresql://username:password@server:port/database", "SELECT * FROM lineitem")
Optionally, you can accelerate the data loading using parallelism by specifying a partition column.
import connectorx as cx

cx.read_sql("postgresql://username:password@server:port/database", "SELECT * FROM lineitem", partition_on="l_orderkey", partition_num=10)
The function will partition the query by evenly splitting the specified column to the amount of partitions. ConnectorX will assign one thread for each partition to load and write data in parallel. Currently, we support partitioning on numerical columns (cannot contain NULL) for SPJA queries.
Experimental: We are now providing federated query support, you can write a single query to join tables from two or more databases!
Read the full README
import connectorx as cx
db1 = "postgresql://username1:password1@server1:port1/database1"
db2 = "postgresql://username2:password2@server2:port2/database2"
cx.read_sql({"db1": db1, "db2": db2}, "SELECT * FROM db1.nation n, db2.region r where n.n_regionkey = r.r_regionkey")
By default, we pushdown all joins from the same data source. More details for setup and configuration can be found here.
Check out more detailed usage and examples here. A general introduction of the project can be found in this blog post.
Installation
pip install connectorx
Check out here to see how to build python wheel from source.
Performance
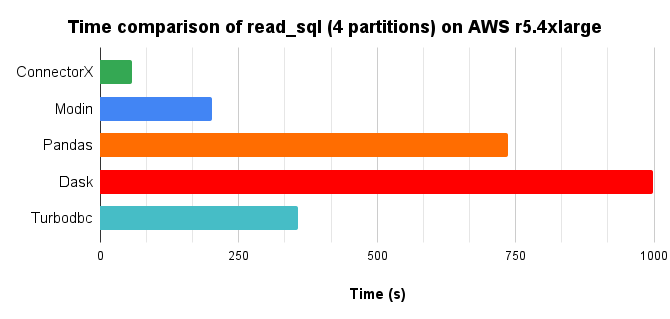
We compared different solutions in Python that provides the read_sql function, by loading a 10x TPC-H lineitem table (8.6GB) from Postgres into a DataFrame, with 4 cores parallelism.
Time chart, lower is better.
Memory consumption chart, lower is better.
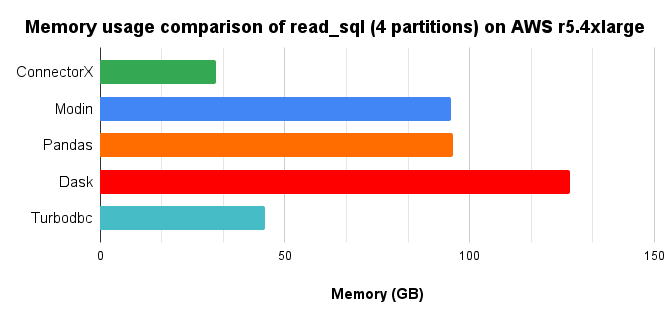
In conclusion, ConnectorX uses up to 3x less memory and 21x less time (3x less memory and 13x less time compared with Pandas.). More on here.
How does ConnectorX achieve a lightning speed while keeping the memory footprint low?
We observe that existing solutions more or less do data copy multiple times when downloading the data. Additionally, implementing a data intensive application in Python brings additional cost.
ConnectorX is written in Rust and follows "zero-copy" principle. This allows it to make full use of the CPU by becoming cache and branch predictor friendly. Moreover, the architecture of ConnectorX ensures the data will be copied exactly once, directly from the source to the destination.
How does ConnectorX download the data?
Upon receiving the query, e.g. SELECT * FROM lineitem, ConnectorX will first get the schema of the result set. Depending on the data source, this process may involve issuing a LIMIT 0 query SELECT * FROM lineitem LIMIT 0.
Then, if partition_on is specified, ConnectorX will issue SELECT MIN($partition_on), MAX($partition_on) FROM (SELECT * FROM lineitem) to know the range of the partition column.
After that, the original query is split into partitions based on the min/max information, e.g. SELECT * FROM (SELECT * FROM lineitem) WHERE $partition_on > 0 AND $partition_on < 10000.
ConnectorX will then run a count query to get the partition size (e.g. SELECT COUNT(*) FROM (SELECT * FROM lineitem) WHERE $partition_on > 0 AND $partition_on < 10000). If the partition
is not specified, the count query will be SELECT COUNT(*) FROM (SELECT * FROM lineitem).
Finally, ConnectorX will use the schema info as well as the count info to allocate memory and download data by executing the queries normally.
Once the downloading begins, there will be one thread for each partition so that the data are downloaded in parallel at the partition level. The thread will issue the query of the corresponding partition to the database and then write the returned data to the destination row-wise or column-wise (depends on the database) in a streaming fashion.
Supported Sources & Destinations
Example connection string, supported protocols and data types for each data source can be found here.
For more planned data sources, please check out our discussion.
Sources
- [x] Postgres
- [x] Mysql
- [x] Mariadb (through mysql protocol)
- [x] Sqlite
- [x] Redshift (through postgres protocol)
- [x] Clickhouse
- [x] SQL Server
- [x] Azure SQL Database (through mssql protocol)
- [x] Oracle
- [x] Big Query
- [x] Trino
- [ ] ODBC (WIP)
- [ ] ...
Destinations
- [x] Pandas
- [x] PyArrow
- [x] Modin (through Pandas)
- [x] Dask (through Pandas)
- [x] Polars (through PyArrow)
Documentation
Doc: https://sfu-db.github.io/connector-x/intro.html Rust docs: stable nightly
Next Plan
Checkout our discussion to participate in deciding our next plan!
Historical Benchmark Results
https://sfu-db.github.io/connector-x/dev/bench/
Developer's Guide
Please see Developer's Guide for information about developing ConnectorX.
Supports
You are always welcomed to:
- Ask questions & propose new ideas in our github discussion.
- Ask questions in stackoverflow. Make sure to have #connectorx attached.
Organizations and Projects using ConnectorX

To add your project/organization here, reply our post here
Citing ConnectorX
If you use ConnectorX, please consider citing the following paper:
Xiaoying Wang, Weiyuan Wu, Jinze Wu, Yizhou Chen, Nick Zrymiak, Changbo Qu, Lampros Flokas, George Chow, Jiannan Wang, Tianzheng Wang, Eugene Wu, Qingqing Zhou. ConnectorX: Accelerating Data Loading From Databases to Dataframes. VLDB 2022.
BibTeX entry:
@article{connectorx2022,
  author    = {Xiaoying Wang and Weiyuan Wu and Jinze Wu and Yizhou Chen and Nick Zrymiak and Changbo Qu and Lampros Flokas and George Chow and Jiannan Wang and Tianzheng Wang and Eugene Wu and Qingqing Zhou},
  title     = {ConnectorX: Accelerating Data Loading From Databases to Dataframes},
  journal   = {Proc. {VLDB} Endow.},
  volume    = {15},
  number    = {11},
  pages     = {2994--3003},
  year      = {2022},
  url       = {https://www.vldb.org/pvldb/vol15/p2994-wang.pdf},
}
Contributors
Compatibility
- Runs on
- GPU support unknown
What shows it
- no dependency or feature matches a backend row
- Native code
- Optional
- Binds native code: libsqlite3-sys (feature src_sqlite), odpic-sys (feature src_oracle), openssl-sys (feature src_postgres)
- Python bindings
- No Python binding crate found
- License
- MIT
Compare with similar projects
Order: strongest tier first, then most downloads, then name, with unmeasured values last. A library counts downloads over 30 days. An app counts binary downloads per release. An app with none counts its crate downloads over 30 days. ML Rust runs this catalogue, so its closest project always gets a row.
| Project | Downloads | Dependents | Stars | Latest release | Runs on (GPU) | Native code | License |
|---|---|---|---|---|---|---|---|
|
Load data from databases to dataframes, the fastest way. |
4,951 downloads over 30 days | 5 | 2,659 | 0.4.6 | GPU support unknown | Binds native code: libsqlite3-sys (feature src_sqlite), odpic-sys (feature src_oracle), openssl-sys (feature src_postgres) | MIT |
|
datafusion Featured
DataFusion is an in-memory query engine that uses Apache Arrow as the memory model |
2,992,524 downloads over 30 days | 484 | 9,578 | 55.2.0 | GPU support unknown | Binds native code: libmimalloc-sys, liblzma-sys (feature compression), zstd-sys (feature compression) | Apache-2.0 |
|
vortex Listed
An extensible, state-of-the-art framework for columnar compression, and the fastest FOSS columnar file format. Formerly at @spiraldb, now an Incubation Stage project at LFAI&Data, part of the Linux Foundation. |
98,129 downloads over 30 days | 32 | 3,310 | 0.93.0 | GPU support unknown | Binds native code: zstd-sys | Apache-2.0 |
|
ndarray-csv Listed
Easily read and write homogeneous CSV data to and from 2D ndarrays |
23,808 downloads over 30 days | 7 | 20 | 0.5.4 | GPU support unknown | No native code found | Apache-2.0 OR MIT |
|
Data Agent Ready Warehouse : One for Analytics, Search, AI, Python Sandbox. — rebuilt from scratch. Unified architecture on your S3. |
48 binary downloads per release | Not applicable | 9,493 | Not measured | Not measured | Apache-2.0 | |
|
elusion Listed
Elusion is a modern DataFrame / Data Engineering / Data Analysis library that combines the familiarity of DataFrame operations (like those in PySpark, Pandas, and Polars) with the power of SQL query building. |
27 downloads over 30 days | 0 | 144 | 9.0.0 | GPU support unknown | Binds native code: ring, openssl-sys | MIT |
|
Model conversion and quantization with no Python: reads SafeTensors, GGUF, TCF and PyTorch state dicts, writes SafeTensors, GGUF and TCF, and quantizes to Q2_K through Q8_0 and IQ4 formats, including Q4_K_M mixes. GPTQ, AWQ, NF4, FP8, EXL2 and ONNX input are not implemented. Python bindings |
23 downloads over 30 days | Not applicable | 0 | 0.2.1 | GPU support unknown | No native code found | Apache-2.0 |
Why ListedNo archive, New or Featured rule places it, so it is Listed.
What it lacks for Featured
- It has 4 active dependents and 4 new dependents in 365 days. Featured needs 11 active dependents or 9 new dependents in 365 days. The repository route reads 2,659 stars, 229 forks and 75 contributors. It needs 4,539 stars, 434 forks and 79 contributors together.
What else the check found
- The last activity is on 8 Nov 2026, 1 day ago. The rules expect an update within 450 days. Dormancy rule
- The latest release requires the deprecated dependency fehler. RUSTSEC-2023-0067 Rot signals rule
Exact rules: Listed, Featured library. The check on applied thresholds version 9.
Every rule outcome, as the check records it
expected-interval: version 0.4.6 base 450: E = 450 daysdormancy: last activity 2026-11-08, 1 days ago, E = 450: activerot: deprecated requirement `fehler (RUSTSEC-2023-0067, https://rustsec.org/advisories/RUSTSEC-2023-0067.html)`featured: not featured: active_users 4 < 11 and new_adopters 4 < 9 and repository route stars 2659 (needs 4539), forks 229 (needs 434), contributors 75 (needs 79)listed: listed: no archive, new or featured rule applies
Measurements and sources
Each signal row shows the raw value, its source and the fetch date. The Sources list gathers every distinct source on this page. Movement needs more history.
Sources6 sources
- Description: the crates.io description
- crates.io database dump, fetched
- RustSec advisory database, fetched
- GitHub repository, fetched
- crates.io package, fetched
- GitHub contributors, fetched
Adoption4 active dependents, 4 new dependents in 365 days1 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Active dependents | 4 | crates.io database dump | Yes | |
| New dependents (365 days) | 4 | crates.io database dump | Yes | |
| Peak active dependents | 4 | crates.io database dump | Yes | |
| Active dependents as a share of the peak | 1 | crates.io database dump | Yes | |
| Binary downloads per release | Not measured | Yes |
MaintenanceLatest human commit: 1 day ago3 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Latest human commit | 2026-11-08 | GitHub repository | Yes | |
| Latest release | 2026-09-18 | crates.io database dump | Yes | |
| First release | 2021-07-25 | crates.io database dump | Yes | |
| Latest version | 0.4.6 | crates.io database dump | Yes | |
| Days the oldest outside issue waits for a reply | 359 | GitHub repository | Yes | |
| Maintainer replies over 365 days | 31 | GitHub repository | Yes | |
| Repository archived | false | GitHub repository | Yes | |
| Repository gone | false | GitHub repository | Yes | |
| Release commit or manifest in the repo | true | crates.io package | Yes | |
| Published docs | true | crates.io database dump | Yes | |
| Latest release fails cargo check | Not measured | Yes | ||
| Build check date | Not measured | Yes | ||
| Build check toolchain | Not measured | Yes |
SecurityUnpatched vulnerabilities: none
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Unpatched vulnerabilities past the grace window | none | RustSec advisory database | Yes | |
| RustSec unmaintained advisory | none | RustSec advisory database | Yes | |
| Deprecation notice | none | crates.io database dump | Yes | |
| Deprecated requirement | fehler (RUSTSEC-2023-0067, https://rustsec.org/advisories/RUSTSEC-2023-0067.html) | crates.io database dump | Yes |
Distribution23 releases, 4,951 downloads over 30 days5 not measured
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| Releases | 23 | crates.io database dump | Yes | |
| Downloads over 30 days | 4951 | crates.io database dump | Yes | |
| Binary downloads over the last 3 releases | Not measured | Yes | ||
| Homebrew installs on request over 365 days | Not measured | Yes | ||
| Repology repository families | Not measured | Yes | ||
| Docker pull growth over 90 days | Not measured | Yes | ||
| Docker pulls at the growth baseline | Not measured | Yes | ||
| Every version a prerelease | false | crates.io database dump | Yes | |
| Every version 0.0.x | false | crates.io database dump | Yes | |
| Every version yanked | false | crates.io database dump | Yes | |
| Crate deleted from crates.io | false | crates.io database dump | Yes |
Repository2,659 stars, 229 forks, 75 contributors, 2,324 commits. Stars alone never qualify a project.
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| GitHub stars | 2659 | GitHub repository | Yes — one part of the repository route | |
| GitHub forks | 229 | GitHub repository | Yes — one part of the repository route | |
| Contributors with a GitHub account | 75 | GitHub contributors | Yes — one part of the repository route | |
| Commits on the default branch | 2324 | GitHub repository | No | |
| Repository's main crate left out of the entry | none | crates.io database dump | Yes |
Facts that never count
| Signal | Value | Source | Fetched | Counts |
|---|---|---|---|---|
| License | MIT | crates.io database dump | No | |
| Runs on, from listed crates and their direct dependencies | GPU support unknown | crates.io database dump | No | |
| What shows each backend | no dependency or feature matches a backend row | crates.io database dump | No | |
| Native code, from listed crates and their dependencies | Binds native code: libsqlite3-sys (feature src_sqlite), odpic-sys (feature src_oracle), openssl-sys (feature src_postgres) | crates.io database dump | No | |
| Python bindings, from direct dependencies of listed crates | No Python binding crate found | crates.io database dump | No | |
| Crates that depend on a listed crate directly | 5 | crates.io database dump | No |
Corrections and review history
No correction applies to this entry.
Judgments
A judgment enters only through an approved issue and a merged pull request.
No judgment applies to this entry.